Google's New RSI Paper: Featuring Built-in Memory and Autonomous Iteration
Reported by Zhidx on November 19, the research teams from Google Cloud AI, Google DeepMind and the Pennsylvania State University recently jointly published the paper *Self-Improvement Memory Enables Continual Recursive Self-Improvement*, proposing a new method named Self-Improvement Memory (SIM).
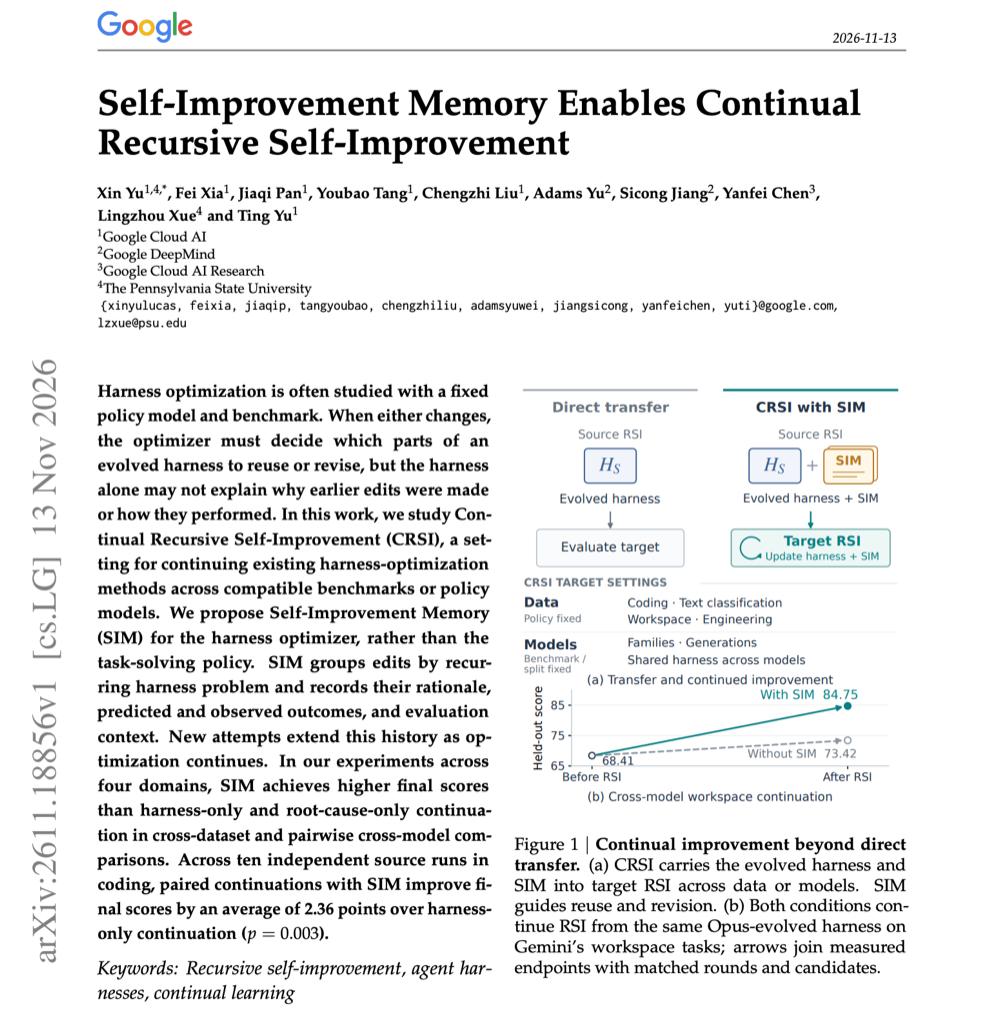
▲*Self-Improvement Memory Enables Continual Recursive Self-Improvement*
Previously, although AI could independently optimize the external operation framework (Harness) outside large models, re-optimization was often required after replacing the model or task. For the first time, SIM organizes the reasons behind code modifications, expected effects and actual results into continuously updatable memory, enabling AI to inherit and adjust past improvement experience, and achieve cross-model and cross-task Continual Recursive Self-Improvement (CRSI).
Subsequently, the research team conducted tests in four fields: programming, text classification, office tasks and engineering design. In 10 independent controlled programming experiments, the scheme with SIM introduced performed better in 9 groups, leading by an average of 2.36 points. In another cross-model office task test, the final score of the scheme with SIM introduced reached 84.75 points, while the scheme without SIM only got 73.42 points, a gap of 11.33 points.
Xin Yu, the first author of this study, graduated from Nankai University with a major in Statistics in 2023, and is currently pursuing his doctorate in Statistics at the Pennsylvania State University in the United States. This study was completed during his internship at Google.
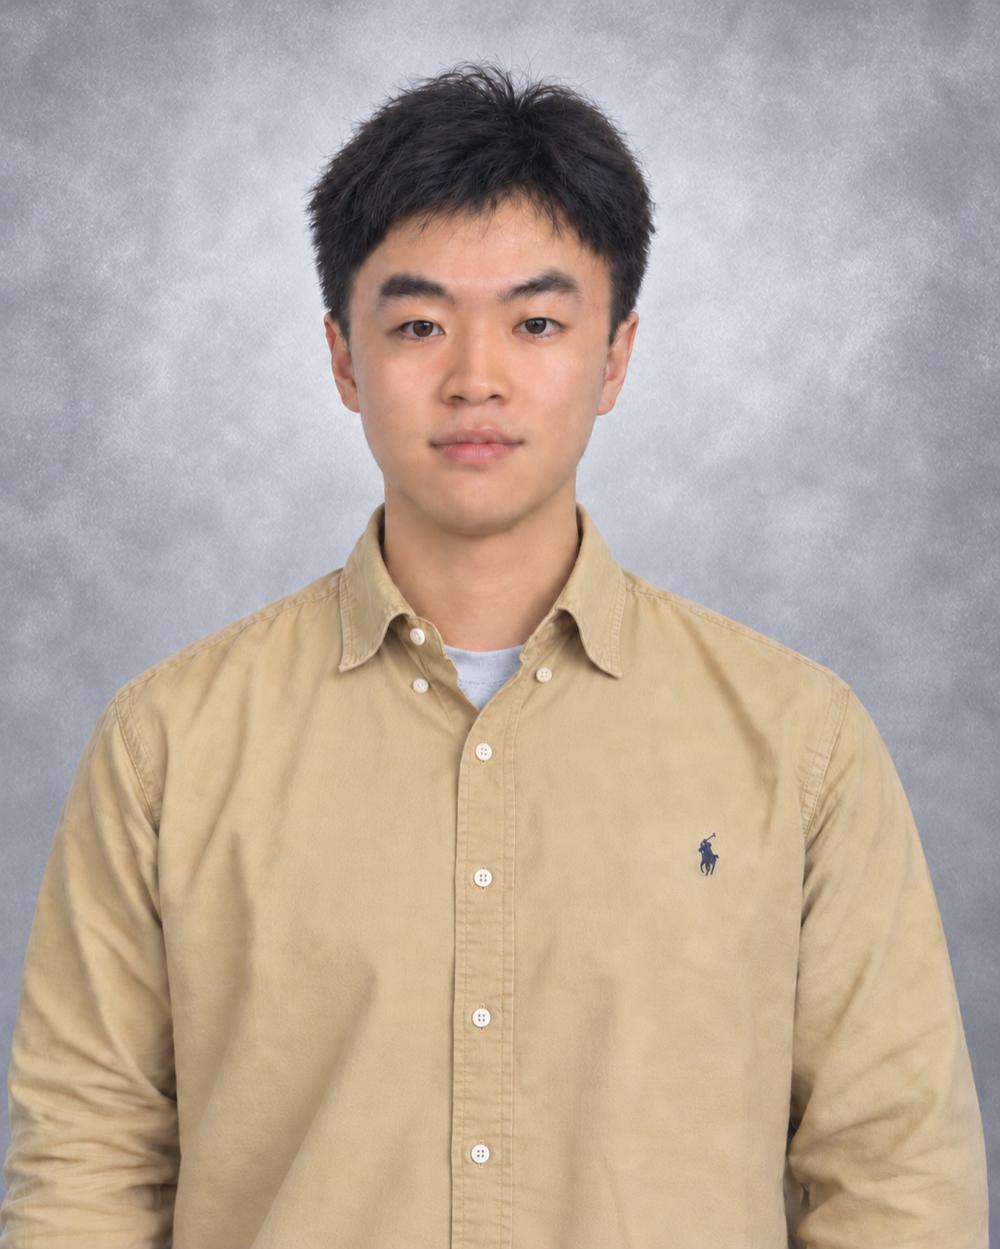
▲Xin Yu
Xin Yu has interned at Microsoft Research Asia, ByteDance Seed, TikTok and Meta, and won the 2023 "Star of Tomorrow" award from Microsoft Research Asia. Many of his co-authored research papers have been published in top international artificial intelligence academic conferences such as ICML, ICLR and NeurIPS.
Adams Wei Yu, another author of the paper, is a researcher at Google DeepMind, who has participated in projects including Gemini, Bard and Veo, the AI video generation model.
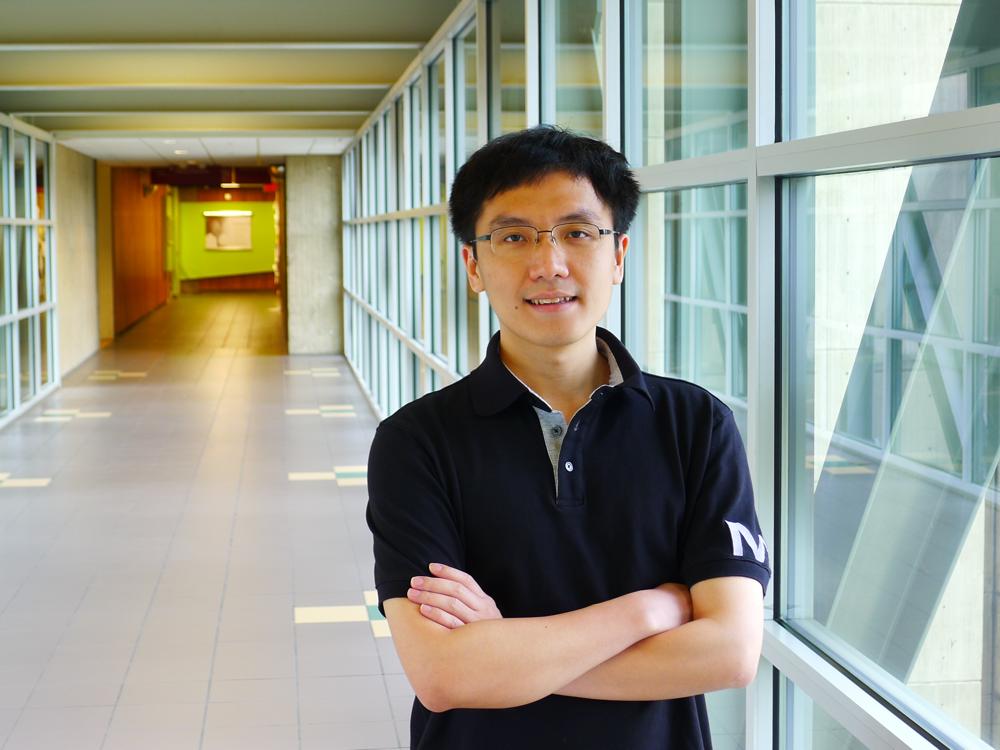
▲Adams Wei Yu
After the paper was released, Xin Yu introduced the starting point of this work on X. He mentioned that past research on recursive self-improvement usually targeted fixed large models and test tasks, but real-world Agents need to continuously adapt to new tasks, datasets and models. Therefore, the research team hopes that the optimization experience of AI can continue to accumulate as the environment changes.
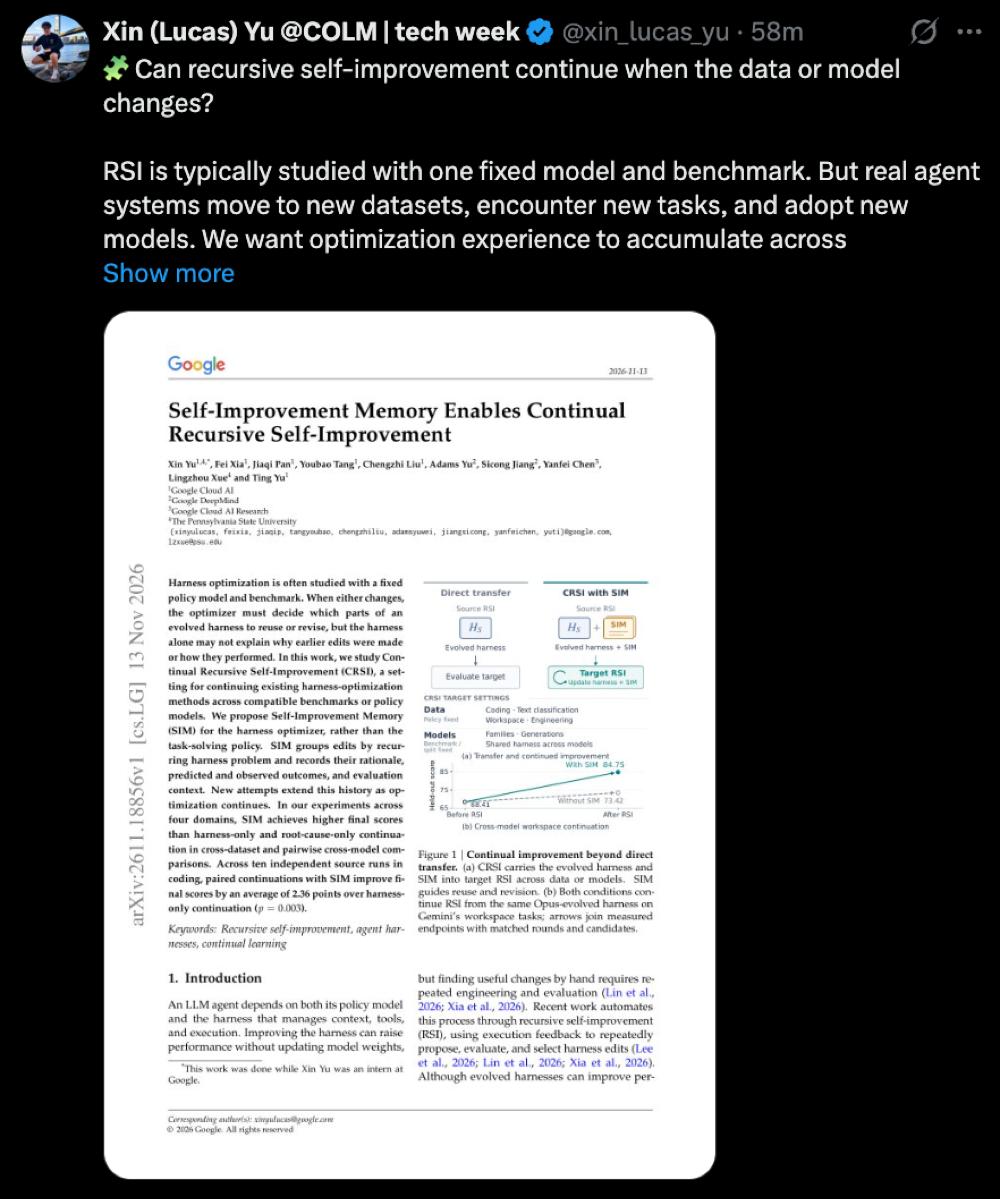
▲Xin Yu's post on X
"What carries forward should include the experience behind the code—not just the code itself," Xin Yu wrote.
Paper link: https://arxiv.org/abs/2611.18856
01.
AI Can Modify Code on Its Own
And Remember the Success or Failure of Each Improvement
Recursive Self-Improvement (RSI) refers to enabling AI to participate in improving AI systems and improve performance through repeated iterations. In this study, the object of AI improvement is not the large model itself, but a set of external programs running around the large model — Harness.
Harness is responsible for managing prompts, context, tool calls and task execution processes, etc. For example, when AI is assigned a programming task, Harness can decide when to call the terminal, how to check the code running results, and under what conditions the task can be declared completed.
Through RSI, AI can independently modify the Harness code, repeatedly test the modification effects, and retain the version with better performance, so as to improve the task completion rate of the Agent without updating the weights of the large model.
However, this type of optimization is usually targeted at fixed models and tasks. A set of Harness optimized for Claude may not remain effective after being replaced with Gemini; the rules previously designed for programming tasks may also not apply to new tasks.
More importantly, although the modified Harness retains the code, it does not necessarily retain the reasons behind each modification and the testing experience. When the model or task changes, the AI responsible for optimization may repeat previous attempts and even delete originally valid functions.
To this end, the research team proposed Continual Recursive Self-Improvement (CRSI), hoping that the automatic optimization of Harness can be continued across models and tasks, and previous improvement experience can be saved through SIM. SIM is like an "experimental record book" that records each adopted modification scheme, modification reason, expected result, actual effect, as well as the corresponding model and test environment.
When a new task or model appears, the AI responsible for optimizing Harness can refer to these records to judge which rules should be retained, modified or removed, without having to start from scratch.
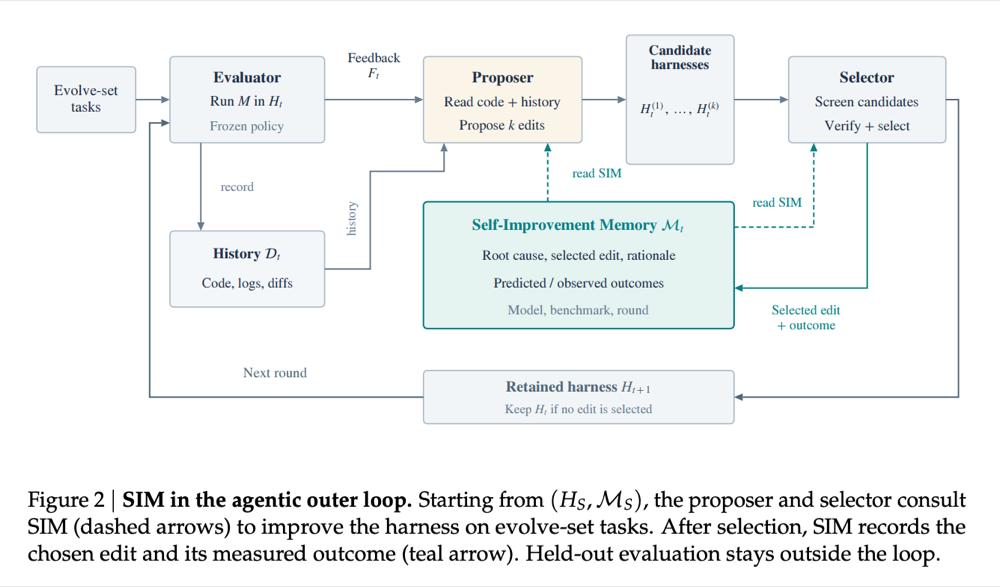
▲SIM Workflow
Specifically, the AI responsible for proposing schemes in the system will read the current code, execution feedback and SIM records to generate new modification schemes; the AI responsible for screening will check the candidate schemes and decide whether to adopt them combined with the test results.
Subsequently, the system will write the adopted modification and its actual effect into SIM. Even if the modification does not meet expectations, the failure result will be retained for subsequent optimization reference.
In a Git server configuration task, AI declared the task completed in advance because the local test was successful, but missed the key step of creating the specified user account, leading to the failure of external verification. Through automatic optimization, the researchers added a task completion check mechanism to the operation framework to prevent AI from ending the task in advance when there is a lack of execution evidence.
When the test was switched to the optical waveguide routing task, a new problem arose: although the routing path generated by AI met the constraint conditions, it did not mean that the routing cost was low enough. Therefore, the subsequent optimization retained the previous check mechanism, and at the same time added a check reminder for the quality of the scheme to prevent AI from ending the task only after passing the basic constraint check.
This is exactly the effect SIM hopes to achieve: enabling AI not only to follow past effective improvement methods, but also to continue adjusting according to the requirements of new tasks.
02.
9 out of 10 Programming Experiments Benefit from SIM
Up to 11.33 Points Higher in Cross-Model Tests
To verify the effect of SIM, the research team carried out two main types of experiments: one kept the underlying model unchanged and replaced the task data; the other kept the test task unchanged and replaced the underlying model.
In the first type of experiment, the researchers used Gemini 3.8 Flash as the underlying model, and migrated the optimized operation framework to new tasks.
As a result, in 6 groups of tests covering programming, text classification, office tasks and engineering design, the scheme with complete SIM introduced obtained the highest final score, leading 2.43 to 4.35 points compared with the scheme that only used the original operation framework.
The second type of experiment involves migration between different models. The researchers first optimized a set of Harness for Claude Opus 5.5, then let Gemini 3.8 Flash use this set of Harness and continue to carry out automatic optimization.
It was found that after directly migrating the Harness applicable to Claude to Gemini, its initial performance in the 4 test fields was worse than the performance when Gemini used the original Harness.
However, after introducing SIM, the AI responsible for optimization can refer to previous modification experience to adjust the parts that are not suitable for Gemini. Finally, the SIM scheme obtained the highest score in all 4 fields, leading 3.60 to 11.33 points compared with the scheme without SIM.
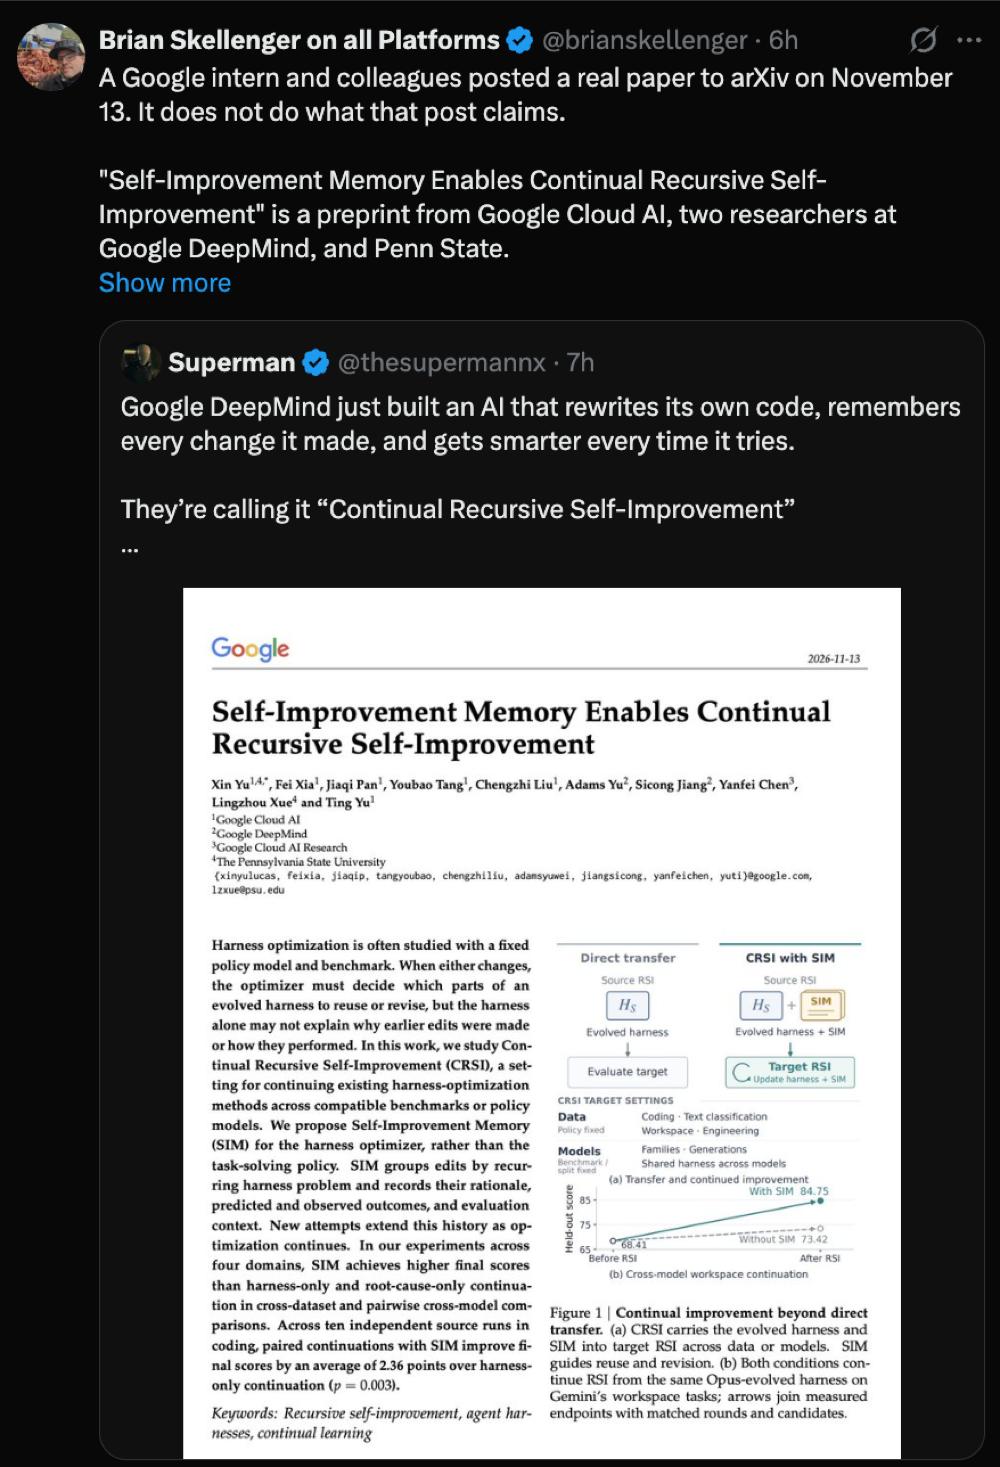
The largest gap appears in the office task test. Both schemes started from 68.41 points. The scheme with SIM introduced finally reached 84.75 points, while the scheme without SIM got 73.42 points.
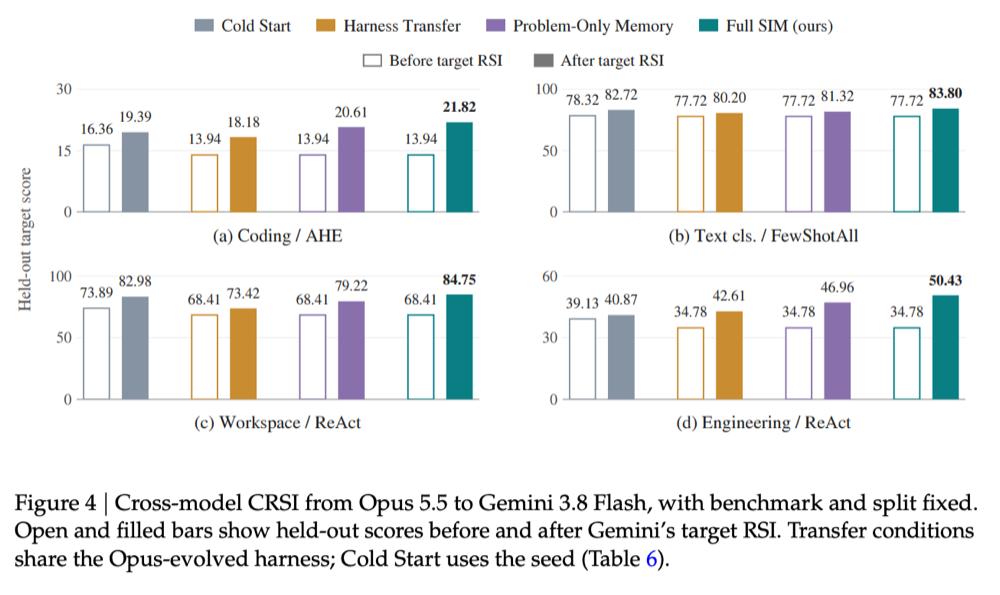
▲Cross-Model Test Results
To further verify the effect, the researchers also conducted 10 independent controlled programming experiments.
With the same initial code, underlying model, task and optimization budget, 9 groups of the schemes added with SIM got higher scores, with an average final score of 21.70 points, while the average score of the schemes without SIM was 19.33 points. The average difference between the two was 2.36 points, and the statistical test result was p=0.003.
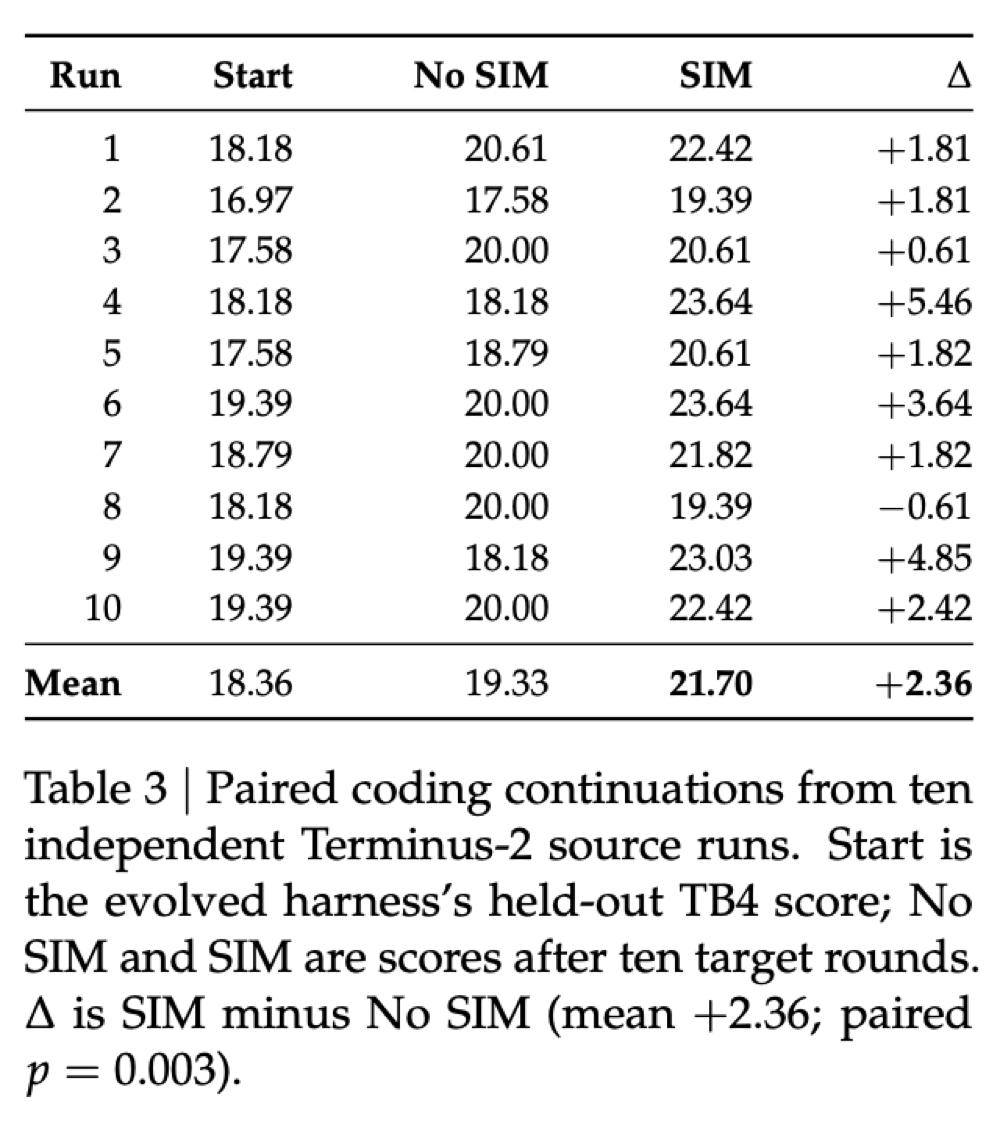
▲Results of 10 Groups of Controlled Programming Experiments
The research team also tried to make this set of operation framework and its memory adapt to Gemini 2.5 Flash, Gemini 3.5 Flash, Gemini 3.8 Flash and Gemini 4 Argon in turn.
Compared with the optimization from scratch for each generation of model, the scheme that inherited historical experience led by 3.5 points and 1.6 points on Gemini 3.5 Flash and Gemini 3.8 Flash respectively. However, on Gemini 4 Argon, the final score of the scheme that inherited experience was 0.8 points lower than the other.
This shows that although historical experience helps AI to continue optimization across models, it does not guarantee that every migration can achieve better results.
03.
Can AI Achieve Continuous Self-Evolution?
The Model Weights Remain Unchanged
This study also sparked discussions on X. Superman, a tech blogger, believes that in the past, when AI tried to improve itself, it was easy to forget previous successful experience, repeat mistakes, or fall into ineffective modification loops.
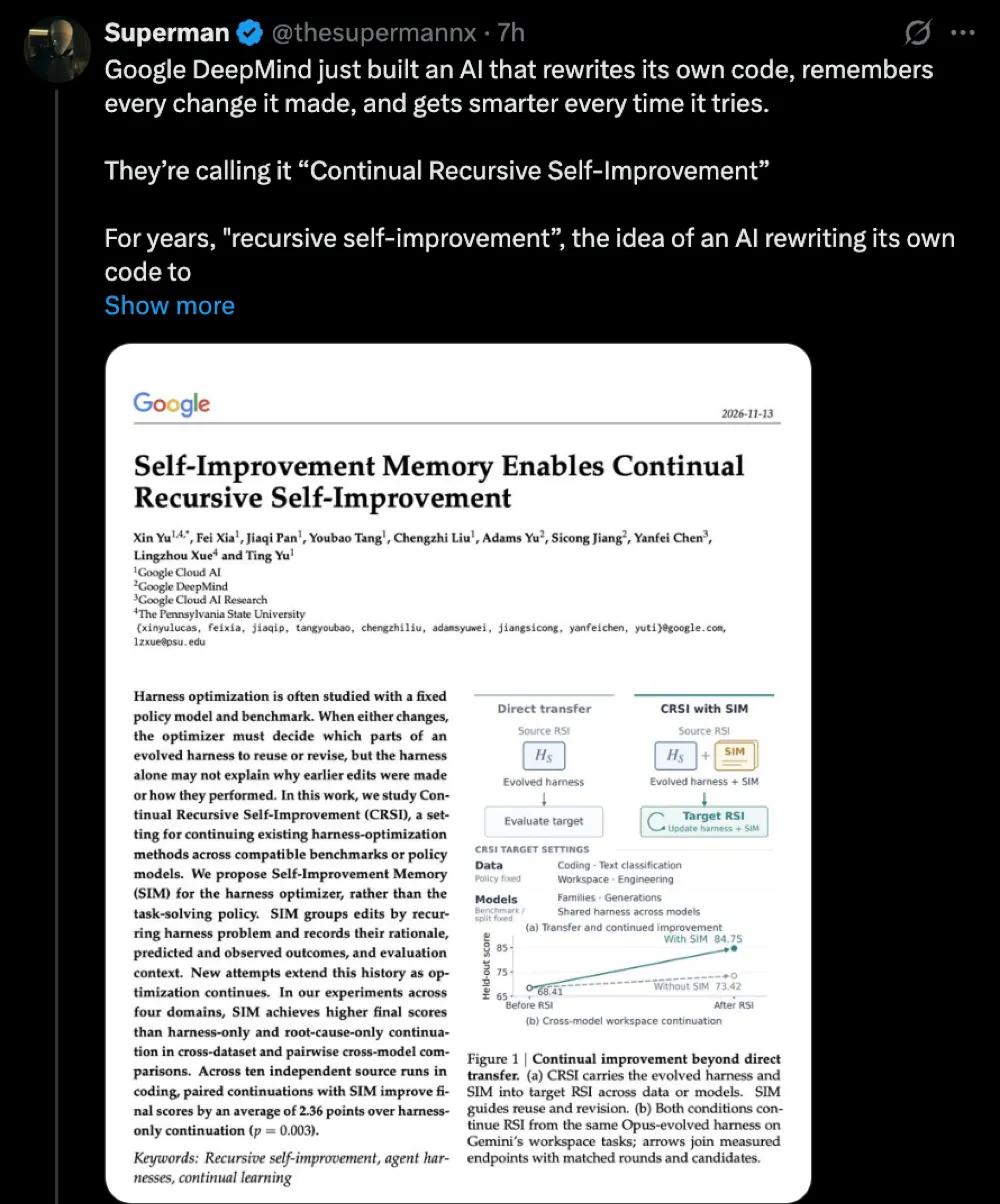
The emergence of SIM allows AI to review past modification records, understand which schemes are effective and which ones fail, so as to continue optimizing on the basis of previous achievements.
In his view, this gives AI the opportunity to achieve continuous recursive self-improvement by continuously accumulating experience.
This understanding has something in common with the problem the paper aims to solve, but part of the experiments in the paper shows that the claim that AI can continuously improve its own intelligence level needs to be considered in combination with the scope of the experiment.
Another developer Brian Skellenger reminded that although the AI in this study can independently modify the code and continuously optimize through test feedback, what it modifies is the external operation framework of the large model, not the architecture or parameters of the model itself. The paper also clearly mentions that the weights of the large model in the experiment always remain unchanged.
In general, the progress of this study lies in enabling AI to accumulate and reuse previous optimization experience. In addition to saving the modified code, the system also records the reason, expected effect and actual result of each modification, so that these experiences can continue to be utilized after replacing tasks or models.
As Xin Yu, the first author of the paper, said, what AI systems need to accumulate is not only the optimization results, but also the process of getting these results.
04.
Conclusion: Recursive Self-Improvement of AI
Moving Towards Continuous Evolution
In the past, Recursive Self-Improvement (RSI) enabled AI to optimize its own Harness by repeatedly modifying code and testing effects, but past optimization results were often difficult to continue across models and tasks. Now, SIM enables AI not only to inherit the modified code, but also