Yang Zhexuan Talks About Data Compilation, Model Capabilities and How Robots Re-enter the Real World
▲ From a porcelain cup to reusable data assets — compilation takes place after every operation.
Several teacups are placed on the table. The collector puts on the head-mounted device, picks up, moves away and puts the cups back in place one by one. The device records continuous video and Inertial Measurement Unit (IMU) data. It seems that the movements have been fully preserved. But once the task is over, this experience usually comes to an end. It does not naturally turn into a capability that can be called up next time.
But in Yang Zhexuan's view, this is exactly where the problem lies: the movement being recorded is only the beginning of the matter. The video tells us what happened, but it does not tell the model what to do next. It lacks dynamics, intentions, spatial relationships, and the experience of how to recover after a failure. To turn the action of sorting teacups into reusable intelligence, the system also needs to split the task into steps, align them with structured language, and supplement hand posture, motion trajectory and action intention.
Yang Zhexuan's judgment is very clear: "In my judgment, language, specifically structured language, is the only thing that can be aligned." In his view, only by first writing the task into a structure that the model can understand, retrieve and reuse, can the actions in the physical world turn from one-time experiences into intelligence that can be called up next time.
▲ Several teacups are placed on the table. Recording the movements is just the beginning.
From an industry perspective, after embodied intelligence enters the stage of large-scale data, the collection volume grows rapidly, but the gap of high-quality data remains large. 36Kr cited industry consensus in May this year that training an embodied model with general generalization capabilities requires at least tens of millions of hours of data. By the beginning of 2026, the total amount of high-quality real physical interaction data worldwide is only about 500,000 hours, less than 1/20000 of the training data of large language models.
A live metaphor given by Yang Zhexuan is more straightforward: after purchasing 1000 hours of external data, only about 100 hours may be usable after screening. There is a gap between collection scale and effective supply that needs to be filled by engineering capabilities.
What Zhiyu Foundation wants to do is exactly to supplement this set of structures. The company positions itself between data collection and model training, and uses the Physical AI DBMS and physical causal model to compile multi-modal observations from real tasks into operable data assets that are trainable, evaluable, queryable and reusable. The larger goal is to make every action in the physical world a reusable intelligence, so that embodied intelligence can re-enter factories, shopping malls, homes and other real scenarios, and become a workforce that can undertake specific tasks.
Triple Misalignment Between Data and Model Learning Requirements
In Yang Zhexuan's view, data does not lose its value just because it has been "collected enough". Every step the model takes forward will expose new shortcomings, and the data demand will change accordingly. Just as exams keep coming up with new questions, the model will keep raising new questions after entering the real work link.
The real problem is that there are still many misalignments between existing data and models.
The most direct misalignment lies in the learning objects. The video records where the object is and what the hand does, but it may not include the object state changes, action consequences, operation sequence, failure recovery and contact relationship that the model needs to understand. Zhiyu Foundation internally summarizes the capabilities that the model needs to master at the operation level into ten categories. Yang Zhexuan believes that models are generally deficient in these aspects, and videos that only record pictures will not automatically give answers.
▲ The same experience is split into pictures, trajectories and contact relationships, but the three records are often not aligned.
The second misalignment occurs in the task distribution. Standardized collection sites are the easiest to expand: a 2000-square-meter site can arrange about 200 people, calculated at about 10 square meters per station. But after the model learns "how to pick up an object" here, it may still not know what to do when moving to a shopping mall, kitchen or factory. Yang Zhexuan said that such sites are easy to scale up, but it is difficult to provide scenario generalization.
The third misalignment comes from ontological differences. Humans and robots, as well as different robots, are different in body structure, action space and control methods. The reuse of human data on robots requires camera calibration, task Schema definition, action mapping and ontology adaptation. A study by Physical Intelligence last December also found that the transfer ability of human videos to robots will only appear when the pre-training data is sufficiently diverse in scenarios, tasks and ontologies.
▲ For the same cup, humans and machines do not see the exact same position.
This is also the direction that Zhiyu Foundation is focusing on and actively exploring: how to shorten the human-to-robot embodiment gap, so that the accumulated human movement experience can be understood, mapped and reused by different robots. If this gap can be narrowed, it will not only affect a certain task or a certain type of robot, but also change the efficiency of embodied intelligence in converting data scale into actual capabilities.
Yang Zhexuan's judgment is that up to now, one relatively certain thing is that scaling will continue to happen. Further down, the key is to find a steeper scaling slope, so that model capabilities can grow at a lower cost.
Therefore, the two types of data have different divisions of labor. Human first-person perspective data is easy to scale, and mainly serves the generalization of scenarios, tasks and actions in the pre-training stage; real machine data is closer to specific ontologies and execution feedback, and is suitable for post-training of specific tasks. Yang Zhexuan gave an example: if you want to further increase the success rate of a specific task, you must collect real machine data for post-training.
Subsequent changes such as the second formation of a robot model research team by OpenAI and the release of Fable 5.2 by Anthropic have not been made public. What Yang Zhexuan talked about at that time was not just a certain model or a certain release, but how language and data structures became the foundation of embodied intelligence. Later, the public actions of the industry emerged one after another. Looking back, that was more like an early industry prediction.
From an industry perspective, a report released by institutions such as the China Academy of Information and Communications Technology (CAICT) in August stated that by the end of June this year, more than 70 embodied intelligence training grounds had been built and put into use across China; however, the "Embodied Intelligence Development Report (2026)" released by CAICT and the Department of Electronic Engineering of Tsinghua University and other institutions in October also pointed out that embodied intelligence is still in the transition stage to pilot applications.
To judge whether data is effective, it depends on whether it can cover the capabilities that the model needs to learn; the collection duration itself does not constitute a criterion. What the industry needs to compete for has also shifted from collecting more to retaining parts with higher training value.
Data Compilation: From Observation Records to Operation-Level Assets
In Yang Zhexuan's view, the core difference between observation-level data and operation-level data lies in whether there is a structured system to align the data. What is missing is not more labels, but a set of languages that can place different signals in the same coordinate system. In his words: "In my judgment, language, specifically structured language, is the only thing that can be aligned." Therefore, Zhiyu Foundation chooses to organize tasks in structured language, and supplements information such as dynamics, spatial position and motion intention, and has built and applied a five-link data compilation pipeline accordingly.
Still take sorting teacups as an example. After entering the pipeline, the video first undergoes data quality inspection, and segments with dropped frames, IMU drift, blocked key actions or non-compliant operations will be screened out. Data produced by external service providers also needs to go through this process; then it enters the data base reconstruction, the system converts the recorded data that is easy to write into a self-developed intermediate format (IR) with balanced read and write performance, and unifies the time reference and spatial coordinates of multi-modal data.
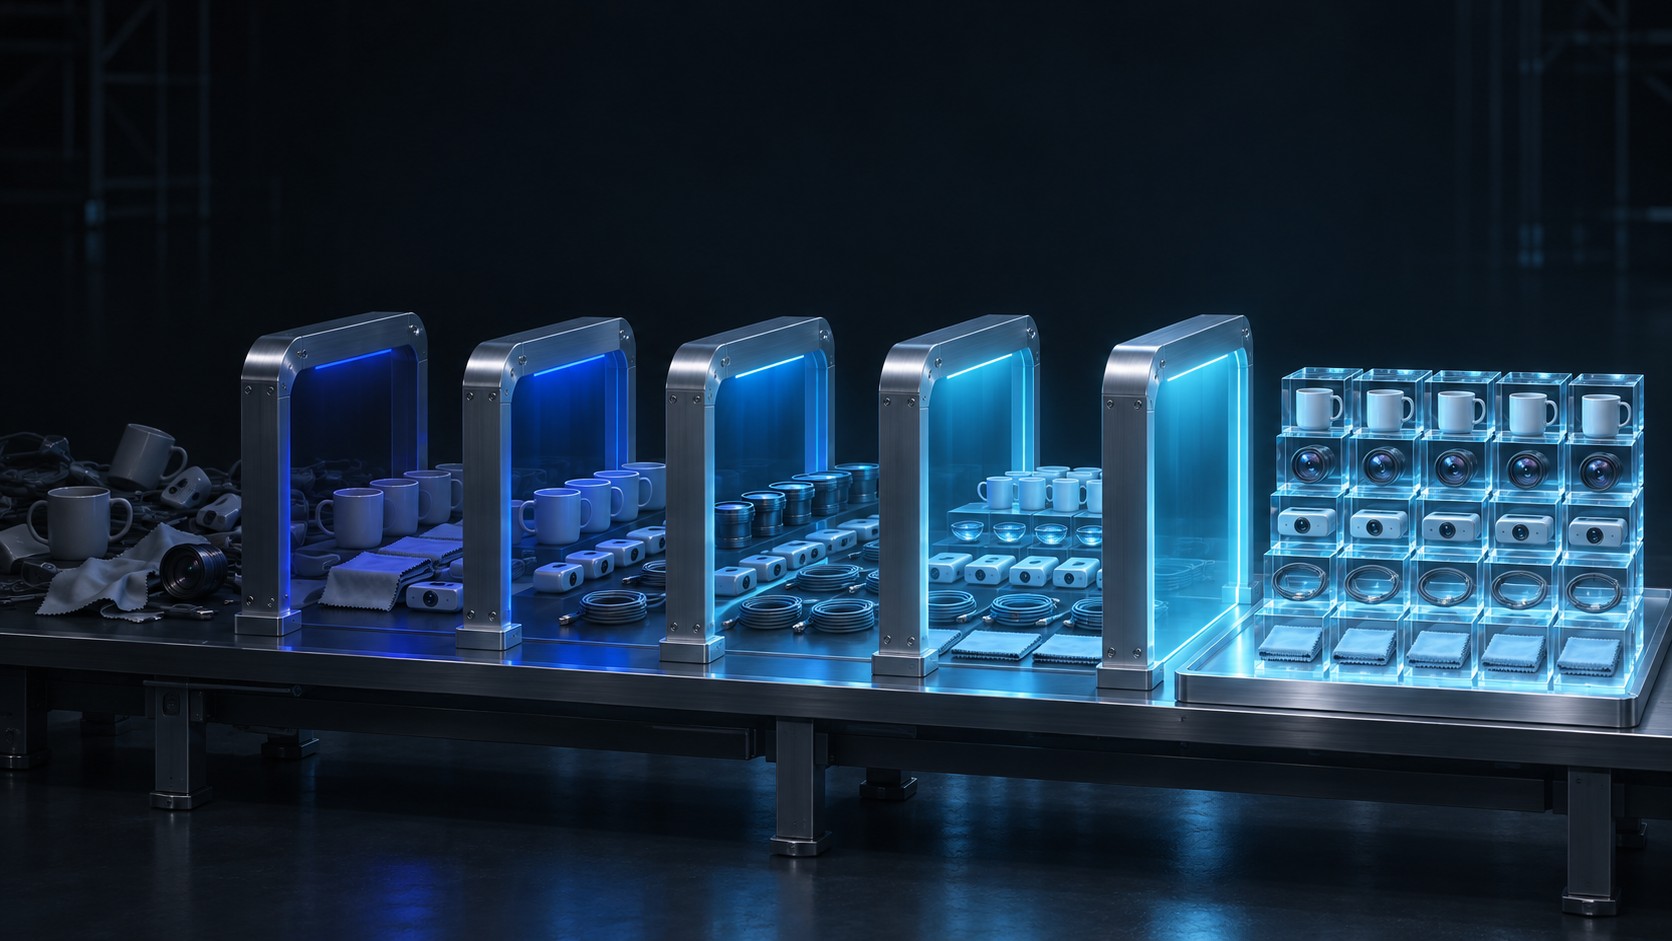
▲ Compilation pipeline: the left end is unorganized observations, and the right end is retrievable and deliverable data assets.
The other side of the manufacturing industry is quality inspection. Products need quality inspection before leaving the factory, and data also needs to pass the check before delivery. Yang Zhexuan said: "Automation cannot achieve unmanned operation in the whole process." Therefore, Zhiyu Foundation puts model-based automation, human-in-the-loop multi-level quality inspection and statistical sampling inspection on the same production line.
The next step is the core data compilation link. The task will be split into multiple steps and aligned with language, and hand posture, 6DoF pose, spatial trajectory, depth and motion intention will be restored and injected into the data. According to Zhiyu Foundation, the compiled data can be intelligently retrieved and grouped according to conditions such as scenarios, objects, and skills, and finally packaged and delivered in a standardized format according to customer needs.
Supporting this pipeline is a four-layer architecture composed of observation-level data input, Physical AI DBMS, physical causal model and operation-level data output.
Physical AI DBMS is the company's internal data base, responsible for heterogeneous data organization, indexing and version traceability. From Yang Zhexuan's background in database development, the operation of automatic quality inspection, annotation algorithms and physical causal models all rely on this base, otherwise the system cannot bear the workload. The physical causal model is responsible for understanding the task itself, including stage division, state change, physical contact, failure cause and recovery path, and finally outputs training data sets, benchmarks, scenario data packages, evaluation assets and reusable task templates.
The outside world often regards the data business as a labor-intensive industry, but Yang Zhexuan's judgment is: "Data is actually a manufacturing industry with high-tech attributes." In his view, labor intensity is a feature of this business, but it does not mean there are no barriers. The high-tech attributes can be reflected in hand posture generation and trajectory extraction. When the hand blocks important areas of the operation, information extraction is blocked and can only be restored by the model, which requires a large amount of unobstructed data for training and then verified by ground truth. "This job cannot be solved just by organizing a large number of people. You need to have computing power, data, and algorithm talents."
The manufacturing side is reflected in quality inspection. Products need quality inspection before leaving the factory, and the same is true for data before delivery, and automation cannot achieve a complete closed loop. "Many peers are claiming 100% automated annotation and quality inspection, which is impossible. If you can achieve that, it means the model no longer needs your data." Yang Zhexuan said. Therefore, Zhiyu Foundation combines automation with multi-level quality inspection and statistical sampling inspection.
It can be seen that data compilation is essentially a manufacturing industry with technical thresholds. It is not a simple cleaning or labeling, but uses database engineering, physical causal understanding, algorithms and quality control to stably process one-time observation records into data assets available for the model.
Capability Boundary of Data Compilation
After compilation, the original observation data is processed into trainable and evaluable operation-level data assets, but this does not mean that the data can directly drive the robot to perform tasks. Yang Zhexuan emphasized that the compiled data "has not yet reached the robot level" and is not a control instruction that can be directly issued to any robot. Different robots have certain differences in body structure, action space and control system, and the data still needs ontology adaptation before entering the training and application links of specific robots.
This also means that cross-ontology reuse is not directly copying the same data or action instructions to different robots. What can really be reused are more methods and experiences such as task definition, failure classification, observation rules, quality access control and recovery patterns. They can provide references for data production and training of different ontologies, but specific data processing and action mapping still need to be completed in combination with the characteristics of the robot itself.
In addition to ontological differences, the data source itself also determines its scope of application. Human first-person perspective data records the human operation process, which has the advantages of scenario and task diversity, and mainly supports the generalization ability in the pre-training stage; real machine data is closer to the specific robot ontology and its actual execution feedback, and is suitable for post-training around specific tasks. The two types of data correspond to different training needs and cannot be simply replaced by each other.
These technical boundaries also delineate the business boundaries of Zhiyu Foundation. The company does not take the R&D of robot ontologies and general basic models as its main business, but it is not completely unrelated to model training. The team will carry out small-scale pre-training to evaluate the effect of self-produced data, and at the same time use models with small parameter scales to maintain understanding of model requirements and verify new technical ideas.
"I think our company, including my career and my genes, will not do large-scale pre-training." Yang Zhexuan said. In contrast, he hopes that the company will focus on large-scale post-training in the future to help robots enter specific scenarios to complete real tasks.
For Zhiyu Foundation, the core work of data compilation is to convert the operation experience of the physical world into data assets that can be used by the model; as for how to make the model master these experiences and further convert them into the actual capabilities of the robot, links such as model R&D and ontology adaptation are still required to complete together.
From One-Time Collection to Continuous Real Task Supply
For data compilation to operate continuously, real tasks are needed continuously. Zhiyu Foundation put forward the concept of "Real Task Network" on its official website, hoping to connect industrial parks, robot enterprises, model teams and scientific research institutions, and connect task entrances, operating environments, robot ontologies and model requirements into the same data system.
At this stage, the company collects both real machine data and human first-person perspective data at the same time, with external service providers participating in production, and the internal team responsible for task definition, processing and acceptance. Yang Zhexuan believes that the difficulty of doing data is not how many people you hire, but whether you can define the task first from the perspective of model training, which is also the reason why the company insists on collecting real tasks and actions in real scenarios.
Hardware is another investment. Zhiyu Foundation has self-developed the ArcheGo series of wearable collection devices