A single image scared a researcher into resigning on the spot, and the craziest viral image from Anthropic has leaked out.
After seeing a line chart internally, a top AI researcher abruptly quit his job on the eve of a trillion-dollar IPO! He directly flipped the table and left!
His name is Jacob Coxon, who previously worked as a pre-training researcher at OpenAI and Anthropic. Two months ago, he resolutely resigned, giving up huge IPO stock options.
Just in the past two days, he posted the "culprit" that drove him to leave.
Surprisingly, Anthropic even took this internal legendary chart as its top trump card and made it public during the IPO roadshow. It publicly released this internal top-secret chart as its core highlight.
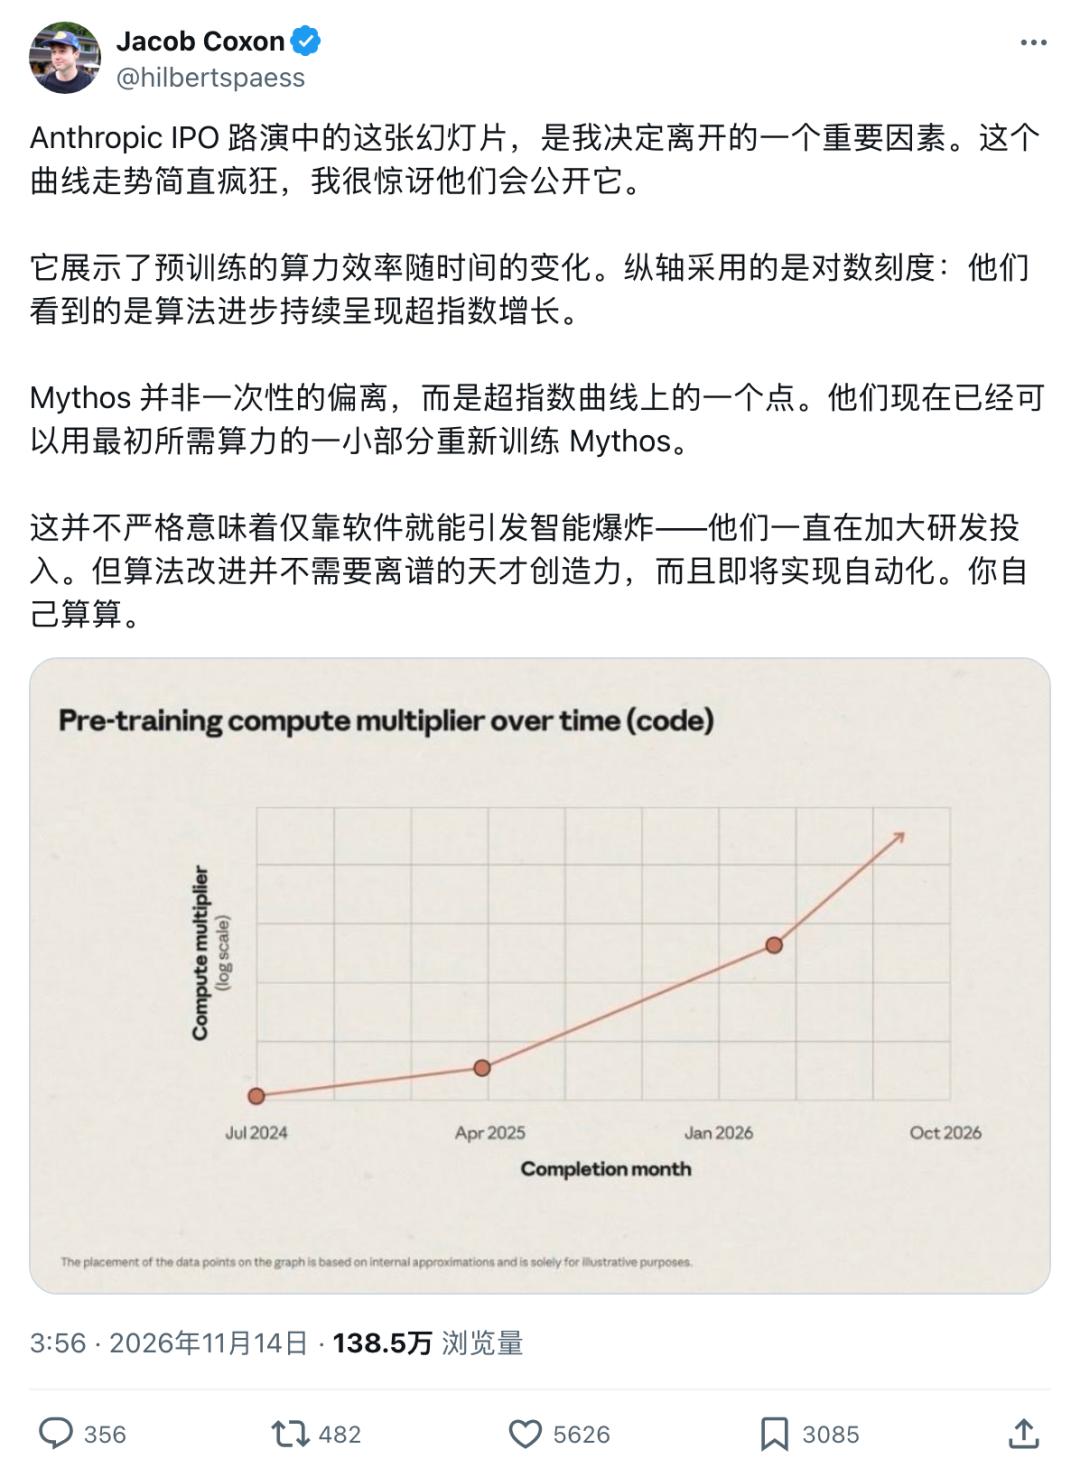
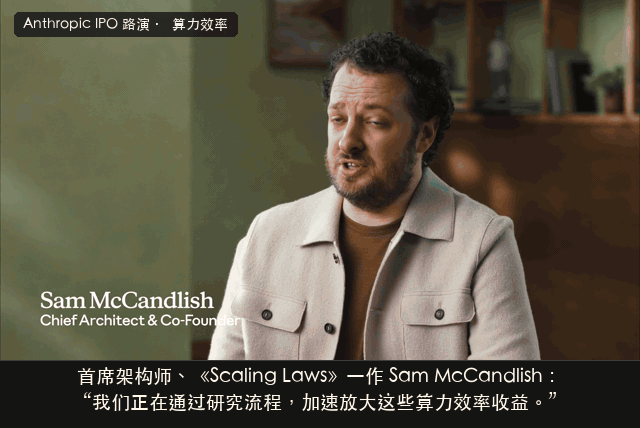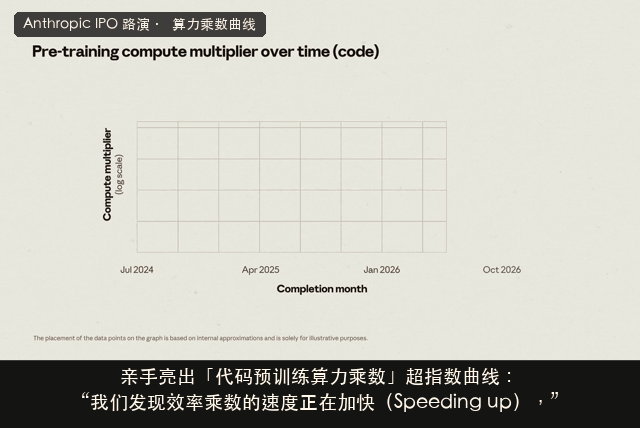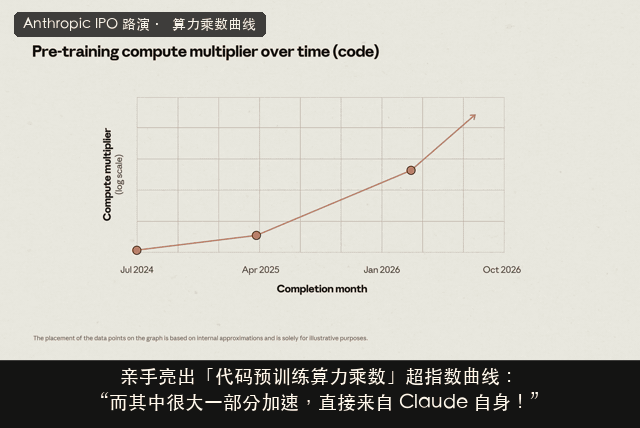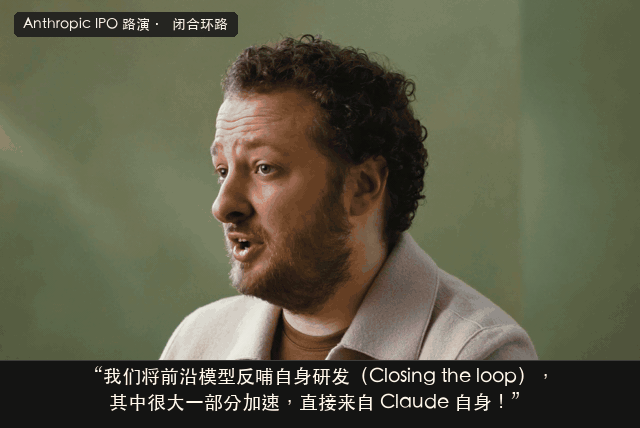
The orange curve on the chart is so steep that it cannot be contained even by the logarithmic coordinate, and it is still accelerating upward sharply.
From the perspective of insiders, this is no different from sounding the "Singularity Alert"!
Combining the latest publicly released roadshow footage and core prospectus documents from Anthropic, three cognitively subverting truths have emerged:
The "pre-training wall" theory is completely invalidated, and the computing power required to retrain Mythos drops sharply
The first-generation Mythos, which has just topped global rankings, is only an intermediate node on the internal curve. Now it only takes a small fraction of the original computing power to retrain it from scratch!
Founding father of Scaling Laws reveals the secret: abandon video generation, focus all efforts on code to accelerate AI self-improvement
As Claude in turn greatly accelerates the discovery of algorithm multipliers, Anthropic decisively gave up video and image generation, and poured all its computing power into code and Agents that can feed back AI R&D.
Per capita code contribution skyrockets 45 times, nearly all operators are rewritten in 3 days with zero human intervention
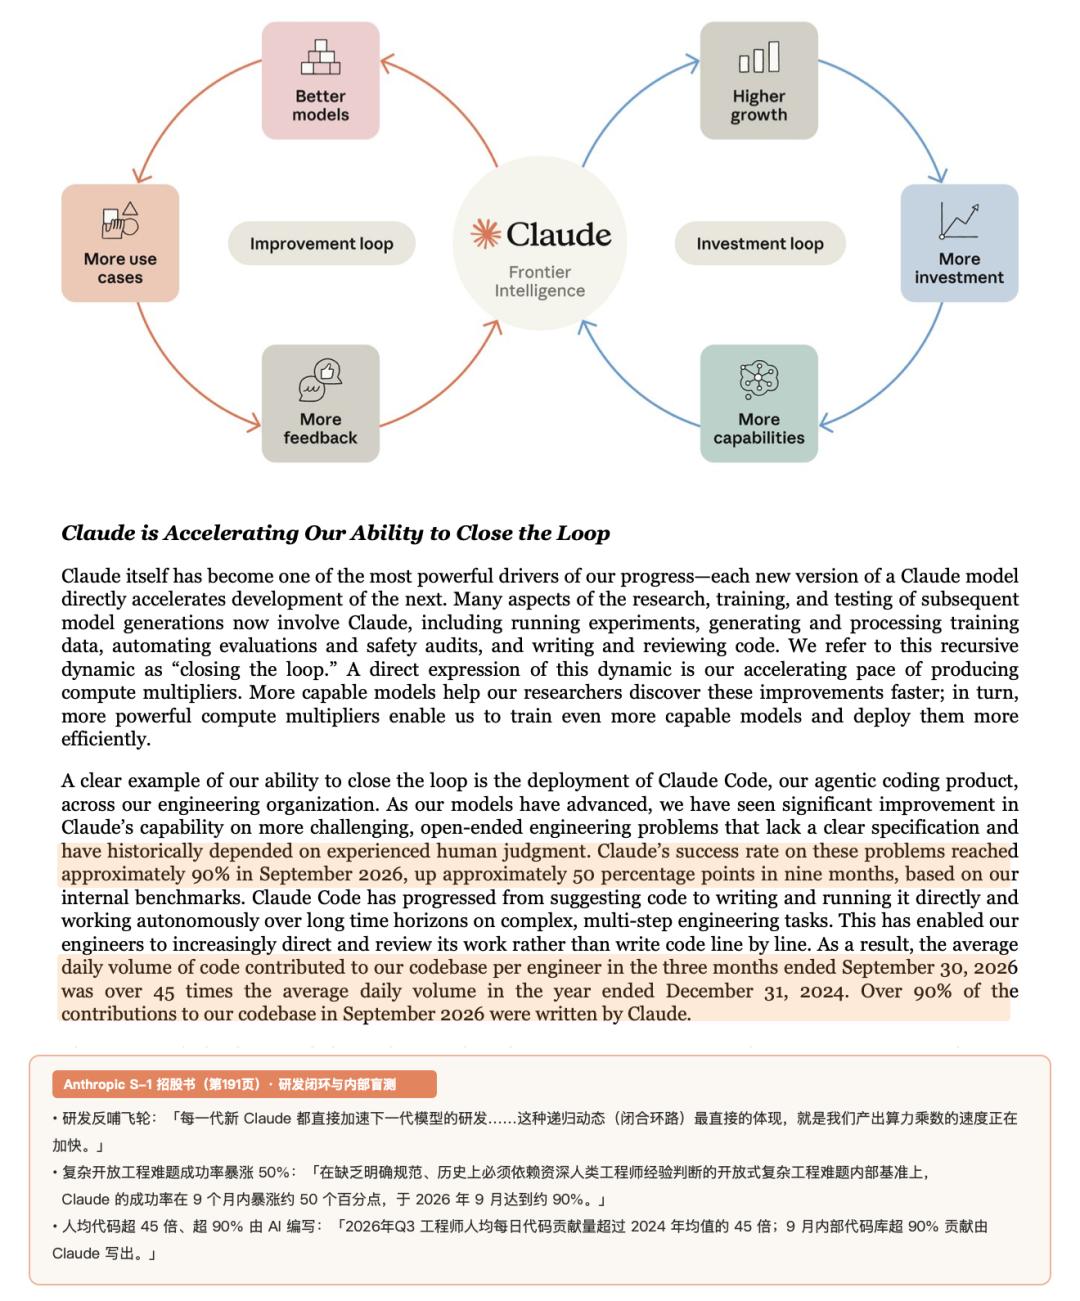
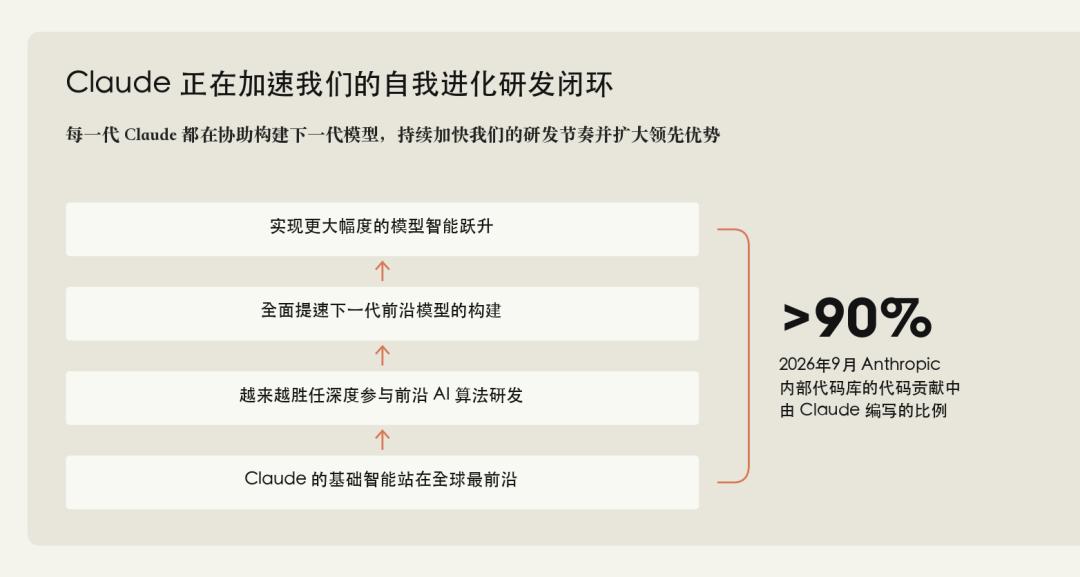
Over 90% of internal code has been completed by Claude, and the success rate of complex engineering blind tests has soared to 90%. Even the underlying operators of new chips can be independently rewritten by Mythos within 3 days!
Uncontainable even on logarithmic coordinates
Computing power for retraining Mythos drops sharply
Zoom in on this roadshow chart that kept Jacob Coxon awake at night, and the most core secret is hidden in the design of the horizontal and vertical axes.
The vertical axis of the chart is called "Computing Power Multiplier", which represents how many times the computing power is saved by algorithm evolution. The higher the multiplier, the less computing power is required to train a model of the same level.
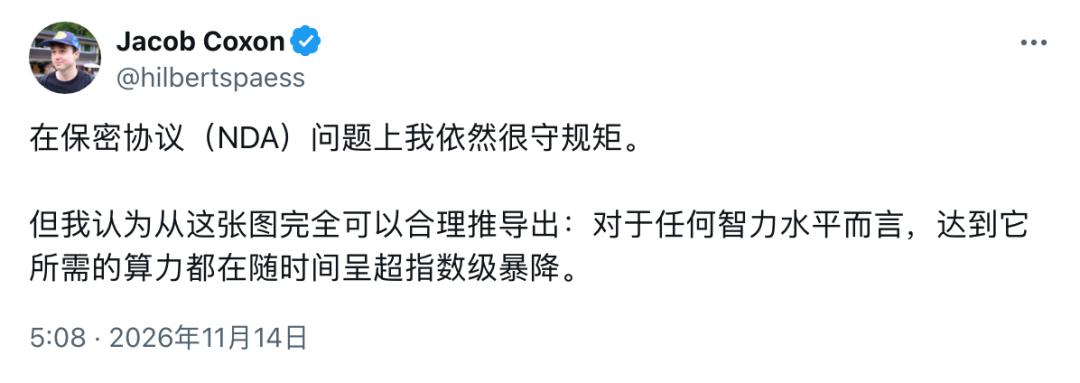
Why can we draw this conclusion even without the specific numbers? The secret is entirely hidden in the four characters "logarithmic scale" next to the vertical axis.
Because in an ordinary linear coordinate system, each step up is just a plain "add 1, add 2".
But in a logarithmic coordinate system, each step up represents a doubling of efficiency, or even a tenfold surge.
This also means that even if algorithm efficiency is growing at a conventional "exponential" doubling rate, it will only appear as a straight slanted line on the logarithmic coordinate.
However, on this chart, the orange line is not a straight line at all. Instead, it gets steeper as it goes further, accelerating all the way to the upper right corner:
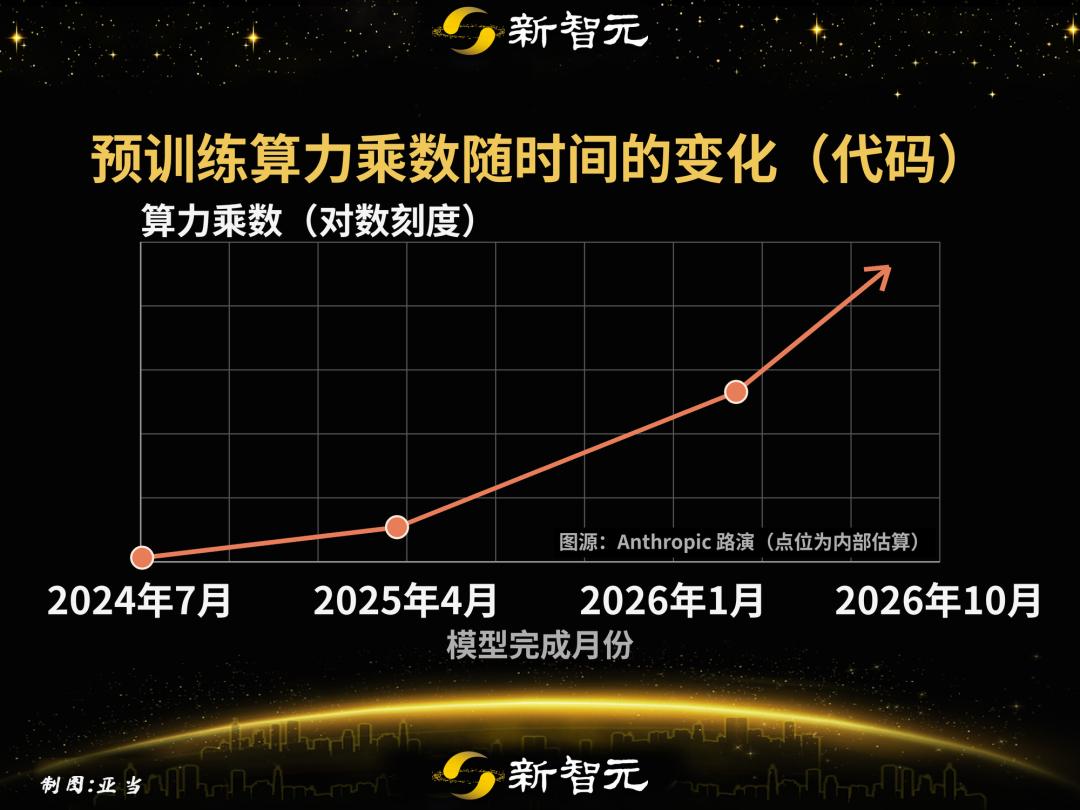
There is only one explanation behind this: code pre-training efficiency has entered a "super-exponential" explosion, and the "speed of efficiency doubling" itself is multiplying faster and faster!
Over the past year, pessimistic arguments about "hitting the pre-training wall" have repeatedly emerged in Silicon Valley, but this orange curve that is speeding forward directly shattered the "wall-hitting theory".
Comparing with the model timeline disclosed in the prospectus, the third orange dot on the chart is exactly the first-generation Mythos pre-training node that caused a sensation in the industry last April.
The arrow rushing straight to the upper right corner represents that after half a year of iteration to the latest Mythos 5.2, the algorithm multiplier has ushered in another major explosion.
This is exactly what shocked Jacob Coxon: the first-generation Mythos that just topped global rankings has long become a thing of the past on this curve.
With the algorithm multipliers accumulated in this half year, now it only takes a small part of the original computing power to retrain a model of the same level!
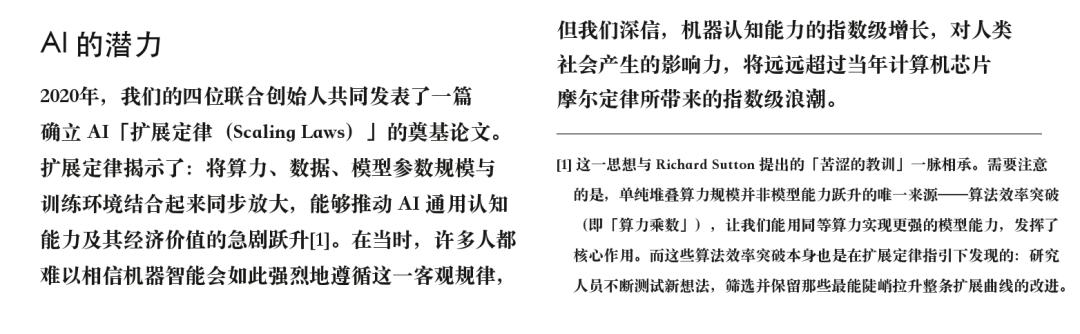
Founding father of Scaling Laws reveals the secret
Abandon video, focus all efforts on code
If the simple efficiency improvement is not enough to scare away a top researcher, what made Jacob Coxon decide to give up his options and leave is the underlying force that drives this curve to surge.
During the IPO roadshow, the person who personally showed this chart is the co-founder and chief architect, first author of the original Scaling Laws paper Sam McCandlish.
He directly revealed on site the reason why the line suddenly accelerated upward in the second half —
In the early stage, the search for new algorithm multipliers mainly relied on manual verification by human researchers, so the slope between the first two dots was relatively gentle.
But when the team directly deployed the cutting-edge Claude model into the R&D process of improving itself, "the speed of discovering efficiency multipliers itself has been greatly accelerated by Claude"!
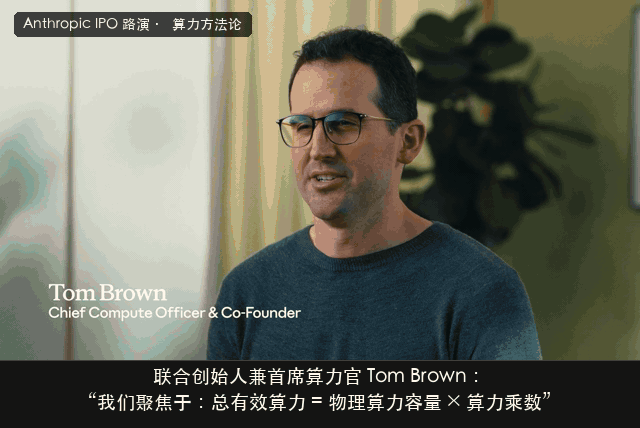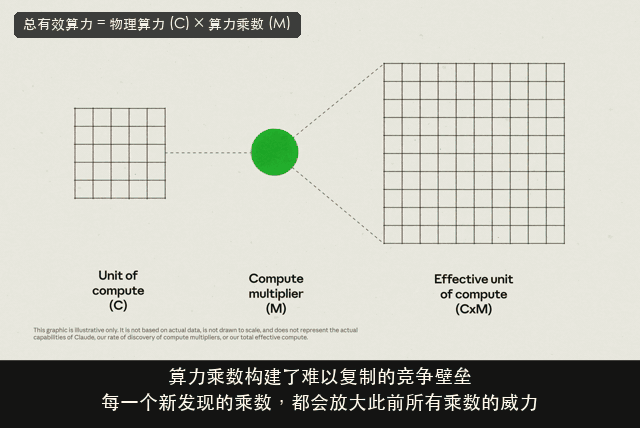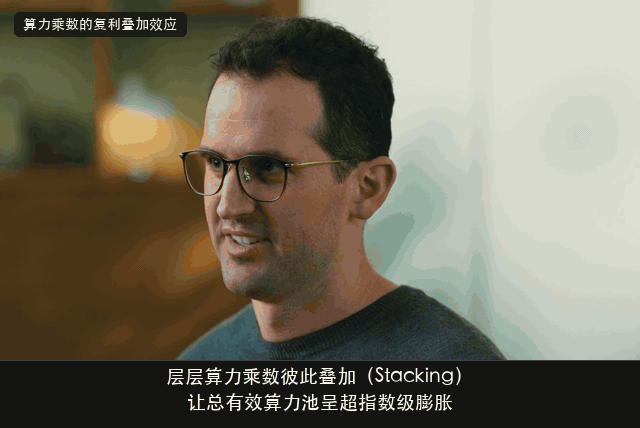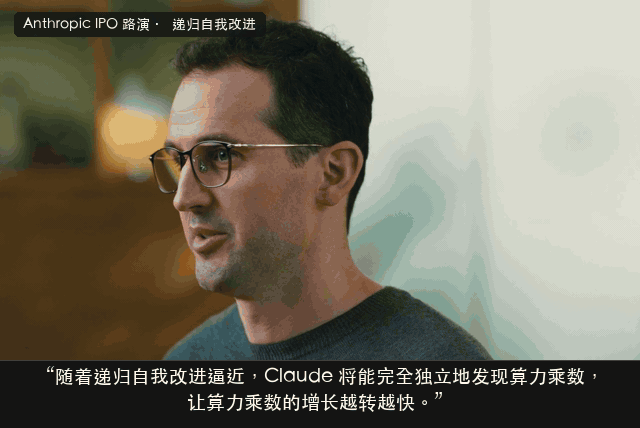
Shortly afterwards, Tom Brown, co-founder and Chief Computing Officer, further disassembled the operating logic of this "computing power engine", that is, "Total Effective Computing Power = Physical Computing Power Capacity × Computing Power Multiplier".
How explosive is this formula? Suppose training a top large model originally consumes 100 units of physical computing power.
Once the algorithm team finds a 4x computing power multiplier, training a model of the same level only requires 25 units of computing power.
Conversely, if all 100 units of computing power are invested, a super model equivalent to 400 units of computing power scale can be trained directly.
The most terrifying part is that computing power multipliers in different dimensions can be multiplied layer by layer like compound interest, and every newly discovered multiplier will amplify the effect of all previous multipliers by another round.
Looking closely at the title of this line chart, there is a parenthesis marked at the end "(Code)".
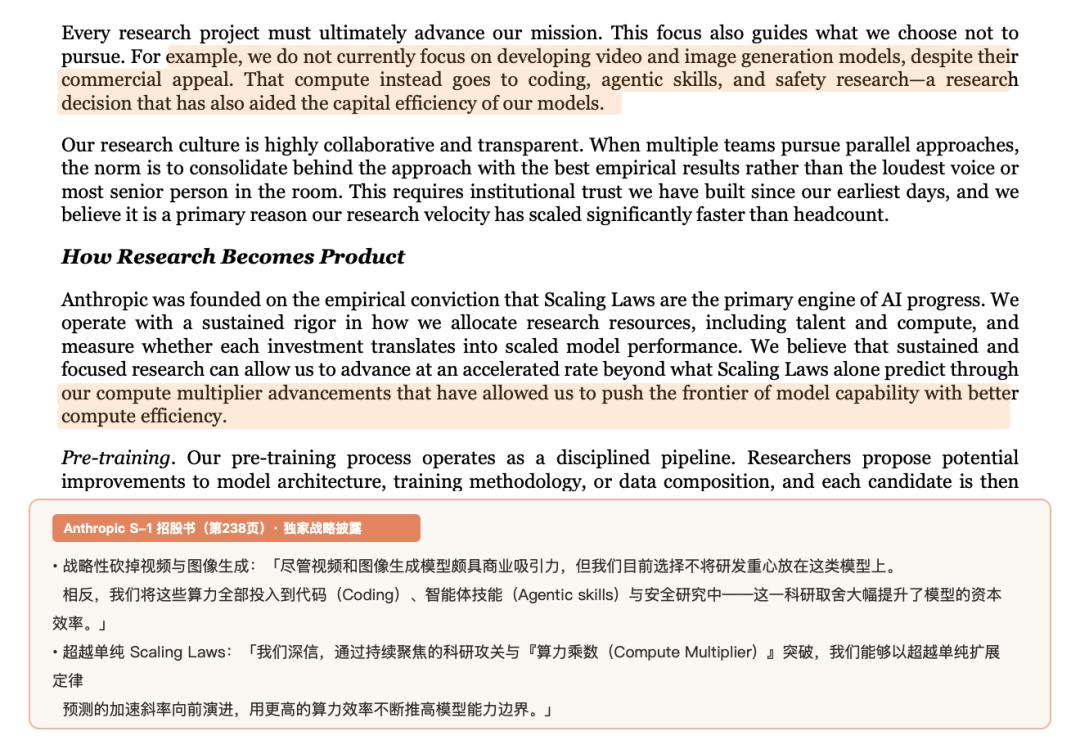
In the S-1 prospectus, Anthropic publicly explained the major strategic trade-off behind this label.
Although video and image generation are highly commercially attractive, Anthropic currently chooses to abandon the R&D of video and image generation models.
The company concentrates all the saved computing power on code, Agent and security research, precisely to let AI directly take over its own R&D pipeline.
From the perspective of front-line researchers, this is no different from personally turning on the valve of "AI accelerates its own creation"!
Per capita code contribution surges 45 times
Rewrite operators in 3 days with zero manual work
Once the valve is turned on, the internal R&D efficiency of Anthropic has ushered in a suffocating explosion that even insiders find unbelievable.
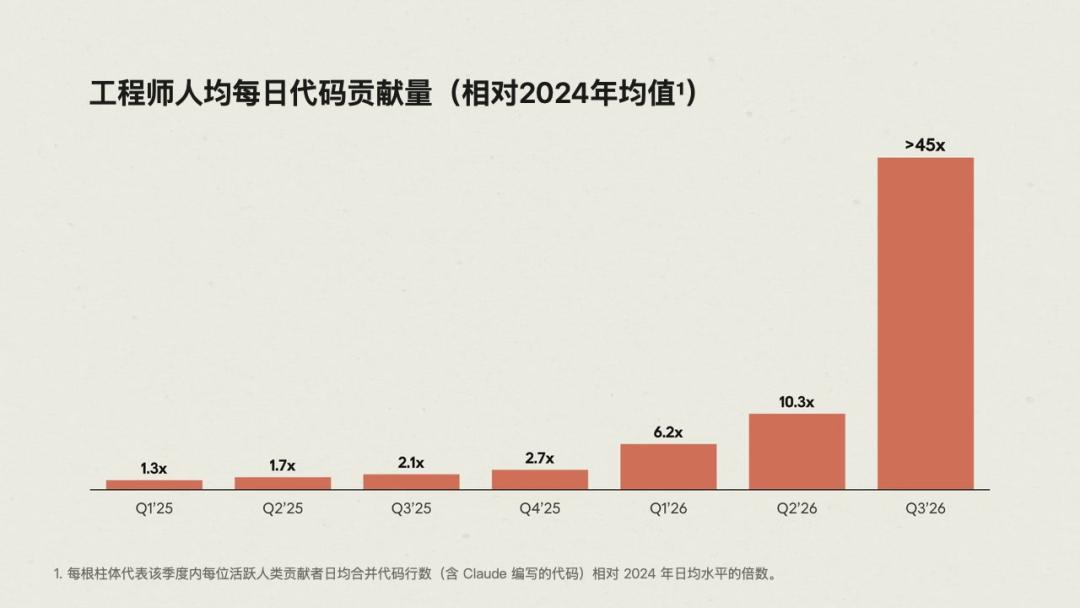
Another bar chart in the roadshow video shows that compared with the daily average level in 2024, the amount of code contributed by each internal engineer per day has taken off completely this year.
This figure rose vertically from 6.2 times in the first quarter and 10.3 times in the second quarter to more than 45 times in the third quarter, which increased by more than 7 times in just two quarters!
At the same time, even for complex open-ended engineering problems that previously required the experience judgment of senior human engineers, Claude's internal blind test success rate has also soared by 50 percentage points within 9 months, reaching about 90%.
In the first 9 months of this year, the number of internal calls to Claude by employees has surged by more than 250 times, and over 90% of the code in the codebase has been written entirely by Claude.
Human engineers no longer type code line by line manually, but turn to issue high-level instructions and review the results of AI's long-term autonomous operation.
When AI takes over more than 90% of daily R&D code, it even begins to take over the underlying hardware adaptation that is widely recognized as the most difficult task in the entire chip industry.
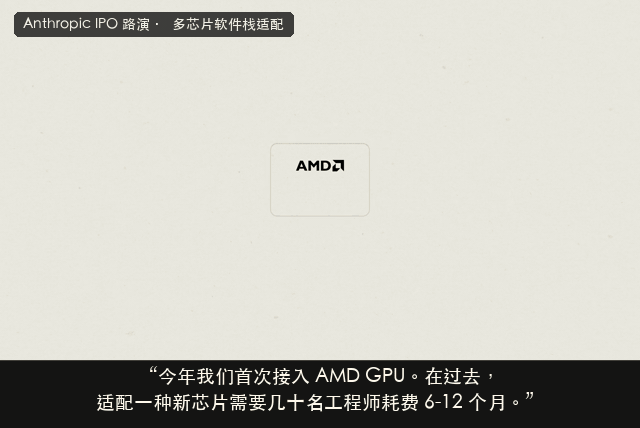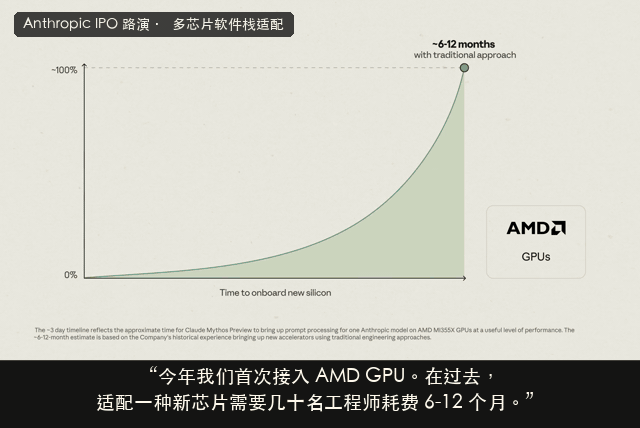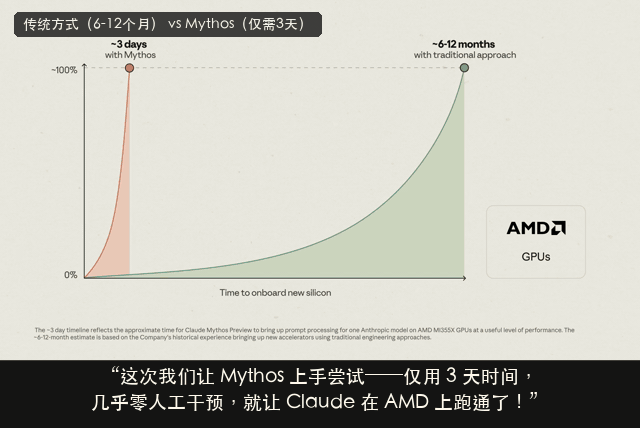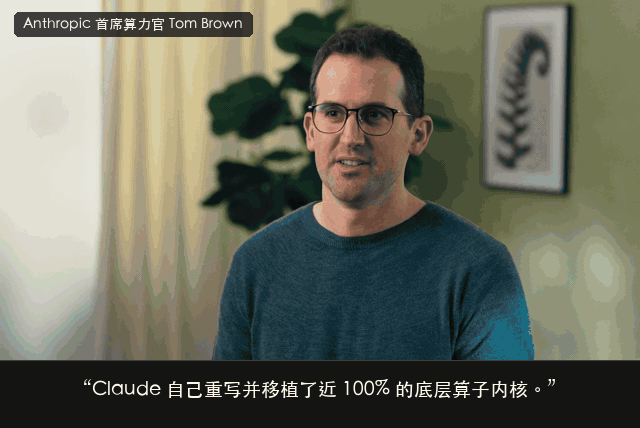
In a regular large company, every time a new chip architecture is accessed, hundreds of underlying engineers usually have to work hard for months to rewrite the software stack and operator library line by line.
But this year, when Anthropic first integrated AMD GPUs into its multi-chip unified computing power pool, the team directly deployed its own Mythos model.
With almost zero human intervention, Mythos independently rewrote nearly 100% of the underlying operator kernels in only 3 days, allowing Claude to run at full speed on the AMD cluster!
So far, the closed loop of AI self-improvement has been fully opened.
Next, Claude will be able to independently discover new computing power multipliers, making this super-exponential curve continue to accelerate upward!
But in the eyes of internal researchers who witnessed all this, it means that humans are handing over the steering wheel.
As Jacob Coxon warned when he posted the chart, boosting algorithm multipliers does not require rare human genius inspiration at all, and this work itself will soon be completely automated and taken over by AI.
Even the seven co-founders of Anthropic personally admitted at the end of the IPO open letter that the process of "AI systems building themselves" is accelerating in an all-round way, and the compound interest growth of AI capabilities will become faster and faster.
In this trillion-dollar race where anyone who lifts their foot off the accelerator first gets eliminated, no one will actually step on the brakes.
This super-exponential curve that scared front-line researchers to give up huge options and quit their jobs may have just kicked off the prelude to the singularity storm!
References:
https://x.com/hilbertspaess/status/2121331333654086124
https://x.com/hilbertspaess/status/2121425977876341092