Fable and Astra are stepping into the physical world, and Ant Lingbo chooses to take root starting from the fingertips.
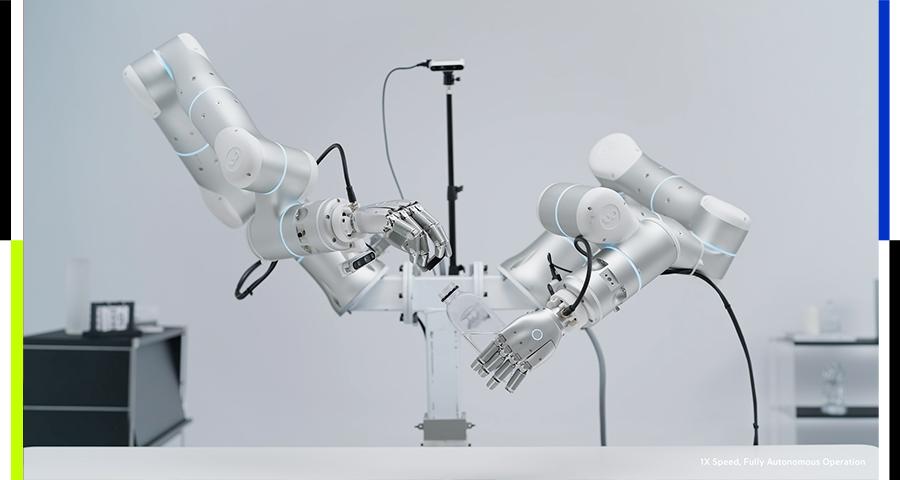
These past two days, you must have all seen the news about Claude Fable 5.2. Its real machine demonstration of tasks like unscrewing bottle caps, solving Rubik's cubes, and drawing is completed in one go, directly pushing the bimanual generalization success rate to 64.9%, more than double that of Astra.
At the same time, Ant Lingbo Technology open-sourced the tactile foundation model LingBot-Touch, which unifies three completely different types of sensor signals: magneto-tactile, visuo-tactile, and piezoresistive, into a unified set of "tactile Tokens" for different dexterous hands and motion models to use. This allows robots to "see clearly and think clearly", while further complementing the tactile perception required for fine manipulation.
Can general large models achieve "dimensionality reduction strike" on embodied intelligence? The relationship between these two technical routes is exactly the focus of current discussions in the embodied intelligence industry. From the perspective of Ant Lingbo, general large models and embodied foundation models are more of a synergistic relationship of 1+1>2: the former enhances the understanding and reasoning of tasks and the environment, while the latter complements physical perception and closed-loop operation capabilities. Only by advancing in tandem can the two jointly accelerate the maturity of the embodied industry.
Shen Yujun, Chief Scientist of Ant Lingbo, holds a rather sharp view on the recent market fluctuations. He said bluntly: "A usable tool is not necessarily the most suitable tool." He hopes this tool is "neither too big nor too small": no shortcomings in key capabilities, and no waste in non-essential capabilities. The "size" mentioned here does not refer to the parameter scale, but the capability configuration. For example, embodied models should not take programming capabilities comparable to Fable and Astra as their goal, because complete software engineering capabilities are not a rigid requirement for robot operations. Conversely, the perception and understanding of physical modalities such as distance and tactile sense are capabilities that digital world models do not natively have, but are indispensable for robots to complete high-precision complex operations.
Developing Tactile Capability Is Not an Optional Choice, But a Mandatory Task
Over the past three years, embodied intelligence has been advancing rapidly driven by visual and language modalities, and the industry has produced a series of impressive demos. However, once robots enter the real world, they often fail at the fine manipulation stage.
Through sufficient implementation practices, the industry has realized that visual and language modalities solve the thinking "before contact", while tactile sense addresses the state "after contact". When the gap between "perception" and "action" in embodied intelligence is so prominent, tactile sense is no longer an optional choice, but a mandatory task.
Whether a robot can hold an object steadily often only becomes clear after its fingers touch it.
Tactile sense, this brand new modality, is gradually stepping onto the industry stage, but it has also taken detours in the past few years. For example, the once mainstream judgment was: Will adding tactile sense introduce noise to the model and reduce its performance? Should we wait until the sensor route is fully clarified before developing the tactile modality?
In recent months, the consensus on the tactile modality has reversed rapidly. However, even though the necessity of the tactile modality has reached a consensus, it does not mean that the industry has found a unified solution. At present, there are still three different branches in the tactile sensor field: visuo-tactile, magneto-tactile, and piezoresistive tactile.
Each of the three routes has its own advantages and disadvantages. Visuo-tactile obtains contact information by observing the deformation of the flexible surface, which can capture rich contact patterns, but it is inevitably constrained by the frame rate. Magneto-tactile uses magnetic field changes to perceive force, which is thin and fast, but vulnerable to ferromagnetic interference. The piezoresistive type measures pressure through resistance changes, with the advantages of low cost and easy large-area deployment, but it has low resolution and is prone to drift after long-term use.
The non-convergence of technical routes has also spawned a large number of industry pain points. Due to the lack of a tactile base that unifies the modeling of three types of heterogeneous tactile signals to generate general representations, the R&D efficiency of the industry is extremely low.
Take a straightforward example: a robot learns "how to judge finger slipping" today, but if it is switched to another dexterous hand or tactile sensor tomorrow, this experience will be completely invalid. Some engineers joked that every type of tactile sensor has its own "dialect" that others cannot understand.
The LingBot-Touch released by Lingbo this time is exactly trying to solve this pain point, and its biggest feature is universality and compatibility.
Lingbo has roughly introduced the entire training process of the tactile model to us.
First of all, the data of LingBot-Touch mainly comes from two types of real operations: one is the operation performed by humans wearing tactile gloves, collecting 2197 hours of piezoresistive tactile data and 1136 hours of magneto-tactile data; the other is collecting 1650 hours of visuo-tactile data by teleoperating the Sharpa Wave dual-arm robot.
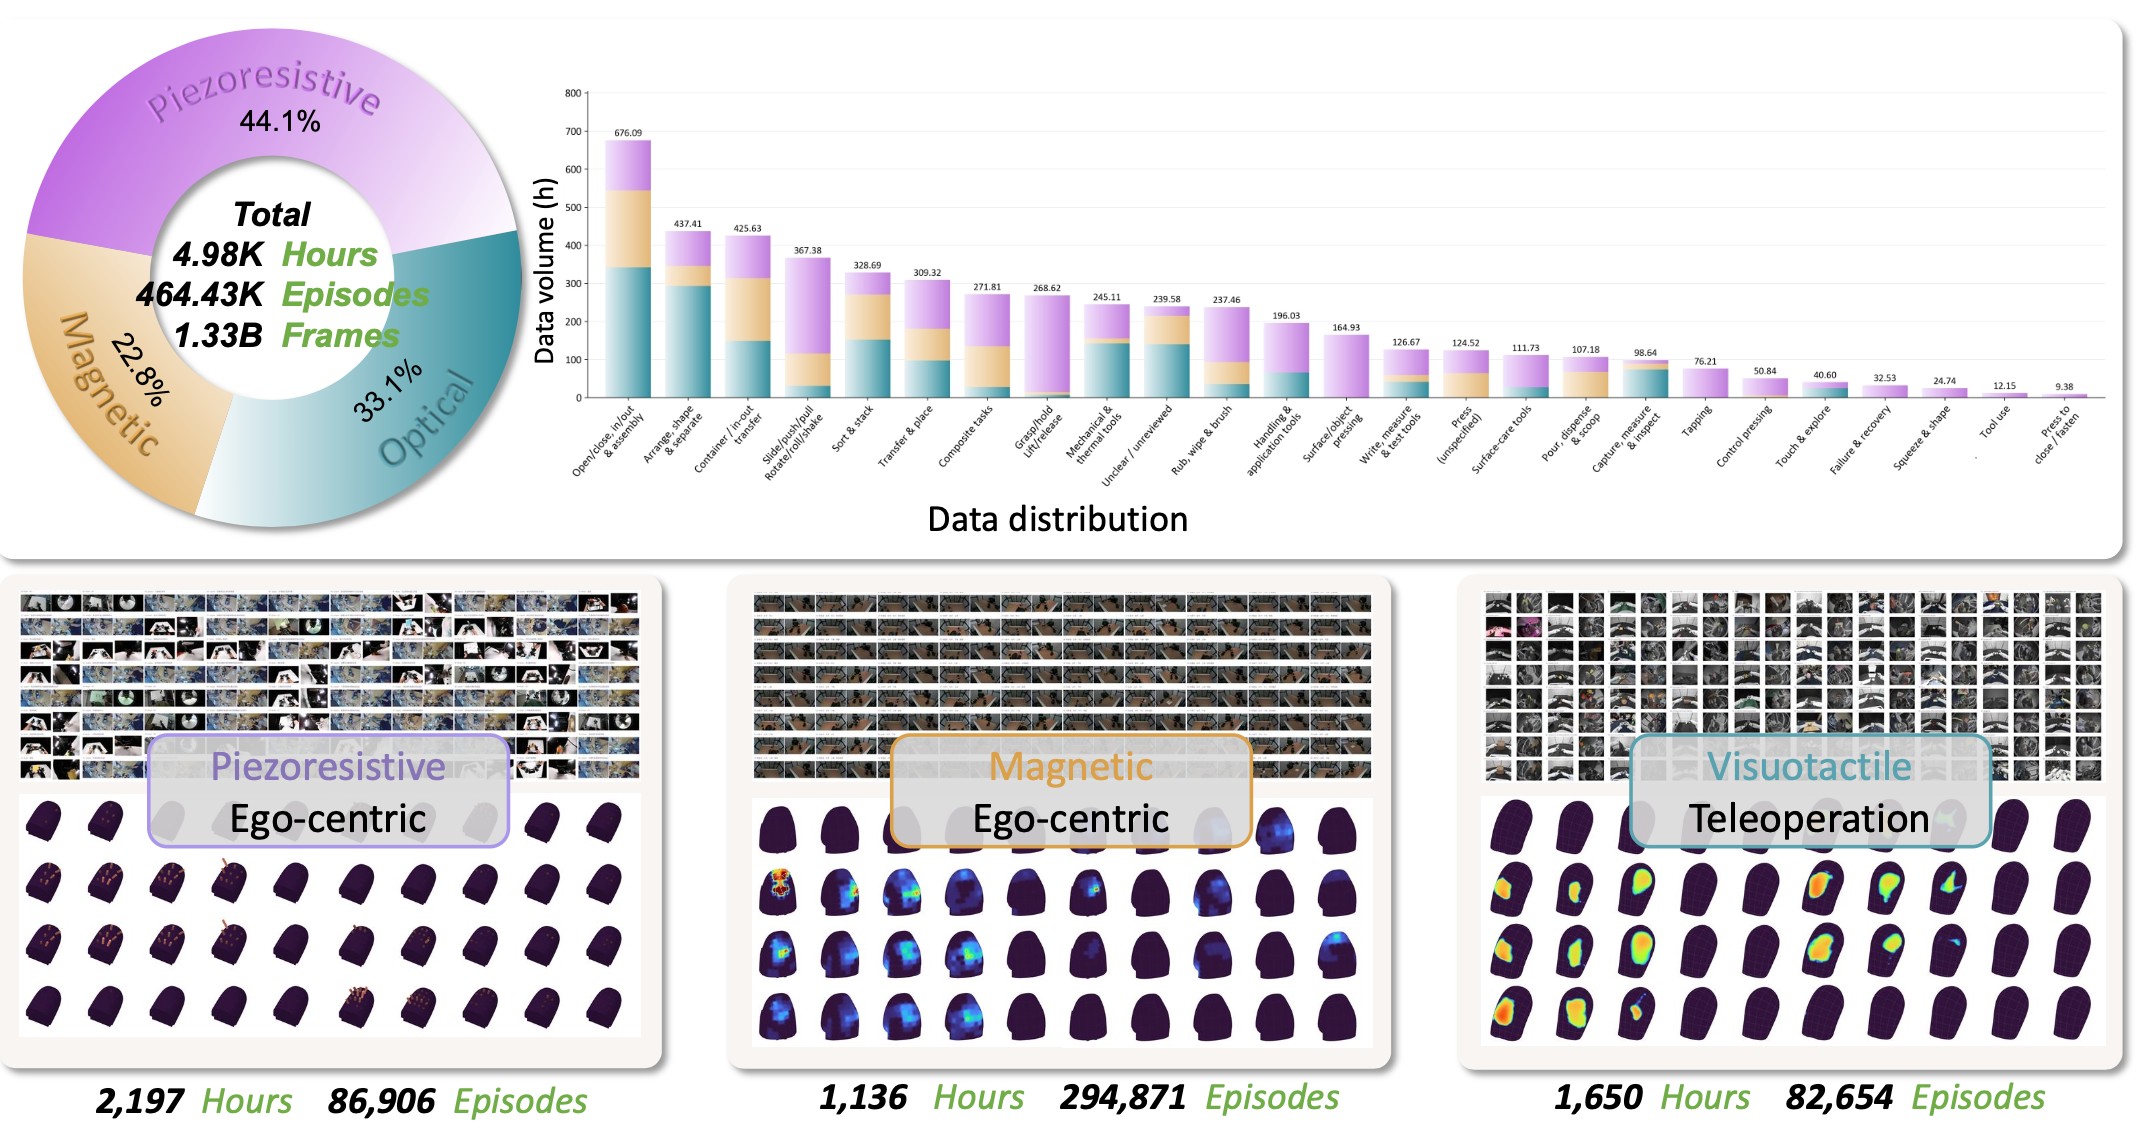
The subsequent training process can be briefly summarized as three steps:
First, to enable the model to uniformly understand the tactile signals generated by different sensors, the research team first maps all contact points to a unified standard fingertip coordinate system. Second, dedicated Tokenizers (encoders) are designed for different sensing principles such as piezoresistive, magneto-tactile and visuo-tactile respectively. Third, the original signals are converted into Tokens that the model can process, and finally input into the same Transformer for training.
The entire training idea is a bit like letting the model do a "fill-in-the-blank question": randomly mask part of the tactile information of the fingertips, and let the model infer what happened to the masked part according to the contact changes at other positions. However, it does not require the model to accurately restore the original data recorded by the sensor, but to predict more meaningful features among them, such as what contact state and physical changes these values represent.
The final effect is that LingBot-Touch directly breaks through the layers of barriers that previously existed between sensors, dexterous hands, tasks, and motion models.
For example, when you switch to a different tactile sensor of the same principle, the new model does not need retraining. If you need to replace the dexterous hand, even if the new hand is equipped with a sensor that has never been seen in the pre-training stage, it can be directly connected.
In addition, if you want to switch hand tasks, whether it is turning pages or unscrewing bottle caps, you do not need to retrain a new set of tactile models. With only a small number of demonstrations, the motion model can learn new operation methods. Even when you need to replace the underlying motion model, you can still continue to use the same set of tactile information.
Real machine tests have also verified this point.
Take unscrewing a bottle cap as an example. Sharpa Wave only has a success rate of 56.25% without the tactile model. After accessing LingBot-Touch, the robot can perceive that the bottle cap is about to slip and adjust the force in time, raising the success rate to 90%.
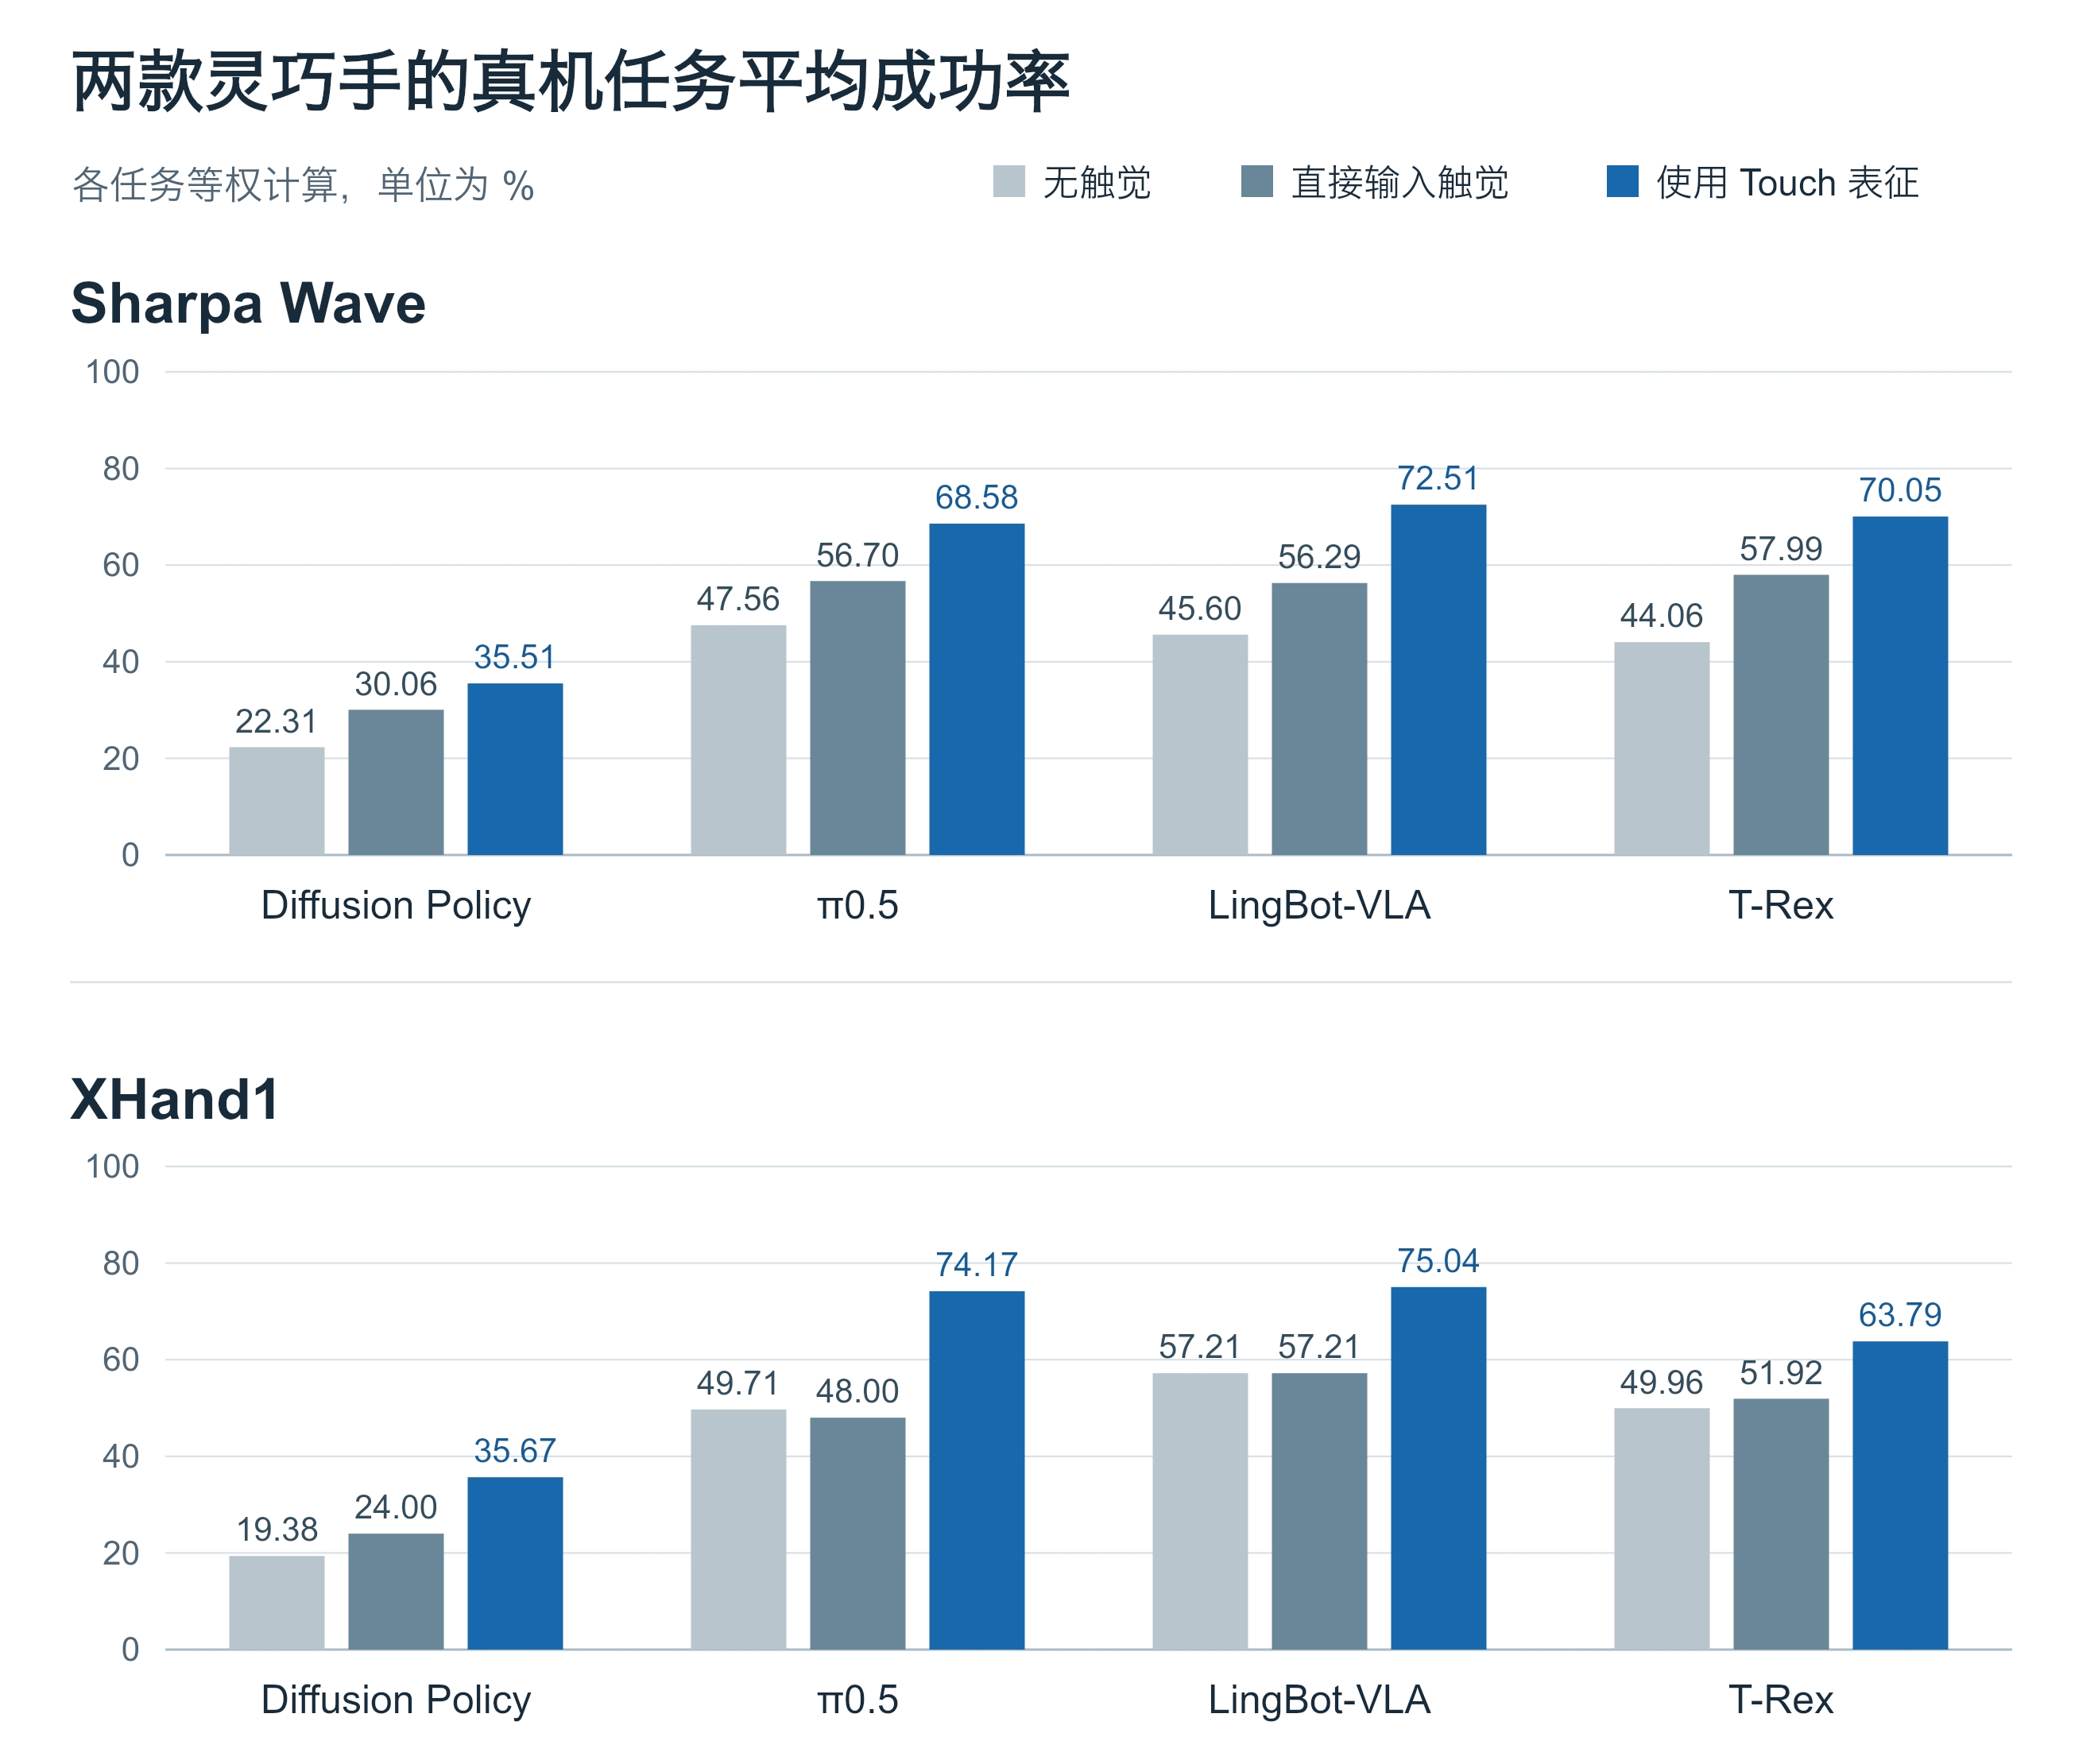
In other words, while the industry is still arguing about how to implement tactile capability and whether it is worth doing, Lingbo has already transformed it from a "sensor selection problem" into a "base capability problem". After completing this step, the remaining question is no longer whether tactile capability is needed, but whether the "brain" is sufficient after tactile access.
With Foundation Models Advancing Rapidly, Why Does Lingbo Still Adhere to Embodiment-Native Development?
After realizing the importance of tactile sense, some people may think that if we directly inject tactile data into the foundation model, the robot deployment will be all set. That is a big mistake.
For example, a type of market player directly uses general large models as ready-made brains, then supplements motion data and tactile information to quickly produce works. The judgment of such players is very realistic: instead of spending a lot of money to develop their own brains independently, it is better to directly "surrender" to general large models. But some other approaches are more tactful: they leverage the power of foundation models for semantic understanding, but do not blindly graft physical intelligence.
Different from the above approaches, Lingbo has chosen a longer-term, more thorough route — adhering to developing embodiment-native models. The aforementioned tactile model is actually just one sensory module in Lingbo's brain model matrix.
In the past few years, Lingbo's LingBot family has long laid out a far-reaching embodiment-native development path. In addition to tactile sense, it also covers spatial perception, world prediction, instruction understanding, and motion generation.
In the view of Shen Yujun, Chief Scientist of Lingbo, there are at least three gaps between foundation models and the real world.
The first is the data gap. Just as a person cannot become Roger Federer by watching Federer play tennis tens of thousands of times. Internet data is rich and cheap, but real-world data has more diverse dimensions: how many Newtons of force are used to hold a tennis racket, how the wrist and finger pads adjust their postures according to the trajectory of the ball. These data only exist in real contact and practice.
Second, the physical world does not pause. Careful observation shows that although Fable 5.2 has strong capabilities in thinking and task decomposition in the simulation environment, its actual execution speed is very slow. The original video of the previous GPT-6 Astra even lasted as long as three hours. Real machines require millisecond-level response to changes, while cloud-based large models need several minutes to think about a single action, which will definitely cause problems during task execution.
Third, simply and crudely feeding new tactile modalities directly into the foundation model may not achieve the 1+1>2 effect. An example from Lingbo's internal test is: taking Sharpa Wave zipping up a zipper as an example, the success rate is 39% without inputting tactile modality. If tactile information is crudely added, the success rate will directly drop to 15%, and the tactile sense will instead become "dirty data" that interferes with the model.
Therefore, Lingbo put forward the counter-consensus strategy of "embodiment-native": the ideal robot is not a "smart foundation large model equipped with tactile modality and robotic arm", but a fully integrated system — semantic intelligence takes root in the digital world, and physical intelligence must also have its own root, mastering real-world data, its own sensors, and its own pre-training methods.
During the years of dedicated development, Lingbo Brain 2.0 has built a complete native technology stack. The reason why it is called "native" is that it does not simply migrate the language and visual capabilities of general foundation large models to robots, but builds an embodiment-native model system centered on perception, understanding and action in the physical world.
According to Lingbo, the spatial perception layer in Lingbo Brain 2.0 consists of LingBot-Vision and Depth 2.0, enabling robots not only to recognize what an object is, but also to judge the spatial boundary, distance and geometric relationship of the object.
For example, when facing transparent cups, reflective metals or stacked sundries, robots no longer only guess the object contour based on 2D images, but truly understand the position and form of the object in 3D space.
The dynamic interaction layer, through LingBot-Video and World 2.0, further enables robots to understand the dynamic changes of the physical world: they not only know what is in front of them, but also can predict how their actions will change the environment. For example, when pushing a door, it is not only necessary to know where the door is, but also to predict how the door will rotate, how much resistance it will receive, and whether it will rebound after releasing the hand.
The tactile perception layer is supplemented by LingBot-Touch to fill in the information that vision cannot perceive, giving robots the ability to judge contact position, applied force and slip state, which is equivalent to installing a layer of subcutaneous nerves for the brain, enabling it to perceive whether an object is slipping and whether the grasping force is appropriate.
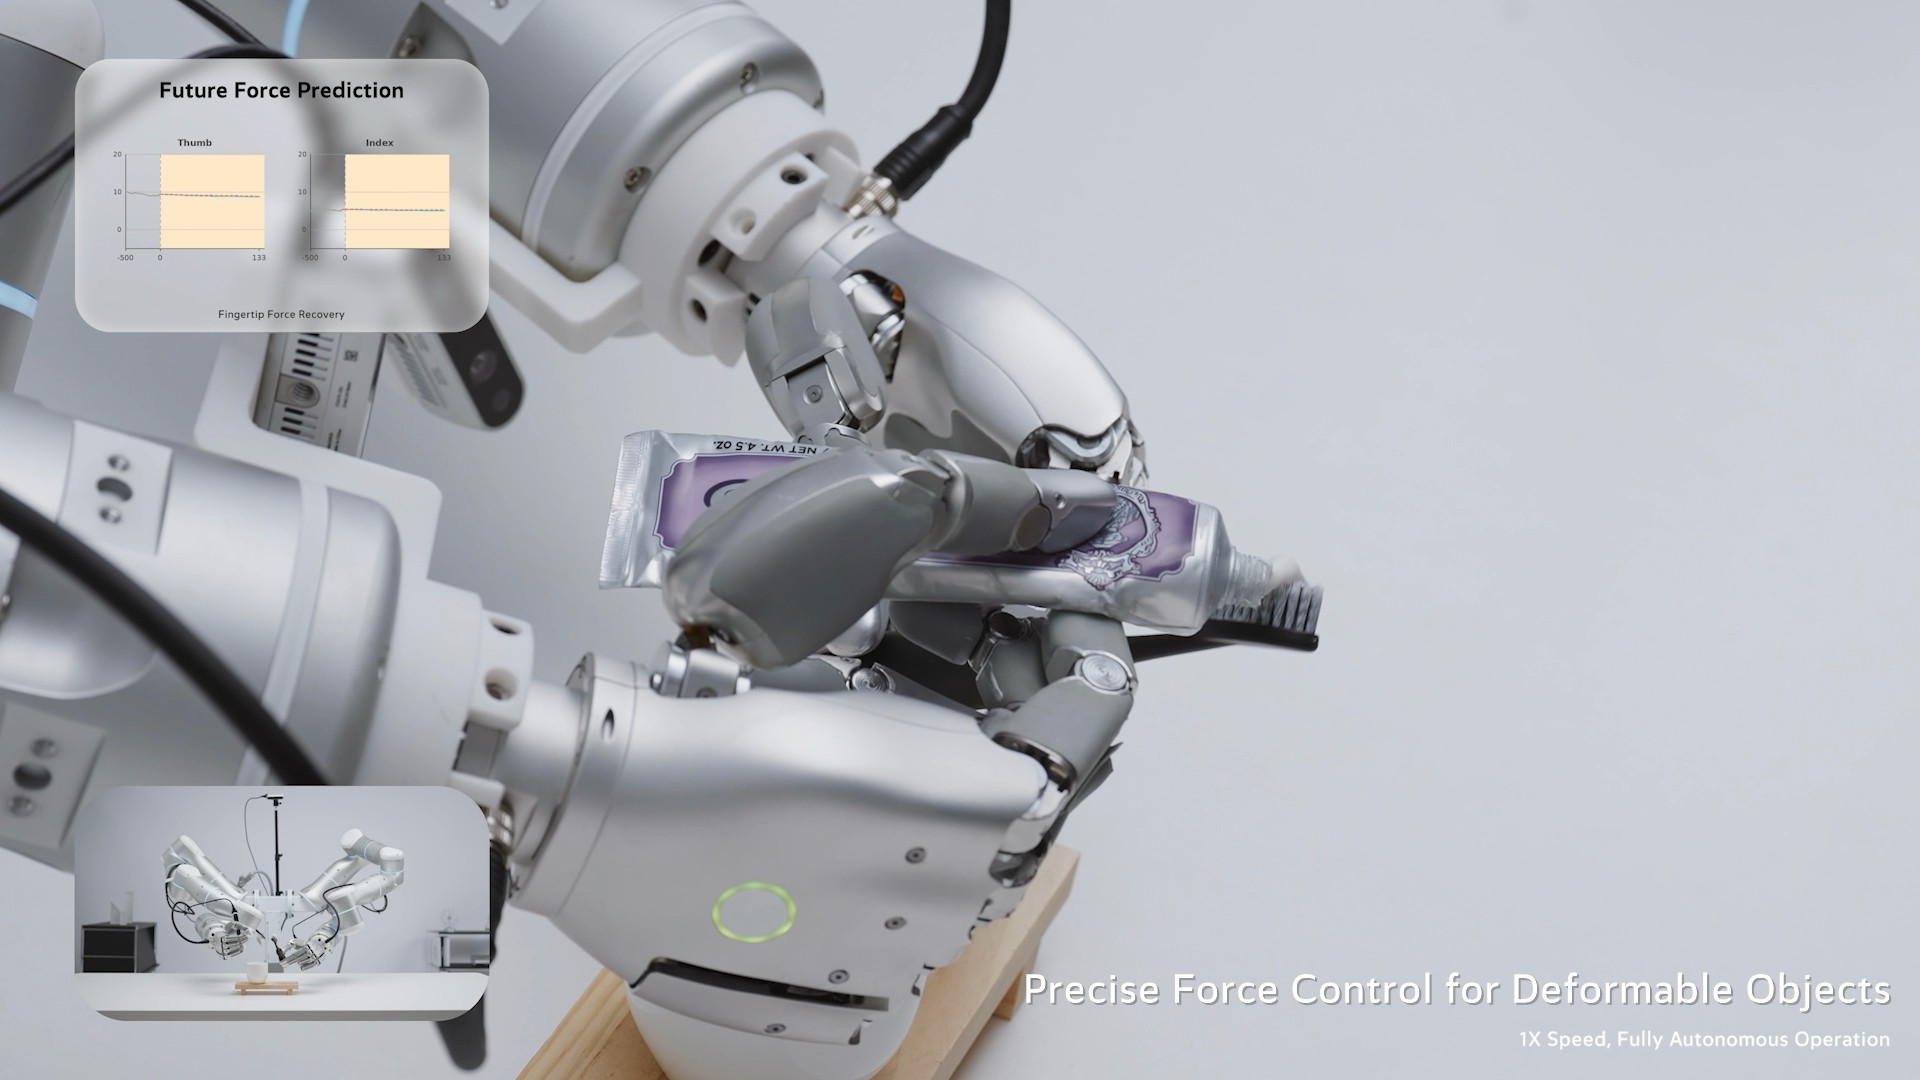
Finally, the operation execution layer consists of LingBot-VLA 2.0 and VA 2.0, which converts the above perception and prediction capabilities into actual actions, allowing robots to continuously deduce, provide feedback and adjust during the execution process, instead of generating action instructions at one time based on input like traditional models.
It is worth noting that the relationship between the four-layer model matrix is not a simple "1+1+1+1=4", but "greater than 4" after sharing physical representations. That is to say, the force perception information extracted by Touch will feed back to the grasping decision of VLA; the World model verifies predictions with contact feedback; the spatial prior of VLA in turn helps Touch eliminate discrepancies.
We can use the case of "a robot picking up a bowl full of water" to help understand: Depth tells it where the edge of the bowl is, Touch detects that the finger pad starts to slip and the bowl is tilting, the World model predicts that the soup will spill if the force is not reduced, and VLA immediately adjusts the force distribution from "squeezing tightly" to "supporting the bottom".
In fact, Lingbo, which adheres to embodiment-native development, is not a "minority". Overseas, a number of companies have chosen not to follow the foundation model path, and abandoned the direction of "adjusting LLM to become a robot".
What makes Lingbo different is that it does not only focus on force control or only develop world models, but builds a more systematic system, turning various modalities into "nerves" of embodiment-native, which are intertwined into a physical brain that can be reused across hardware.
Building Infrastructure for the Embodied Intelligence Industry
Looking at the industry as a whole, LingBot-Touch is just an entry point. The four-layer architecture of Lingbo Brain 2.0 — spatial perception, tactile perception, dynamic interaction, and dexterous operation — aims to solve a larger problem: can robots have a universal intelligent base, so that they do not need to be trained from scratch every time they switch to a different piece of hardware or enter a new scenario?
If this can be achieved, it will have at least three impacts on the entire industry.
First, it will decouple robot hardware from intelligent algorithms.
In the past, after a robot company selected a certain dexterous hand, sensor and ontology, it often needed to retrain the perception model and motion model around this set of hardware. After switching to a new set of hardware, many algorithms also need to be remade.
What Ling