ChatGPT Pro Quota Doubled: A Concession, Not a Benefit?
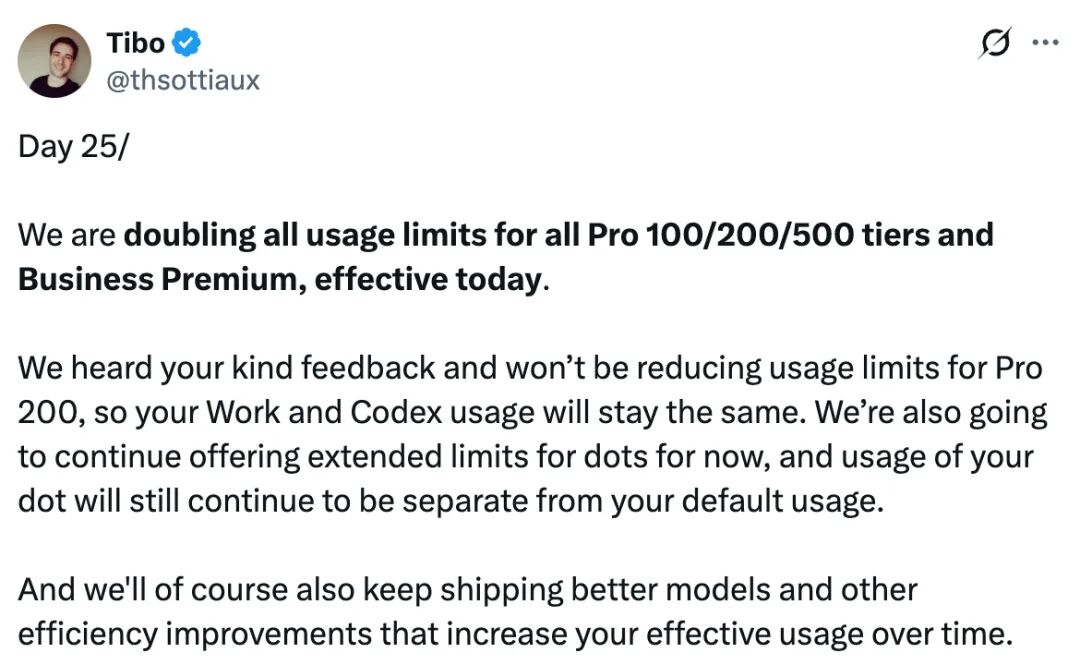
On October 29, Tibo, Head of Product at OpenAI, announced that effective immediately, the usage limits for Pro 100, Pro 200, Pro 500 and Business Premium plans have been fully doubled.
There is also an important note: after listening to user feedback, OpenAI has decided not to cut the usage quota of Pro 200, so the ChatGPT Work and Codex usage of this plan will remain at the original level. At the same time, Dots will continue to enjoy expanded quotas, and its usage is independent of the account's default quota and will not be counted towards the default quota.
This adjustment actually responds to the controversy caused by the previous adjustment of the Pro subscription system. OpenAI previously launched the $500 Pro 500 and adjusted the rights and interests of the $200 Pro plan, and existing Pro 200 users once faced the expectation of partial reduction of usage quota. This announcement withdrew the relevant reduction arrangements, which means that user feedback has indeed affected the final policy decision.
Later, some users further asked whether Pro 500 means that users can get 50 times the usage of the Plus plan, and Tibo directly answered "Yes". This also reflects that OpenAI is further widening the usage quota gap between different paid tiers, providing more usage space for high-intensity AI programming and workflow users.
The community did not unanimously praise this move. Some Pro users welcome the quota expansion, but some $200 Pro users pointed out that they already had a high quota before, and this time it only withdrew the originally planned reduction plan, and did not obtain new rights and interests in the true sense.
"I am glad that users of other Pro tiers and low-quota plans have got real quota increases, which are the real optimizations. However, packaging the cancellation of the original quota reduction into the 28-day improvement plan and publicizing it as a full doubling upgrade is misleading. Frankly speaking, for users who have been following this matter and relying on official announcements to make plans, this statement is really unacceptable." a user said.
At the same time, some Plus users expressed dissatisfaction that this adjustment did not cover low-price plans, believing that OpenAI is further widening the usage experience gap between different paid tiers.
In addition to increasing the quota, Tibo also emphasized that OpenAI will continue to launch better models and efficiency optimizations, so that users can get more actual usage over time. It is worth noting that this adjustment is the 25th day of OpenAI's 28-day product improvement plan. Tibo then joked that OpenAI is graduating from being a "quota reset company" to becoming a "Token company".
Andrew Ambrosino, who is in charge of Codex and ChatGPT products at OpenAI, also said that the team has launched a round of intensive improvements, focusing on solving application simplicity and performance problems, and he is personally responsible for this work.
This means that OpenAI does not intend to only rely on expanding the upper limit of the plan to meet user needs, but hopes to simultaneously improve model capabilities, reasoning efficiency and output per unit of computing power. For developers who are increasingly relying on Codex, whether they can get a stable and sufficient usage quota has become an important factor affecting subscription decisions.
In addition to OpenAI, in the past year, Anthropic has also frequently adjusted the usage limits of Claude Code, and even experienced the process from tightening to expanding, and then to partial recovery.
In March 2026, Anthropic once tightened the 5-hour usage quota for free, Pro and Max users during peak hours; after reaching a computing power cooperation with SpaceX in May, it doubled the 5-hour quota of Claude Code and canceled the peak quota reduction for Pro and Max plans. At the same time, the company also temporarily increased the weekly quota of Claude Code by 50%, but after the promotion ended in September, it only retained a permanent quota 25% higher than the original level.
Dissatisfaction with quota adjustments has also led to users' lawsuits over subscription rights.
Anthropic's Max 5x and Max 20x plans respectively advertise to provide 5 times and 20 times the usage of the Pro plan, but this multiple actually refers to the usage within each 5-hour session window, not the cumulative weekly usage, and users are also subject to the total weekly limit. In September this year, a group of users filed a class action lawsuit against Anthropic on this grounds, believing that the relevant restrictions were not fully and prominently explained during the purchase process, leading to a gap between the actual usage experience and purchase expectations.
1 Background Agents consume a lot of Tokens in inconspicuous places
The quota problem of AI programming tools is not a simple matter of plan pricing. As Agents gradually take over more development tasks, automatic background execution, task scheduling and multi-agent collaboration have also begun to consume a large amount of computing power, and even the situation that users do not directly perceive tasks but have already consumed a lot of usage quotas has emerged.
In June this year, OpenAI's Codex had a similar problem. At that time, many users found that the usage quota that originally took a week to consume was suddenly used up in a day or two. Some $200 Pro users said that the quota that used to take a full week of continuous work to run out could later be exhausted in one day.
Tibo later explained that the problem was related to abnormal background workload: automatic code review and auxiliary sub-agents sometimes run more frequently than expected, even perform tasks repeatedly, or retry excessively after errors, resulting in unnecessary computing power consumption. In addition, the Codex dashboard once displayed some activities that were not actually counted into the user's bill, further aggravating users' confusion about abnormal quota consumption.
To this end, OpenAI organized an emergency investigation, set up a special team to investigate the problem, deployed fixes and reset the usage quota for all users, and added background usage monitoring to detect similar problems earlier. Tibo also said that the team will give users an additional quota reset to make up for the impact of the previous abnormal consumption.
Anthropic's Claude Code has also been found to have similar problems, except that the consumption occurs in a more inconspicuous link.
On August 15, a developer submitted an Issue in Anthropic's Claude Code GitHub repository, asking the official to provide an official switch that allows users to turn off sub-agent status summaries without sacrificing the entire sub-agent function.
The problem lies in the background status refresh mechanism of Claude Code. When users start multiple sub-agents, the system will periodically call the model to generate a short status prompt for each active agent, such as what task is currently being executed. According to the developer's analysis of the internal requests of Claude Code, this mechanism is triggered by default every 30 seconds, and each time it resubmits the complete dialogue history and tool definition of the sub-agent to the model to generate a summary. The final output is usually only dozens of Tokens, which is mainly used to update the status text in the interface, and helps users and Claude Code grasp the work progress of each background agent.
The developer performed packet capture analysis on a 4-hour session that started 27 sub-agents. Among the 1496 API requests, 339 belonged to agent_summary, accounting for 22.7% of all requests; this part of requests generated about 62.76 million raw Tokens, accounting for 22.2% of the total raw Tokens. After weighting according to the cache read, cache write and output prices of Opus 5, its cost still accounts for about 18% of the entire session.
Another developer also found similar problems when using 4 sub-agents for a 1 hour and 45 minutes test. Among them, a long-running agent had a context size of about 380,000 Tokens, and 103 status summary requests generated 21.8 million cache read Tokens, accounting for 26% of the cache read volume of the entire session, but the final output was only about 2100 Tokens. According to the developer's calculation, this agent alone could generate about 45 million cache read Tokens per hour just to generate status prompts.
What's more troublesome is that these background requests are set with skipTranscript: true, and usually do not enter the regular session transcript file. Therefore, third-party tools that rely on session records to count consumption may underestimate the actual Token usage. What users see are the constantly changing words in the agent status bar, but a large number of context reads may have occurred behind the scenes.
On October 28, developer "Flamerix AI" also made its monitoring results public. By analyzing the OpenTelemetry telemetry data of Claude Code, it found that within a one-week statistical cycle, agent_summary accounted for 16.4% of the total estimated cost and 19.7% of the total API requests, and the ratio of input to output Tokens was about 9000:1. In other words, in order to generate a small amount of status text, the system needs to repeatedly read a large amount of context.
Flamerix AI then released an open source script under the MIT license, which tries to intercept related timers through the Bun preloading mechanism, and turn off the status summary without modifying the Claude Code binary file. The script has been tested in multiple versions in the Linux environment. After the summary is turned off, background sub-agents, Forked Skills and background sessions can still run normally, except that the Agents panel no longer continuously updates the status text. However, this method relies on the internal implementation of Claude Code, which is not an officially supported solution by Anthropic for the time being, and subsequent version updates may also make it invalid.
As this matter continues to trigger discussions in the community, Edwin Arbus, an Anthropic engineer who claims to be a member of the Claude Code team, also came forward to respond.
He explained that this mechanism only targets background agents that are working, and idle agents will not continuously trigger summary requests. The 16.4% measured by Flamerix AI may come from a team that makes extensive use of background agents, and is not universally representative. According to Anthropic's telemetry data from the previous week, among Claude Code users who submitted telemetry information, agent_summary accounts for about 2% of the total cost calculated at the API list price, and slightly less than 4% of the total requests; if only looking at the terminal environment, this ratio is about 6%.
However, Arbus also admitted that even 2% is still a relatively high cost for a function that is mainly used to generate status prompts. He revealed that Anthropic has fixed the most expensive scenario in Claude Code versions 2.1.311 and later, that is, the problem that summary requests fail to hit the prompt cache. At present, the team is still developing a cheaper implementation method, which no longer submits the complete dialogue history every time, but sends short notes, and then hands them over to a smaller model to generate summaries.
However, this does not mean that the background summary overhead has been completely eliminated. On October 29, some developers still reproduced related requests on Claude Code version 2.1.312. Another developer counted 129 background agent sessions within 30 days, and found that agent_summary accounted for about 14% of the request volume and 10% of the estimated cost, and even reached 24% in a session containing 40 agents.
This also shows that the problem is not simply too many background requests, but the context size, cache hit rate, model selection and refresh frequency jointly determine the final cost. For long-running agents, even if each request can hit the cache, repeatedly reading hundreds of thousands of Tokens of context will still generate a considerable overhead when accumulated.
2 How can AI programming tools provide stable services?
The fundamental reason why developers are willing to invest a lot of budget in AI programming is that it may bring real productivity improvements. However, the increase in tool usage does not mean that the revenue increases proportionally, and how to measure the input-output ratio (ROI) is becoming a new problem.
While quota adjustments affect users, they will in turn affect the business model of AI programming tool vendors themselves.
Fixed monthly subscriptions and pay-as-you-go billing have different economic logics. For API businesses that charge by Token, the more users consume, the more revenue vendors usually get; but for fixed monthly subscriptions such as Pro and Max, the price paid by users is relatively fixed, but the reasoning cost may continue to increase with usage. Especially when Agents can run autonomously for a long time and call multiple sub-agents in parallel, a small number of heavy users may generate computing power costs much higher than ordinary users.
Anthropic's infrastructure investment also illustrates this pressure. Its IPO document also points out that computing power is Anthropic's largest cost item, and the company's commitment to computing power and infrastructure expenditure to partners in the next 10 years exceeds 600 billion US dollars, and a considerable part of the contracts are non-cancellable or do not depend on actual usage. For such vendors, computing power is not only the foundation of product supply, but also a major cost that must be managed for a long time.
Therefore, tightening quotas can control the cost per user in the short term and protect the gross profit of the subscription business; increasing quotas is conducive to attracting heavy developers, enhancing product stickiness, and expanding the usage scale of enterprise customers. However, if vendors frequently change the usage rights that users have formed expectations for, it may damage brand trust, and even prompt enterprises to establish a multi-supplier strategy to reduce their dependence on a single product.
What AI programming tools ultimately sell to developers is not just model capabilities, but a kind of R&D productivity that can be continuously called. If vendors cannot allow users to accurately predict costs and cannot guarantee the continuous operation of critical workflows, then even if the model capabilities are strong, developers may choose to limit usage, diversify suppliers, or even re-evaluate procurement plans.
Reference Links:
https://x.com/thsottiaux/status/2115850175868727621
https://github.com/anthropics/claude-code/issues/86879
https://news.ycombinator.com/item?id=50284255
https://www.businessinsider.com/openai-codex-usage-limit-warroom-fix-issue-2026-6
https://community.openai.com/t/day-25-wasnt-a-2x-improvement-for-existing-pro-200-users-stop-calling-a-canceled-downgrade-an-upgrade/1410852
https://gist.github.com/flamerix-ai/c3905705cc4205e5de3011fa2e74efce
https://www.reuters.com/legal/litigation/anthropics-ipo-close-look-ai-frontrunners-rapid-growth-spiraling-costs-2026-10-26/
https://www.theverge.com/ai-artificial-intelligence/990313/anthropic-class-action-lawsuit-pricing-subscription-plans
This article is from the WeChat official account "InfoQ" (ID: infoqchina), written by Chu Xingjuan, published with authorization from 36Kr.