Grok 4.7 is here, and netizens' real-world tests broke SpaceX immediately, let's launch the big rocket!
It seems obvious that Elon Musk is well aware that these days around the National Day holiday are tough for the foundational model circle.
So he's staking his claim early — Grok 4.7 is here!!!
With a larger base model, context window extended to 500,000 Tokens, it focuses heavily on training for Coding, Agent, and complex tasks that often run for hours.
It delivers all-round outstanding performance in Software Engineering, Electrical Engineering, long-duration office work, terminal operations and legal tasks.
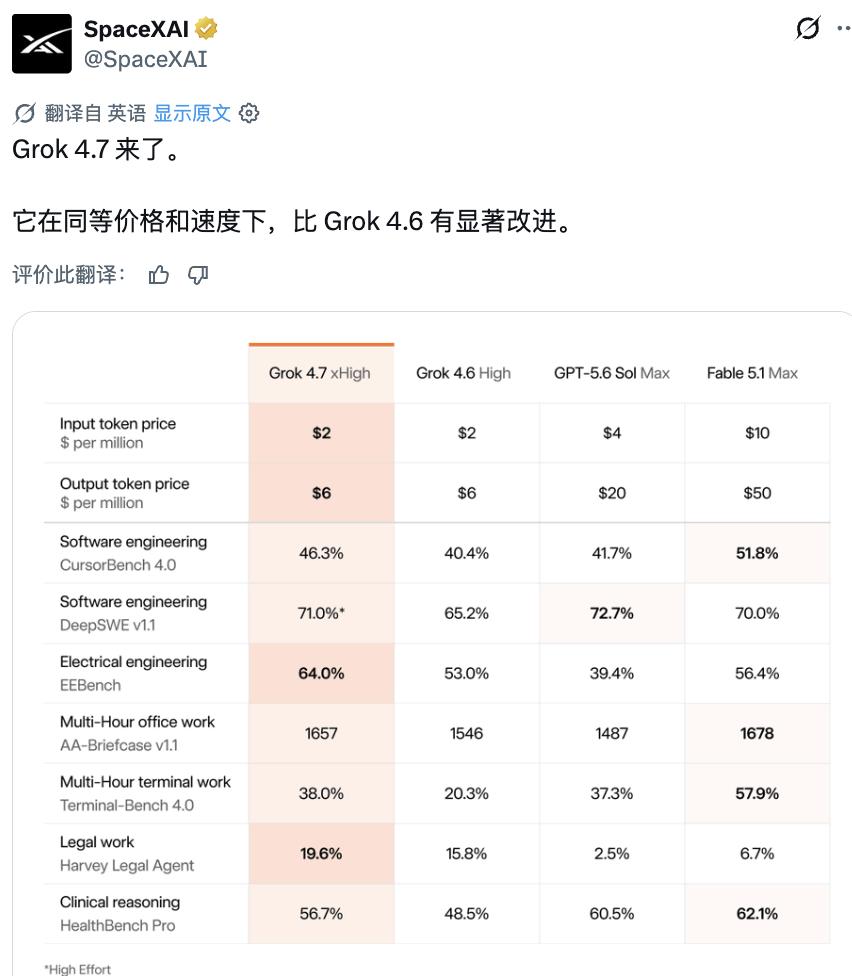
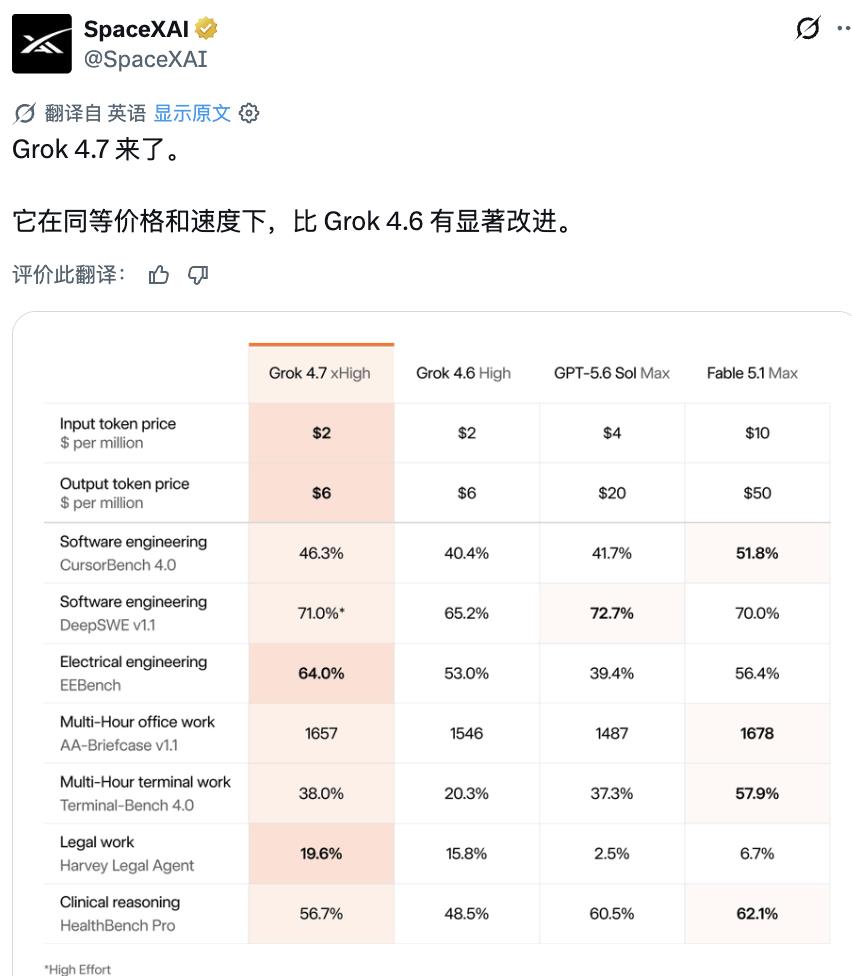
In the official evaluation table, it took the first place in the electrical engineering benchmark test with a score of 64%, and its terminal operation benchmark test score even jumped from 20.3% to 38%~
Of course, the price is also very attractive: $2 per million input Tokens, $6 per million output Tokens. It's truly a case of more volume without extra cost.
Who could have expected that right after the model was released, the actual test results from netizens started to go off the rails.
Coding? Agent? Legal reasoning? Let's put those aside for now~
Just like they had agreed on a secret code in the group chat in advance, the first thing everyone did after opening Grok 4.7 was — LAUNCH A ROCKET!
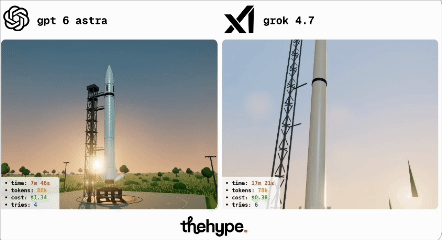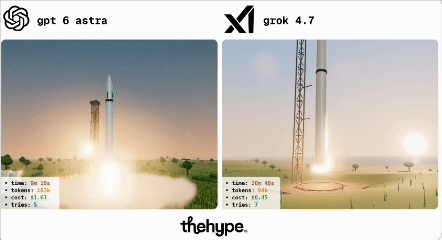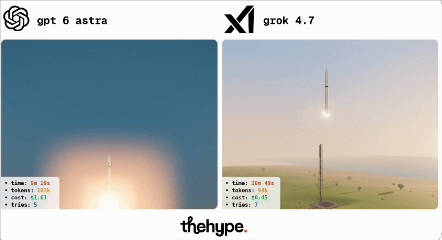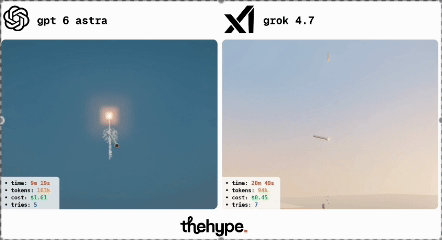
Here, @TheHype. directly staged a grand "space launch" show. Believe it or not, this rocket even flies faster than the one from the competitor:
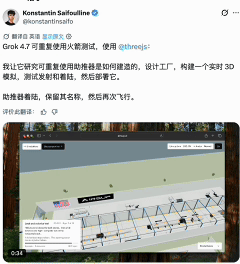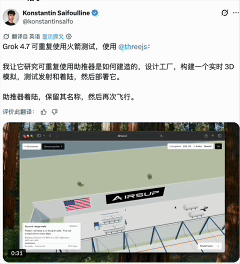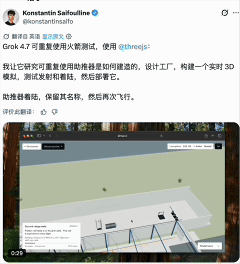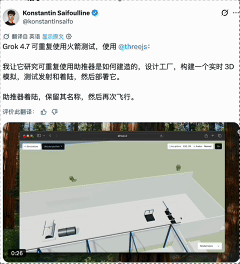
There's also this guy below, who directly asked Grok 4.7 to generate a 3D rocket project for him, complete with the model and launch pad, which can even do a test flight on the spot??
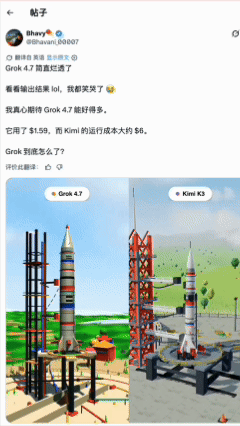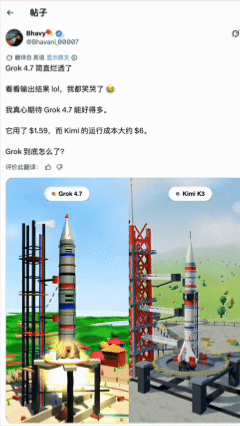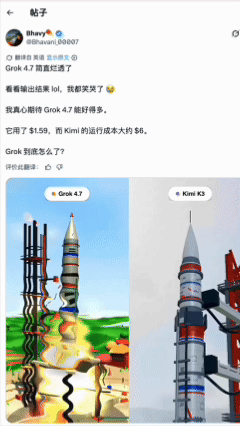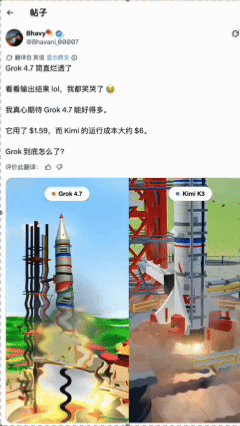
Some netizens who love to watch the fun even dragged Kimi K3 and Grok 4.7 together to the rocket launch site for an open-book test on the same topic!
After this round of testing, Grok somehow failed to keep up and directly crashed into a dizzy state, and netizens were not buying it anymore:
Elon Musk: You guys are all using it like this on me???
SpaceX: What did I do wrong again???
Grok 4.7 is Specially Trained for Complex "Heavy-Duty Tasks" This Time
To put it in one sentence.
Grok 4.7 is clearly built to handle "heavy-duty tasks".
Judging from the publicly available evaluation results so far, the improvements of Grok 4.7 this time are quite concentrated, mainly focusing on Coding, Agent and long-duration tasks.
First, let's look at the evaluation performance given by xAI itself.
The score of Software Engineering CursorBench 4.0 rose from 40.4% of the previous generation to 46.3%, and the score of DeepSWE v1.1 also increased from 65.2% to 71%.
The score of Electrical Engineering EEBench has increased even more dramatically —
It is 11 percentage points higher than the previous generation, taking the highest score among the four models in the table, showing quite obvious gains in professional engineering tasks.
The score of Legal Agent also rose from 15.8% to 19.6%, directly widening the gap with GPT-5.6 Sol and Fable 5.1 listed in the table:
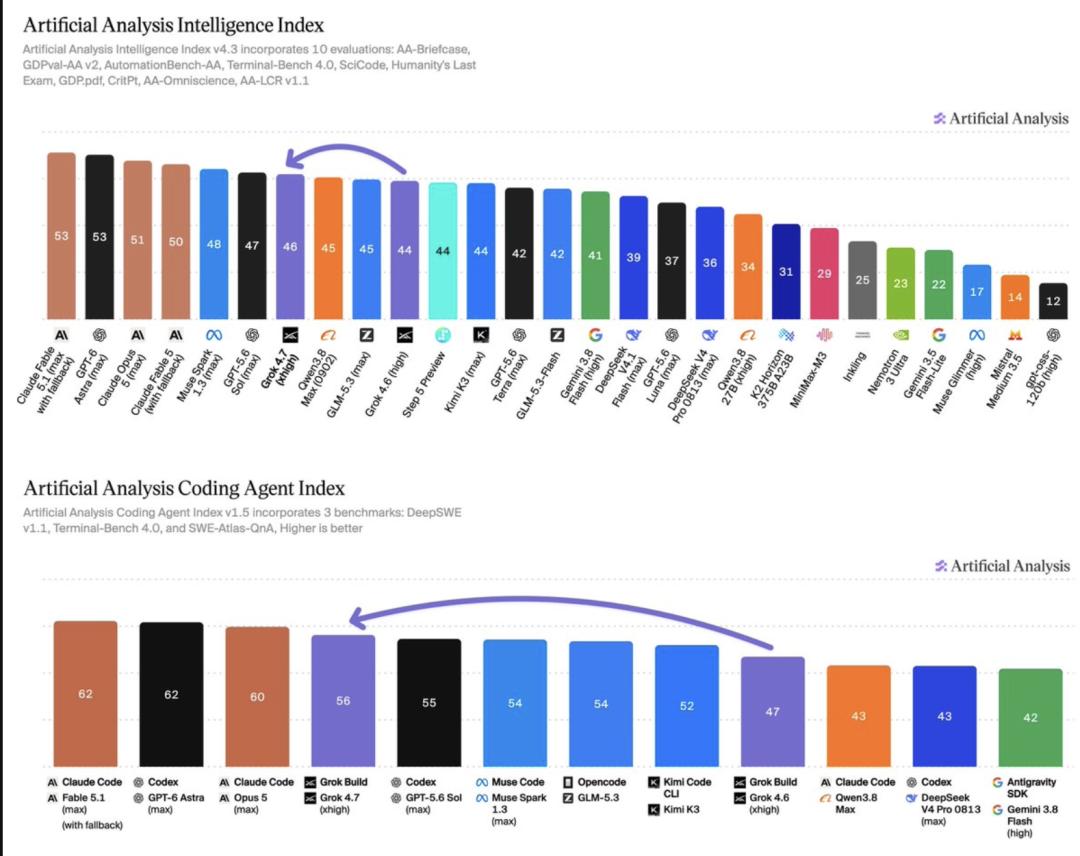
Next, let's take a look at the third-party Artificial Analysis ranking.
It scored 46 points in the comprehensive intelligence index, ranking right after the first tier. When it comes to the more targeted Coding Agent Index, its score reached 56 points, ranking 4th, which is a huge improvement from the 47 points of Grok 4.6.
Grok 4.7: If I can't beat the competitor, can't I at least beat my previous self???
Of course, Grok 4.7 not only has higher scores this time, but also its performance-to-cost ratio has been improved.
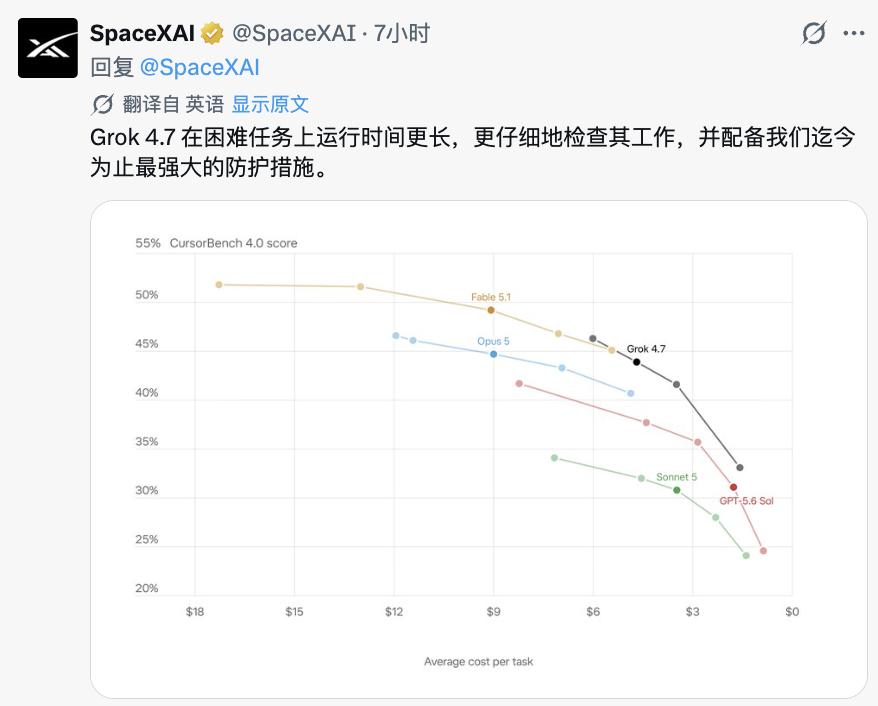
In the CursorBench 4.0 cost curve given by xAI, the score of Grok 4.7 can continue to rise as the budget for a single task increases.
At the position of about $4~$5 per task, it can already achieve a score of about 43%, and further increasing the budget can push it close to 46%.
Checks show that under the same budget, GPT-5.6 Sol is still around 37%, with a gap of about 6 percentage points...
emm... This also shows that for this generation of models, spending a little more reasoning budget on complex Coding tasks can indeed stably bring corresponding capability gains???
Right After Testing Rockets, Grok 4.7 Was Dragged by Netizens to Develop Games and Build Bridges!
What's more entertaining than the release of Grok 4.7 itself is the various tests done by netizens.
Right after they finished testing the rocket launch function, everyone has dragged Grok 4.7 to various scenarios to push its limits.
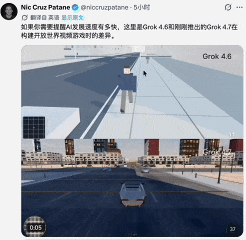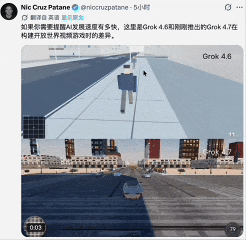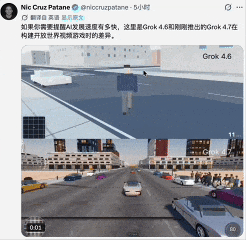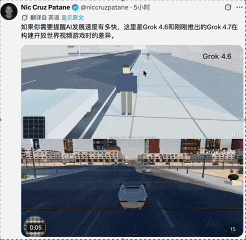
The following is a comparison of the open game world generated by grok 4.6 and grok 4.7, and the difference in visual experience is indeed very obvious.
Version 4.6 still has a bit of that pixel mini-game vibe, with flat visuals and relatively simple modeling?? (in my personal opinion)
Version 4.7 has a much stronger sense of realistic modeling, with more solid details in buildings, roads, lighting, and scene elements, and it already looks like a proper 3D game Demo:
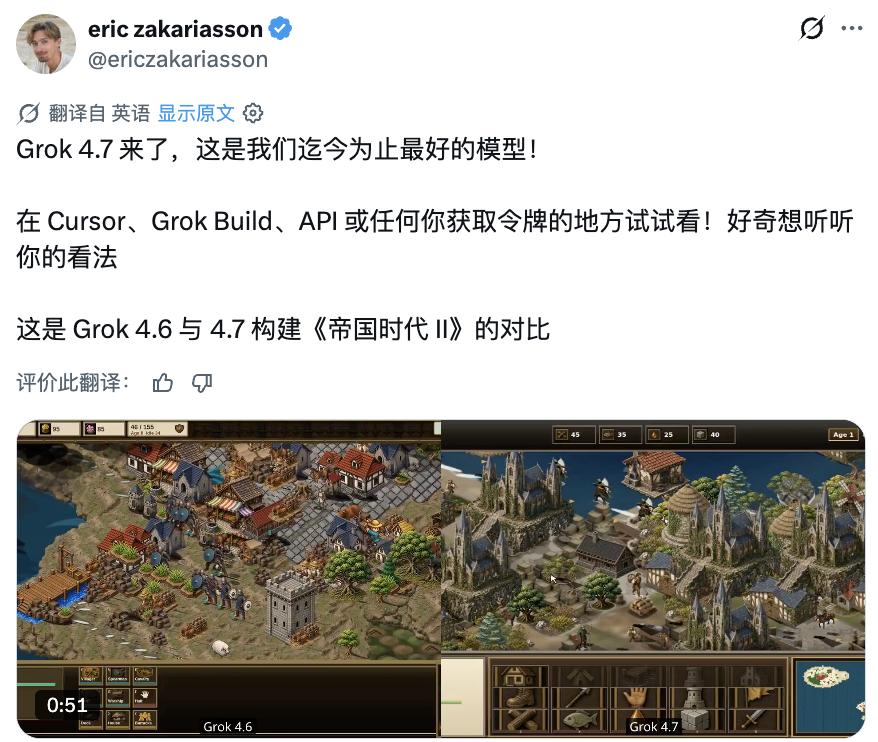
Then, look at this guy below, who directly asked Grok 4.7 to generate a full version of "Age of Empires 2".
Judging from the visual details, it does have better architectural detail than the previous generation, but the color scheme of version 4.6 looks better, each has its own strengths, what do you guys think?
Moving on, the difficulty level keeps increasing.
Some netizens directly imported Grok 4.7 into Blender, and asked it to build a Golden Gate Bridge on the spot.
The whole process only took 17 minutes, with close-up views, distant views, and detailed shots all included. The bridge structure and the overall rendering look pretty well-made.
Judging from the screenshots shared by this guy — the time spent on this is totally worth it!!!

Let's look at another user below.
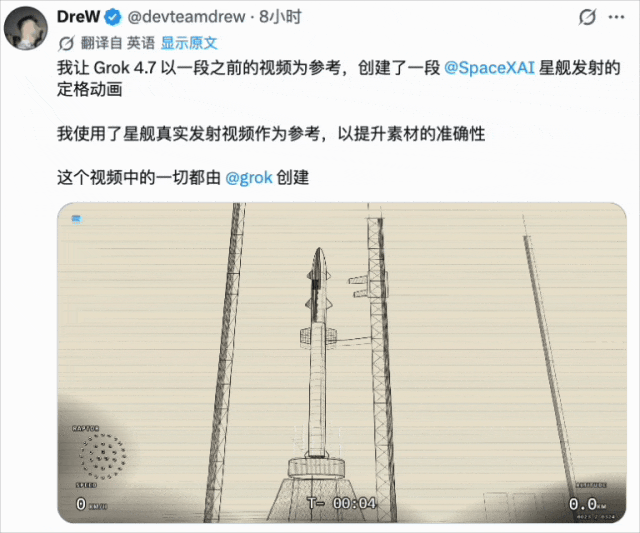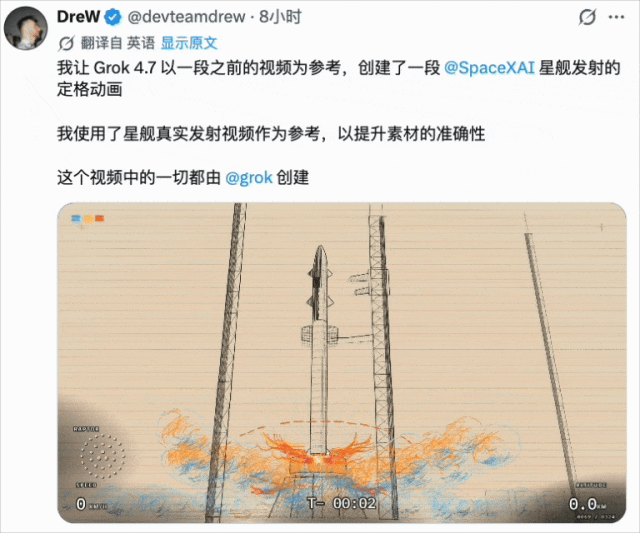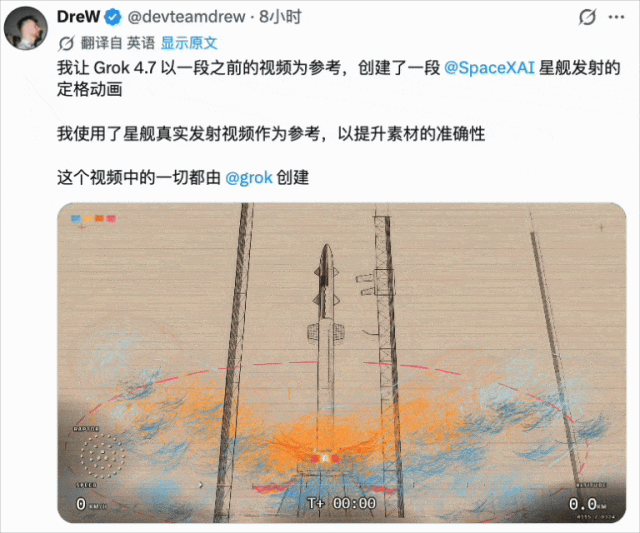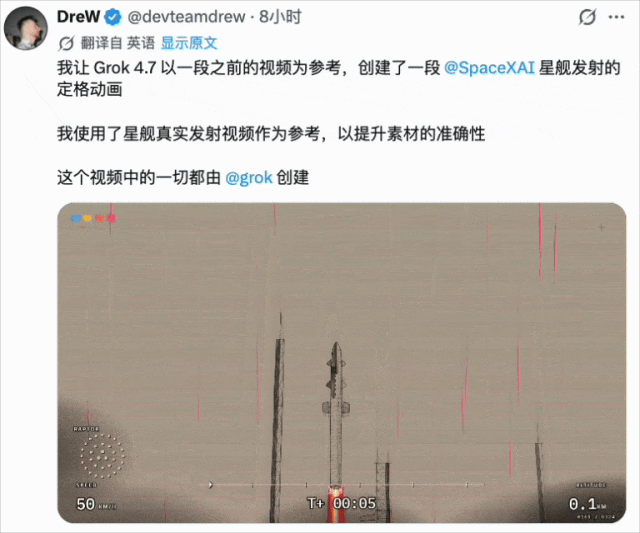
He fed Grok 4.7 a real SpaceX Starship launch video as reference material, and asked it to regenerate a stop-motion animation based on the real footage.
The final generated video is presented in a style similar to hand-drawn engineering sketches / retro stop-motion animation:
When it comes to mini-games, someone quickly came out to expose its flaws.
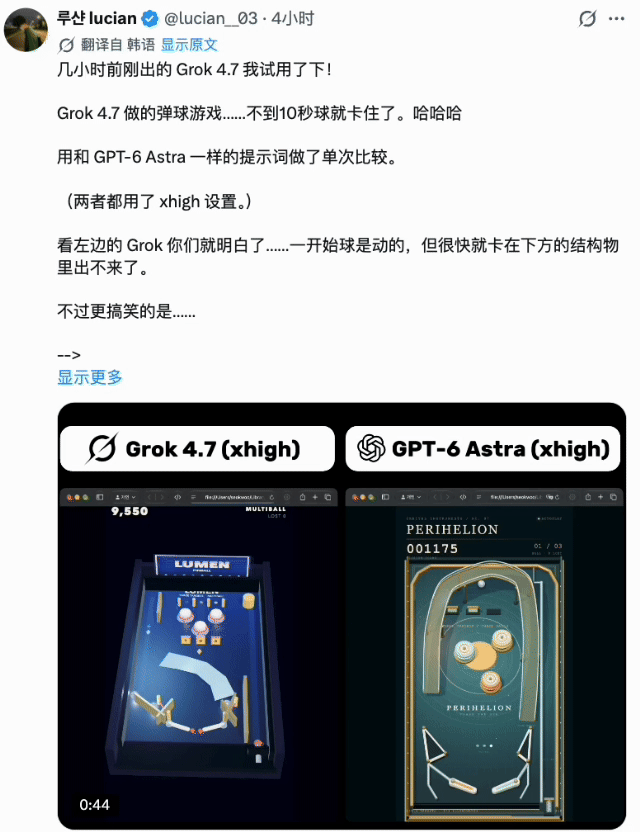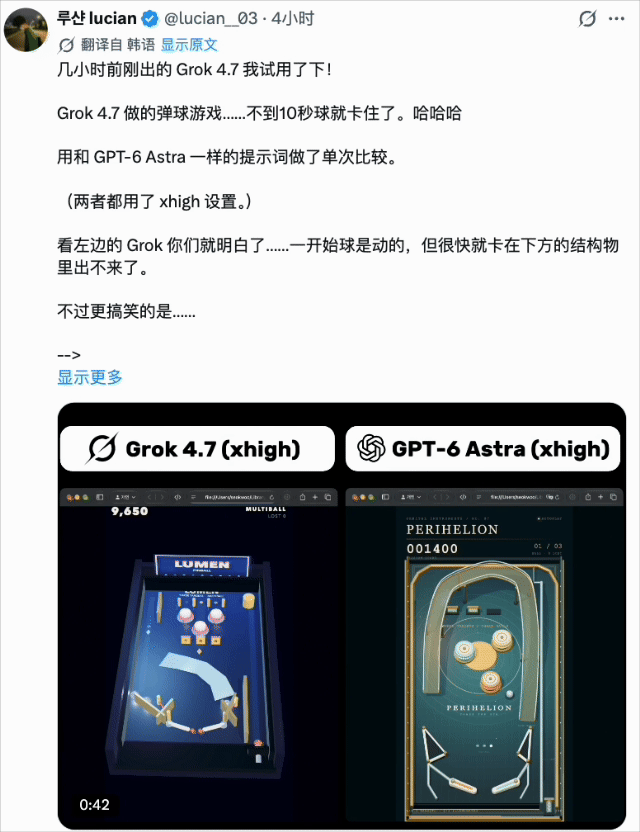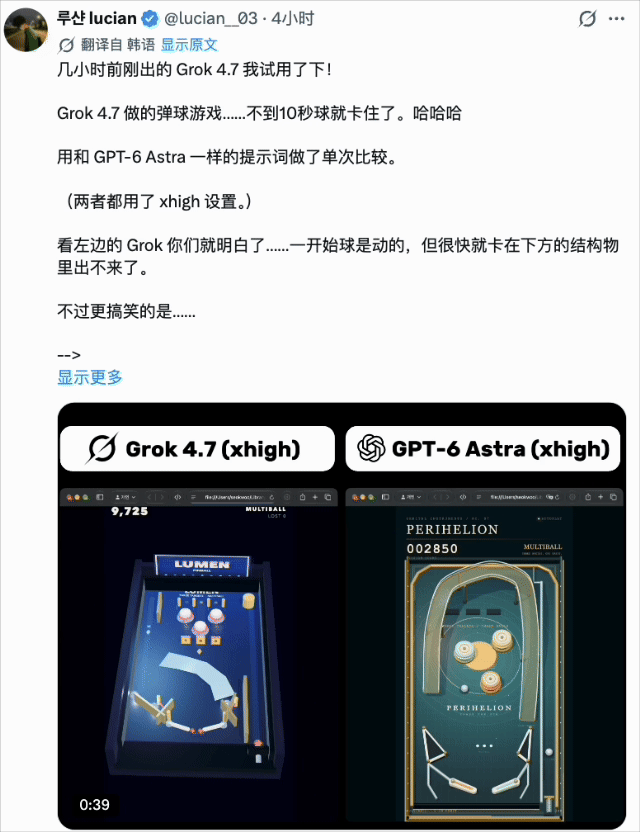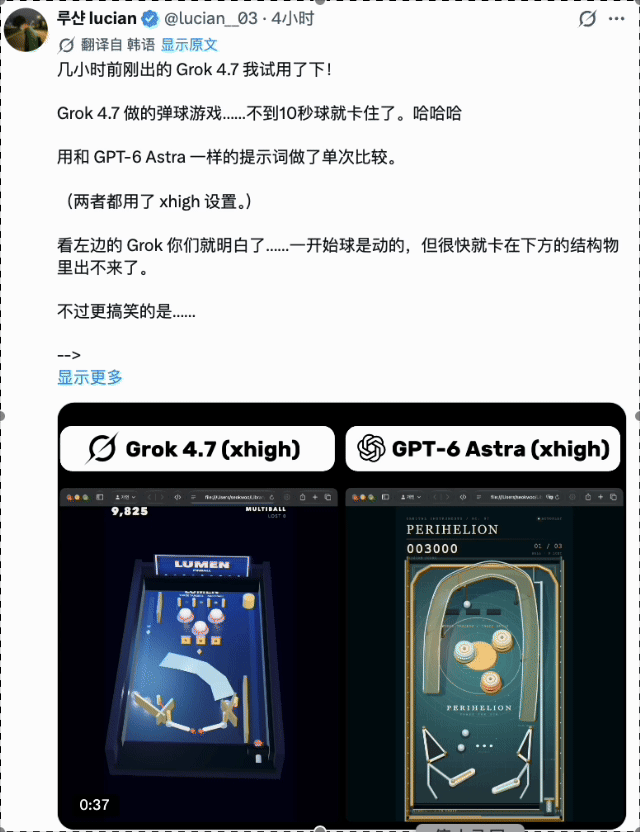
Some netizens asked Grok 4.7 and GPT-6 Astra to each write a pinball game, and then an awkward scene happened —
Our Grok performed quite normally at the start, the ball could bounce and the game ran smoothly, but less than 10 seconds later, the ball got stuck and stopped moving completely.
It can handle super heavy-duty tasks, but struggles with a tiny pinball!!!
Counting down, there are only a few days left before the National Day, when the global foundational model showdown is expected to happen.
Isn't this a typical case of releasing at a staggered time to avoid peak competition?
The competitor Anthropic's Claude 5.2 is just around the corner.
The internal test results of Google Gemini 4 Pro are going viral, and it is even suspected that it has secretly joined the Arena under a pseudonym to take the evaluation test.
Domestic manufacturers are also gradually increasing their stakes in the game. These days around the National Day holiday look like another concentrated period for foundational models to submit their exam papers.
Releasing Grok 4.7 at this point in time is quite a brilliant strategy, isn't it?
Reference Links:
[1]https://x.com/SpaceXAI/status/2102069815225586149?s=20
[2]https://x.com/SpaceXAI/status/2102069817893150777?s=20
[3]https://x.com/ArtificialAnlys/status/2102074898327932987?s=20
This article is from the WeChat official account "QbitAI", written by Meng Yao, authorized for release by 36Kr.