The most popular mute model Jev combined with WeChat has directly cured my low EQ.
Google's dumb model Jev has suddenly exploded in popularity,
It does not chat, write code, draft copies, or provide explanations. No matter what you ask it, it will not generate a single word. It only does one thing — making judgments.
Just a few days after its release, from Hacker News to Chinese tech communities, almost everyone is discussing it. But people are not talking about how smart it is, but how abnormal it is.
Indeed, the fact that a non-verbal model can go viral is abnormal enough in itself.
The first topic people discussed is its implementation scenarios. Where can a non-verbal model be deployed? The answer is WeChat.
WeChat needs to reply to messages, manage groups, and monitor risk control, all of which seem to be tasks that should be handed over to a "talkative" large language model.
Things that seem totally unreasonable have happened reasonably in this way.
But to figure out the specific situation, we have to start with Jev itself first.
01
What on earth is Jev
TypeSafe AI released Jev on September 16, 2026.
This is a San Francisco-based company founded by Diogo Almeida, co-author of the GPT-4 paper and former OpenAI researcher. The company has been doing stealth R&D for two years, and came out with a $40 million seed round led by DCVC.
Jev labels itself as a System One Model.
The name comes from Daniel Kahneman's book *Thinking, Fast and Slow*. In the book, System 1 refers to the kind of intuitive judgment that requires no deliberate thinking, while System 2 refers to the slow, step-by-step reasoning process.
According to TypeSafe, in recent years everyone has been building System 2 models that can think, write long articles and give explanations. But most of the judgments actually needed in software belong to System 1.
The difference between Jev and ChatGPT, Claude is that Jev can only answer multiple-choice questions, while other models can write full essays.
The usage of Jev is as follows: you feed it a piece of status, such as an email, a line of log, a work order, or a segment of program status, then provide it with several pre-defined questions, it will return all the answers at once, with a probability attached to each answer, plus a confidence level showing "how certain it is of the result".
It only answers three types of questions.
Choice: Pick one from up to 255 options.
Score: Assign a score on a scale ranging from 2 to 10 levels.
Noul: Output a yes/no probability between 0 and 1.
The three types of questions can be mixed in the same request, and they are calculated in parallel. The official states that the latency is almost the same whether you ask one question or four questions.
Jev is characterized by high speed and low cost.
Ordinary large language models generate output word by word, and the generation duration depends on the length of the content to be written. Jev does not generate text, the scope of answers is pre-defined, and it only needs to calculate the probability of each option once to finish the task.
According to official data from Jev, the end-to-end response time ranges from 70 to 500 milliseconds, it charges $0.042 per million input tokens, and outputs are free. After it was launched on Vercel's AI Gateway, nearly 13% of Vercel's paid teams adopted Jev within 24 hours, making it the fastest adopted new model on the Vercel platform.
It cannot chat, write code, draft copies, process images, or explain the reasons for its outputs. If you ask it "why not choose this option", it will not reply, it only returns numerical values.
Another feature of Jev is that its hallucination rate is 0%.
This means it will never give an answer outside the options you provided, and will never misspell fields. But it can definitely choose the wrong option, which Diogo, the CEO of TypeSafe, has admitted himself.
The name Jev comes from the Jevons paradox.
When the efficiency of steam engines improved and the cost of coal per ton decreased, the total coal consumption instead increased, because the cheaper power was applied to more scenarios.
In the past, AI was unaffordable, because invoking a large language model once was expensive and slow, and it was not cost-effective to call it just for a tiny trivial judgment. Now Jev has reduced the cost of a single judgment to 1/10000 of a US dollar.
Its training method is called RLCD, Reinforcement Learning for Calibrated Decisions. RLHF pursues "outputs that humans like", RLVR pursues "outputs that programs can verify for correctness", and RLCD pursues "honest probability outputs".
If RLCD says it is 70% certain, it means that the probability of the result being correct is 70% in mathematical verification.
02
Jev has become a plugin for WeChat
After Jev went viral, the most common use case for it in the community is to act as a WeChat plugin.
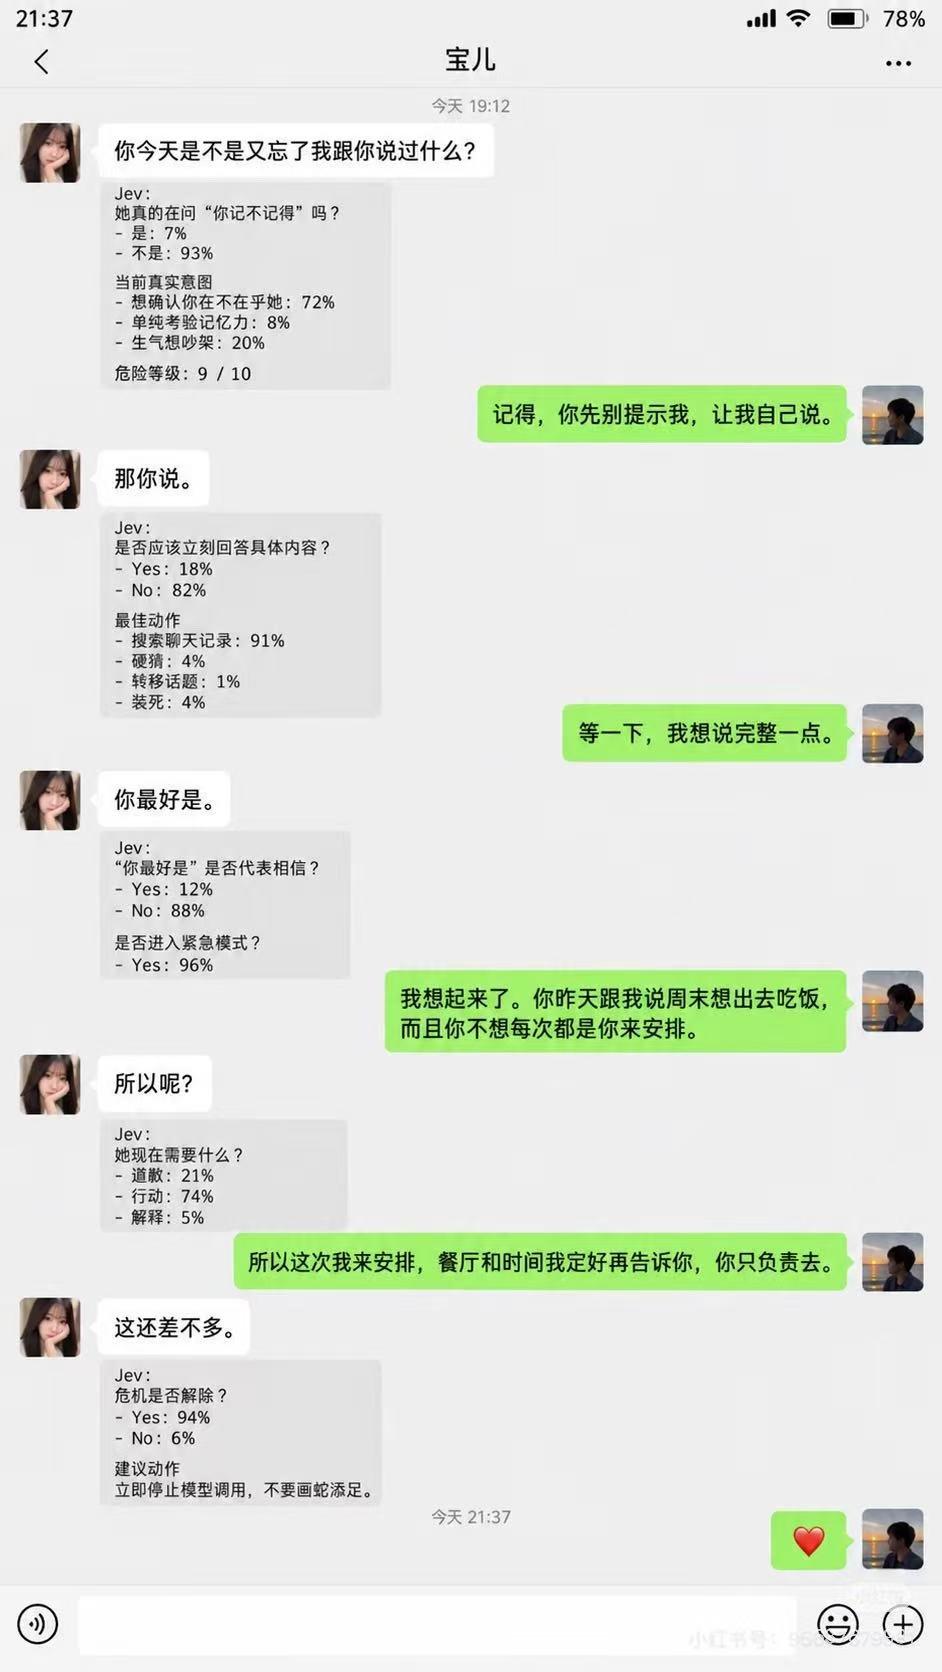
The hardest part of using WeChat is how to accurately grasp the other person's intention. For example, the classic phrase "you handle this as you see fit". What exactly should you do? Make minor adjustments? Leave it alone? Or make drastic changes?
This is exactly where Jev's value comes into play.
Should I reply to this message?
Should I tag this person?
Is this message an advertisement?
Should I remove this person from the group chat?
Should this case be transferred to human customer service?
Does this person want to apply for a refund?
Does this content violate regulations?
Every one of these tasks is "pick one from limited options", and the result needs to be output within hundreds of milliseconds. This is exactly the scenario that Jev is designed for.
Then why not use a regular large language model?
There are three reasons.
First, it is slow. A large language model takes 3 to 30 seconds to generate a reply. Messages in WeChat group chats scroll continuously, if you reply after 30 seconds, the other party may get impatient. Jev responds in 70 to 500 milliseconds, fast enough for you to reply before the message scrolls out of the screen.
Second, it is expensive.
WeChat bots usually run on low-cost always-on servers or lightweight servers, so the cost of a single judgment must be low enough to be negligible. Using a large language model to judge each message one by one will generate considerable real costs when there are hundreds of thousands of messages. Jev charges $0.042 per million input tokens with free outputs, reducing the cost of a single judgment to the order of 1/10000 of a US dollar.
Third, which is the biggest concern for WeChat plugins, it cannot say anything wrong.
If a free-generating large language model is embedded in a chat box, it may spit out inappropriate content at any time, ranging from causing social embarrassment to triggering risk control mechanisms and resulting in direct account bans. Jev does not generate text at all, it only selects from the options you provide, so it is structurally impossible to output out-of-bound content.
The long-standing pain point of WeChat plugins is the line between "automatic reply" and "transfer to human".
Fully automatic processing cannot guarantee content control; transferring all cases to human staff will cause unbearable workload for employees. Jev assigns a calibrated confidence level to each judgment, so this line becomes a threshold: process automatically when the confidence is high, transfer to human staff or a more expensive large language model when the confidence is low.
This diversion mechanism of "automatic processing for high-confidence cases, escalation for low-confidence cases" is exactly the structure that WeChat customer service and community operation teams have long wanted.
There is also a hidden point: traditional rules trigger replies when keywords are hit, kick people out when the word "advertisement" is detected, and respond when being tagged. These are all keyword matching mechanisms. If the other party changes their wording and does not use the pre-set keywords, the automatic reply mechanism will fail.
Jev upgrades "keyword matching" to "semantic judgment". It still makes decisions on whether to reply or whether to kick people out, but the judgment basis is no longer keywords, but the actual intention of the user.
The installation process is also very simple: just type "npx skills add typesafe-ai/skills" to Codex, or add the plugin marketplace in Claude Code. You can call it immediately through OpenRouter.
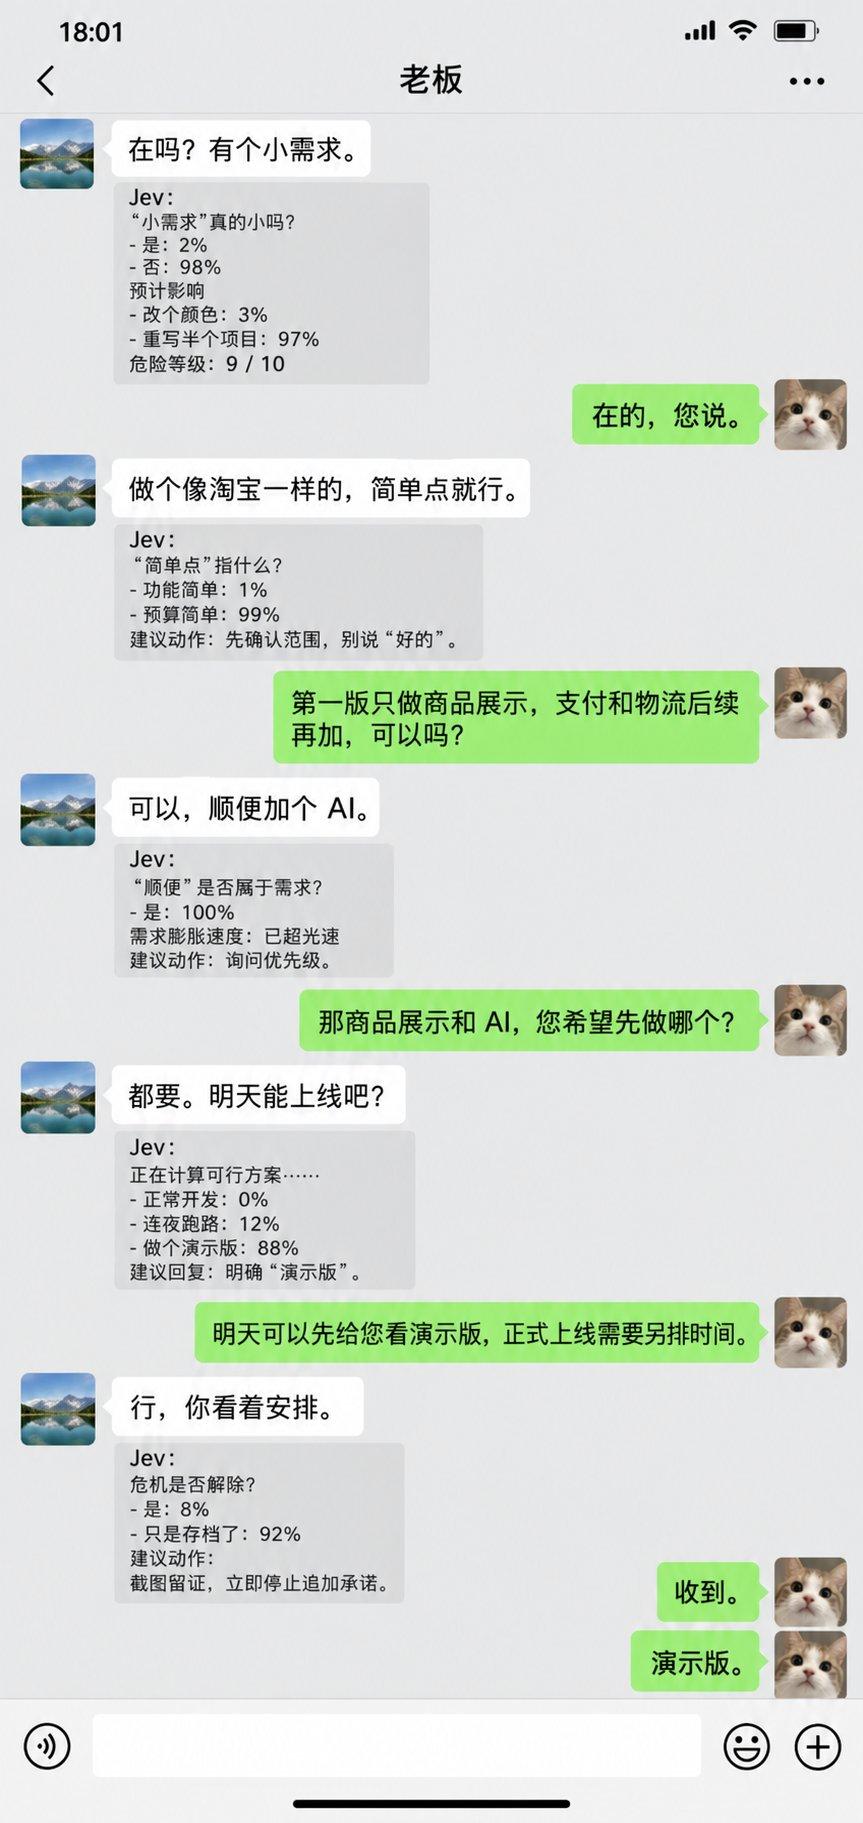
Many mature products have emerged online, such as wechat-jev-hud, which is a WeChat HUD running on Windows. It identifies message bubbles by screenshotting and locating the chat area, and embeds Jev between OCR and the overlay layer to make real-time judgments.
Then you can see the effect shown in the picture: for each message from the other party, it shows the probability that the message refers to different types of content.
03
Shifting from generation to judgment
Jev became popular so quickly because it addresses a major pain point: why Agents are still slow, expensive and fragile.
The AI narrative in the past two years has been focused on longer context windows, smarter reasoning, and more polished responses.
But when you actually deploy a model into a system that runs hundreds of thousands of times every day, you will find that the vast majority of invocations do not require the model to "speak" at all, they only need the model to "make judgments".
For example, which department a customer service work order should be assigned to, whether a tool invocation carries risks, whether a segment of AI output deviates from the correct direction, and which button on the page should be clicked next.
These problems all have only one correct answer, and the options for the answers are already written in the code. Letting a model that is good at writing essays generate a long paragraph first, then having the program translate that paragraph back to a judgment, is taking a huge unnecessary detour.
What Jev wants to eliminate is exactly this detour.
Therefore, many people in the community commented that Jev is like adding a "semantic if statement" to software. If the other party shows a certain intention, then respond with the corresponding answer.
The effect is immediate: by integrating Jev into the browser Agent via Browser Use, you can select "what to do" and "which element to click" in a single request, reducing the time to book a flight ticket from 9.5 seconds to 7 seconds.
In long-running tasks, using Jev as a routing middleware to let it choose which model the Agent should use can also save a lot of time.
However, the claim that "Jev will replace large language models" is a false proposition. The correct approach should be: large language models help you work out clear judgment rules, while Jev executes these rules with high frequency and low cost in the production environment.
Its real value lies in calibration: quantifying those ambiguous problems that seem to have no standard answers, so that you can immediately know which answer to choose.
The WeChat plugin example has already shown that its first implementation scenarios will not be those "creativity-demanding" scenarios, but those high-frequency, low-cost, error-free scenarios.
The more frequent, trivial, and error-sensitive the judgment task is, the more suitable Jev is for it.
One speculation is that when judgment itself becomes extremely cheap, we might as well stop letting models generate text at all, and only let them make judgments. The judgment layer will become a default infrastructure layer just like databases and caches, embedded at the very bottom of every application.
The WeChat plugin is just the beginning.
But Jev has poor Chinese adaptation capabilities. The official documentation clearly marks that its accuracy for CJK (Chinese, Japanese, Korean) content is relatively low, and its performance on short English texts is relatively stable.
At the same time, Jev does not have reasoning capabilities.
In the long-range browser interaction test by the founder of Browser Use, Jev only got 1 correct result out of 20 tests, far behind GPT-5.6 Luna which has reasoning capabilities (17 correct results out of 20 tests).
Browser operations involve state space search and path backtracking, and Jev does not have the capability of multi-step state deduction.
Netizens in the community said that Jev cannot handle real complex non-sandbox web pages. It lacks the capability to deal with unprocessed DOM, asynchronous loading, and unexpected pop-ups on real web pages.
This article is from the WeChat official account "Letter AI", author: Miao Zheng, editor: Wang Jing, published by 36Kr with authorization.