OpenAI has acquired the core team behind iPhone's Portrait Mode, aiming to equip AI with a brand-new pair of eyes.
In the past week, two new mobile phone products have successively gone viral. One is Apple's newly released iPhone 18, the other is the consumer version of the Doubao Mobile Assistant, whose first preloaded model Nubia NaviX Ultra went on sale today. AI will be integrated into mobile operating systems, and we have also done a detailed review of it.
AI has begun to see the screen, and to reach out and interact with it. Meanwhile, *The Wall Street Journal* revealed that OpenAI has acquired camera technology company Glass Imaging for more than 300 million US dollars.
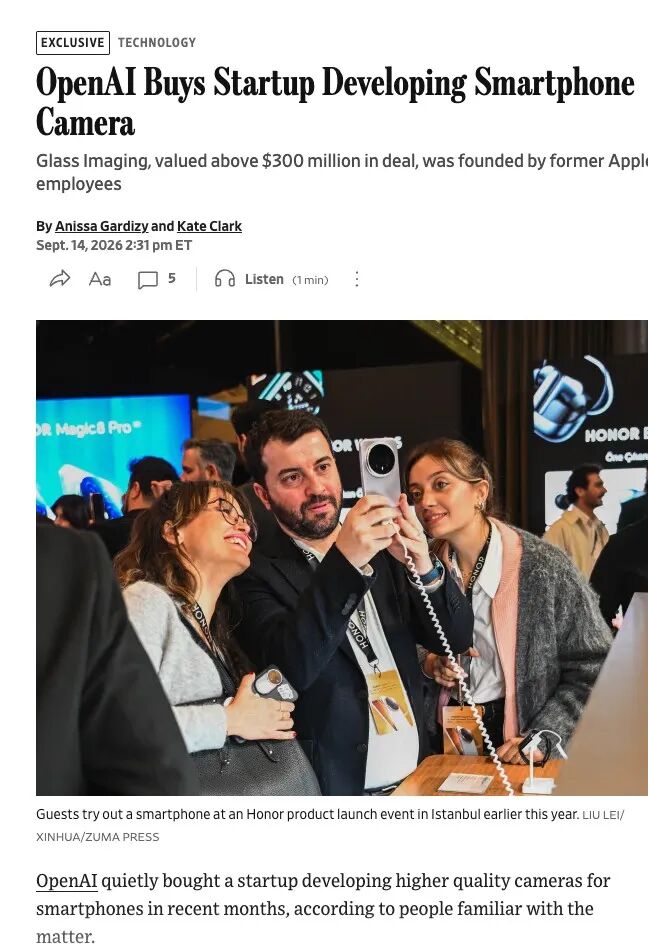
The transaction has not been publicly confirmed by OpenAI, but the position of this new puzzle piece is very subtle: Last year, after OpenAI spent 6.5 billion US dollars to acquire io, a hardware company founded by Jony Ive, it has not yet made remarkable achievements, but industrial designers and camera engineers have already joined the team one after another.
It's AI, but not photo-editing AI
Glass Imaging was founded by Ziv Attar and Tom Bishop, both of whom previously worked on computational photography at Apple and participated in the development of the iPhone Portrait Mode.
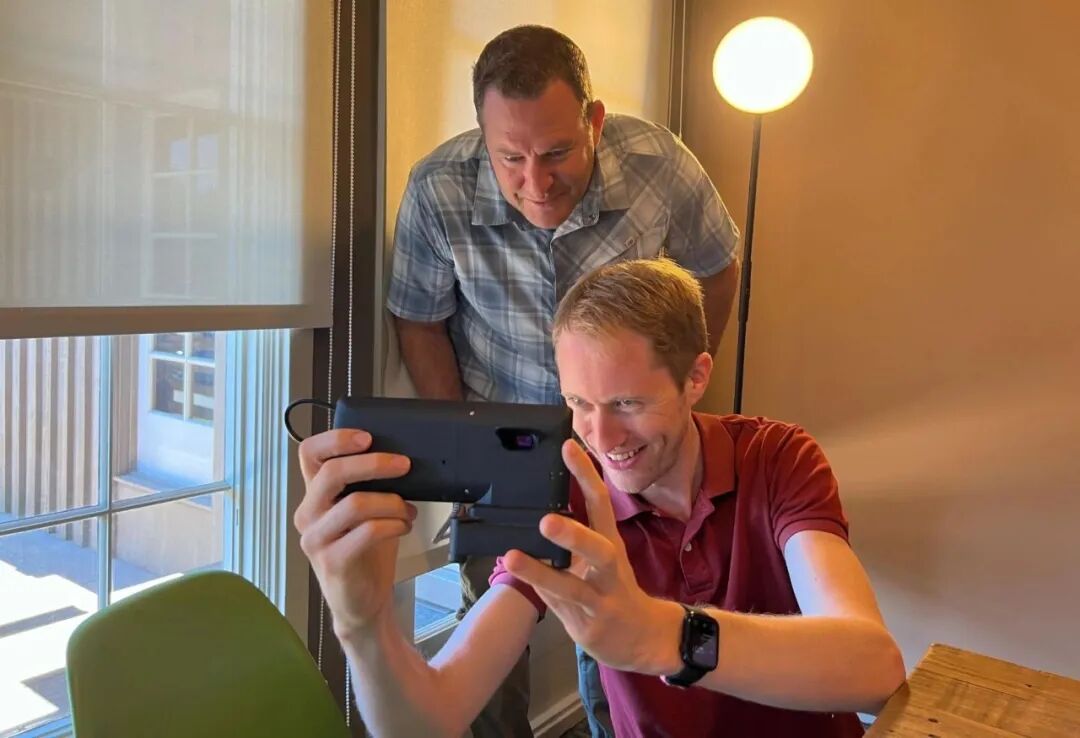
However, what Glass Imaging researches is not the most common AI photo editing today, but using AI to reversibly influence the design logic of camera hardware.
After you press the shutter on a mobile phone, what the sensor gets first is not a directly viewable photo, but a pile of raw light signals. The traditional image signal processor needs to complete processes such as noise reduction, color calibration, and sharpening before generating the final image on the screen.
Glass Imaging tries to use a set of neural networks trained for specific lenses and sensors to take over this entire pipeline. Its underlying technology is still Neural ISP. Traditional ISP will pass RAW data to modules such as demosaicing, noise reduction, multi-frame fusion, and sharpening in sequence, each step is processed by an independent algorithm, and part of the information will be lost in the process.
GlassAI starts from the RAW burst data of the sensor, puts demosaicing, noise reduction, deblurring, and multi-frame fusion into the same jointly trained network, and adds lens aberration deconvolution and sensor crosstalk correction that traditional ISP is not good at, and finally outputs the finished RGB image directly.
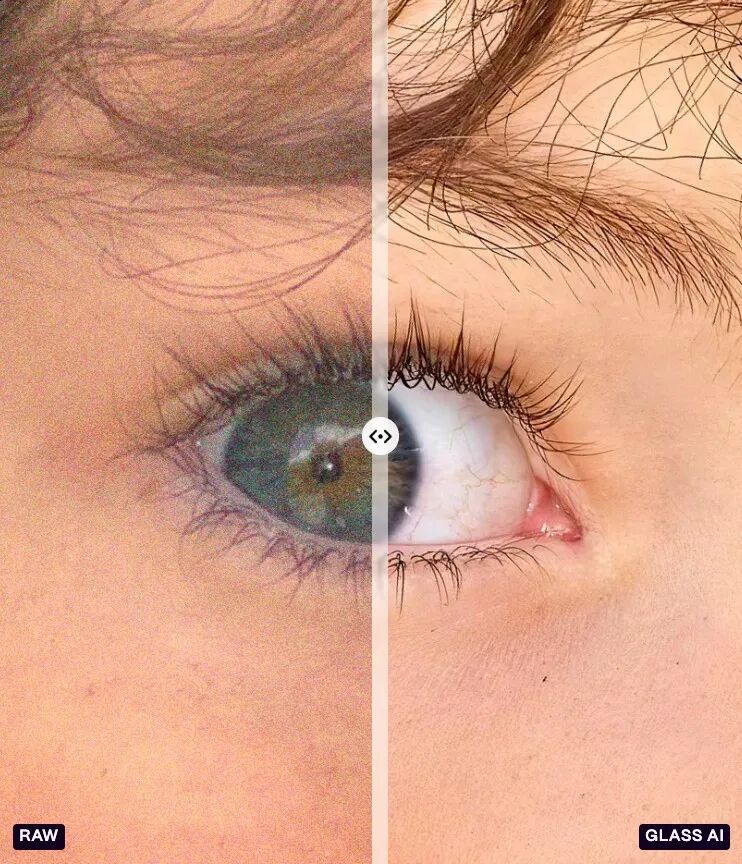
Based on Neural ISP, Glass Imaging has absorbed and rewritten a large number of core links of traditional ISP. What it needs to learn is how a camera generates errors, and then reverse the errors when the image is formed. The idea of Glass Imaging is that as long as the lens delivers enough information to the sensor, the remaining blur, chromatic aberration and distortion can be repaired by a specially trained network.
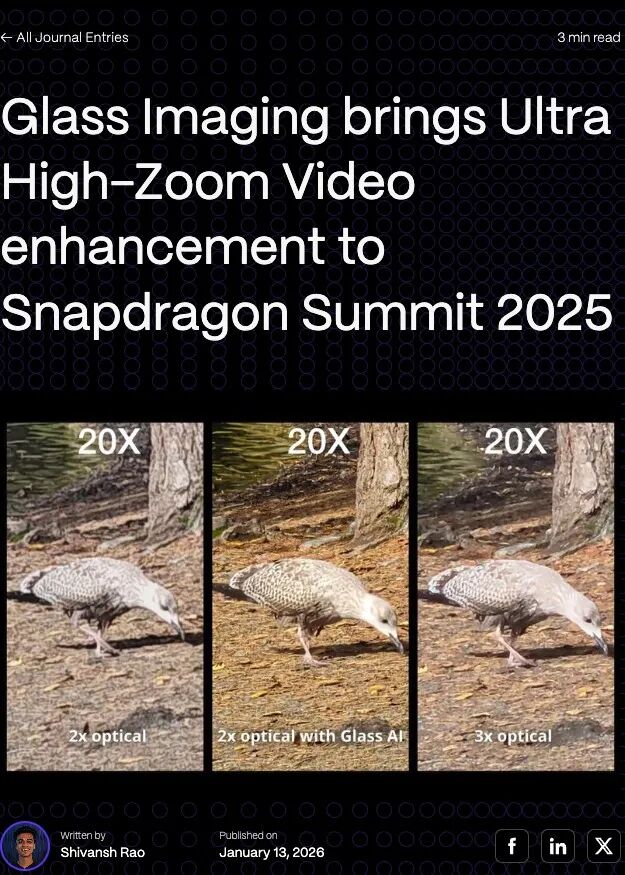
But the so-called "repair" here does not refer to the "editing" in the sense of AI photo editing. Generative photo editing can indeed "guess" the blurred text, the moon and human faces in the distance to be clearer, but clarity does not equal authenticity. According to Glass Imaging's materials, its network is trained for specific optical systems and RAW data, with the goal of restoring the information actually captured by the sensor, rather than generating new textures based on common sense and inference.
This is very different from the current main role of AI in image processing, the reason is: if the camera is only used to take photos for social media posts, it is enough for the photos to look good; but if the image is to be handed over to the Agent to judge the reality and take action, the objects and text made up out of thin air may lead to wrong operations — this is why we can understand why OpenAI is interested in it.
The two "viewing rights" of AI devices
For mobile phone manufacturers, Neural ISP technology allows smaller lenses to take clearer photos; but for a company that is manufacturing AI hardware, it has another meaning: the world the model sees first depends on what the camera delivers to it.
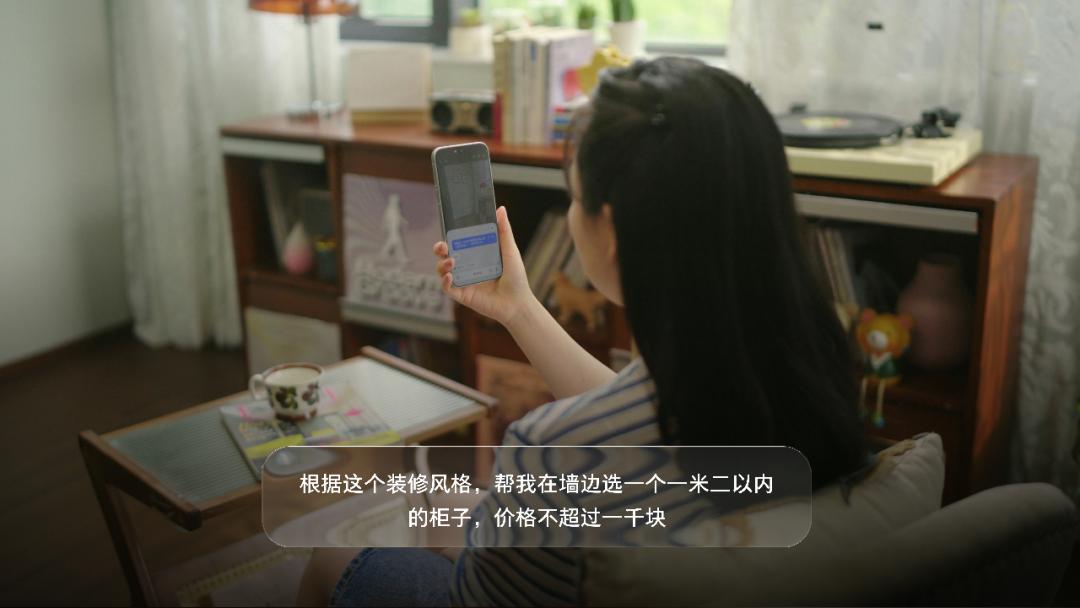
AI devices need two kinds of "viewing" capabilities. The first one happens inside the screen: AI needs to understand what the user is browsing, read what local information, and get the permission to call different Apps. On this basis, it understands the context in the entire operating system.
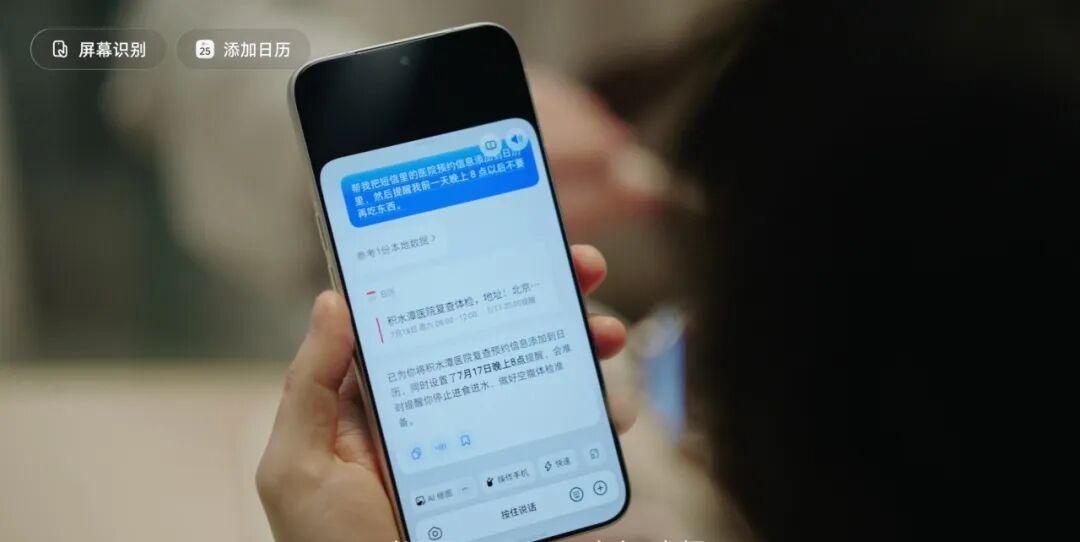
The second one happens outside the screen: the text on the menu, the objects on the table, the road in front of you and the devices in the room cannot be "known" by AI only through chat records. You need to take a photo first, and then hand the photo to AI.
Photos are the end point of human viewing, but they may only be the starting point for Agent to work. If future AI devices want to act in a timely manner, they must shorten the entire chain of "human seeing, shooting, uploading, and inquiring".
The identity of the camera has also changed accordingly. In the past, it helped people save the pictures worth looking back on, in the future, it will become the basis for the machine to judge the next action.
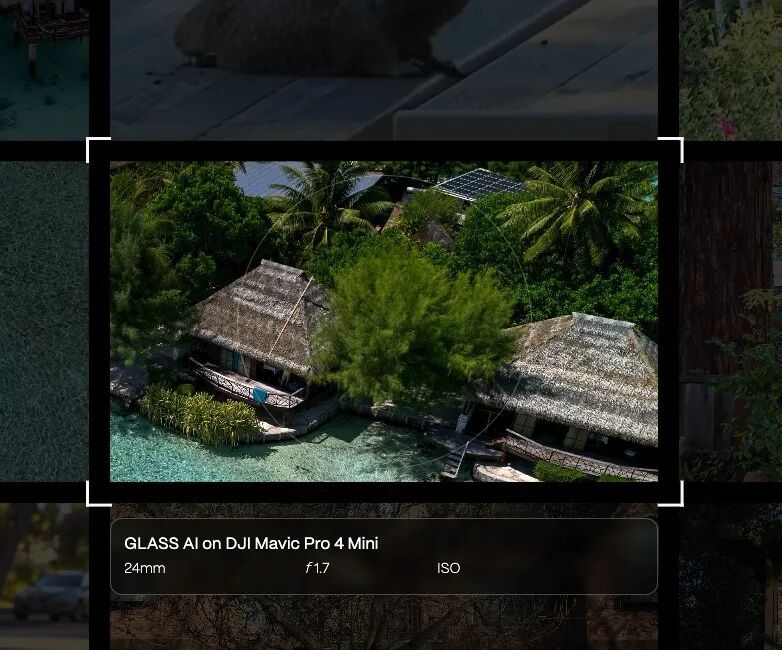
GlassAI's zoom technology has been integrated into the Honor 600 series, which shows that it has at least completed the adaptation from models, mobile phone chips to mass-produced devices; the company has also demonstrated real-time 4K video processing and more than 20x zoom enhancement on the Snapdragon 8 Elite Gen 5 reference device.
These capabilities are currently used to make people take distant objects more clearly, in the future, when the camera is connected not to the photo album, but to an Agent that is ready to take action, the evaluation criteria for imaging will change.
Photos should not only look good, but also present text, objects and spatial relationships as truthfully, stably and timely as possible, because the model may subsequently identify products, operate devices, and even plan actions based on these contents.
It's not that GlassAI will automatically turn cameras into agents, but it complements the most fundamental link before agents enter the real world: deliver the information actually seen by the sensor to the model as accurately as possible.
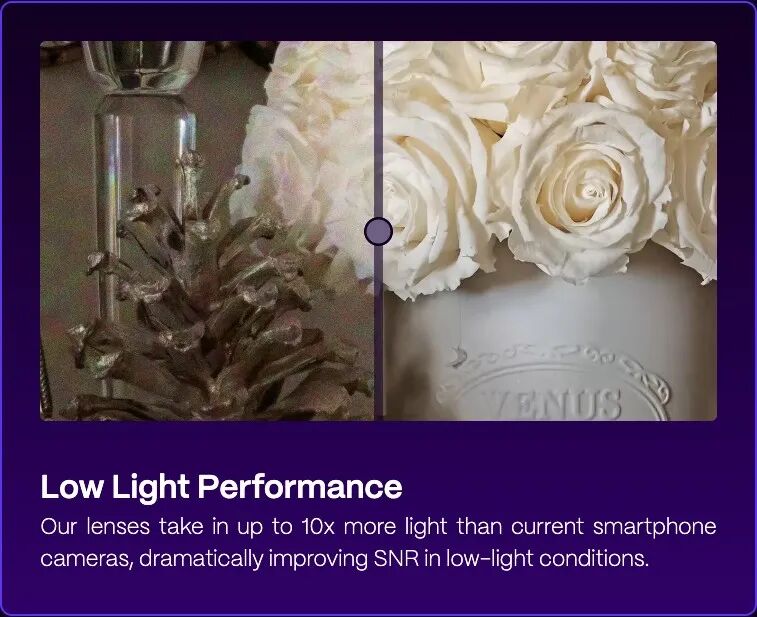
The first change revealed by Glass Imaging is that the division of labor between hardware and software has been redefined. In the past, camera manufacturers first tried to use lenses and sensors to solve aberration, blur and noise, and then let the ISP modify the final image; GlassAI allows the hardware to retain some defects that can be reversed by calculation. As long as the sensor still captures enough information, the specially trained network can restore it during the imaging process. As a result, the lens can be smaller, the pixel size can be further reduced, and part of the problems that originally required adding more lenses, increasing thickness and cost to solve are transferred to the neural network.
Then it is possible that the hardware of future AI devices does not need to be fully designed before "inserting a model" into it. Lenses, sensors, NPUs, memory and models will be designed together from the very beginning, which original signals the sensor is responsible for retaining, which errors the neural network can repair, how much local computing power the device needs, and whether it can continuously understand the environment in a low-power state... These issues will in turn affect the shape of the hardware.
For example, assuming engineers know in advance that certain optical defects can be stably repaired by neural networks, the next generation of cameras can tolerate defects that were unacceptable in the past when choosing the number of lenses, pixel size, sensors and body thickness. It may no longer completely eliminate aberrations by stacking more lenses, or it may ensure that the sensor still retains enough raw information before handing it over to AI for restoration.
The same logic may also extend to microphones, spatial sensors and other sensing components. In the past, hardware was responsible for recording the world as completely as possible, and software only processed it afterwards; in the future, hardware only needs to capture the information that the model can understand and restore, and the model will participate in influencing how the hardware should view the world from the very beginning.
The model is not responsible for deciding what the camera sees, but it will change how much hardware the camera needs to get an image that is sufficient to be restored and understood.
This article is from the WeChat Official Account "APPSO", the author is Discovering Tomorrow's Products, and it is republished with authorization from 36Kr.