Major Breaking Discovery: GPT-6 Astra Has Achieved a Breakthrough in Embodied Intelligence, How Should China Fight the Embodied Defense War?
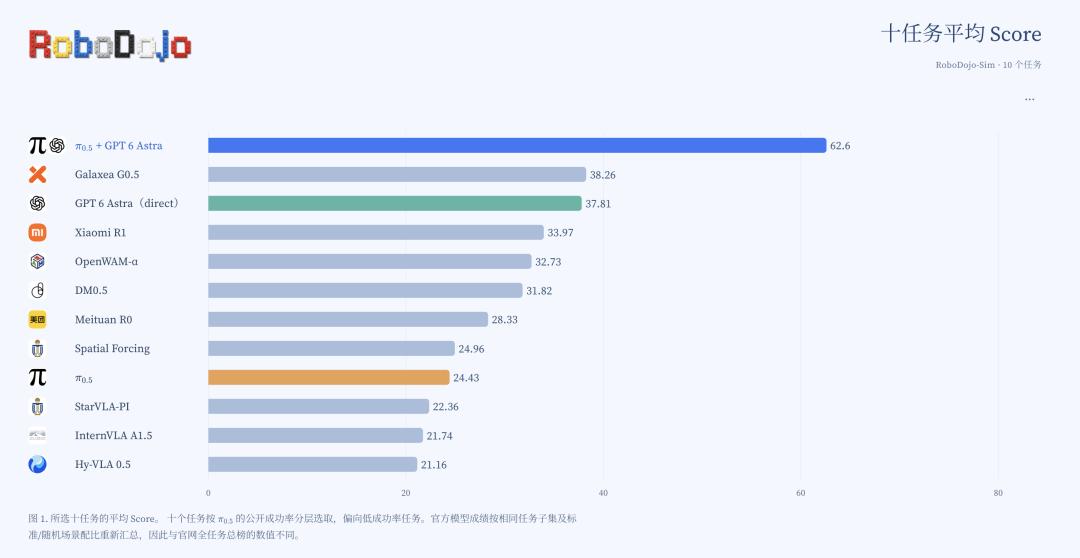
Recently, an anonymous simulation evaluation report published on GitHub dropped a bombshell in the embodied intelligence community. The architecture integrating GPT-6 Astra scored 62.6 points, while the second-place entry only got 38.26 points.
This 64% performance gap indicates that the difference is no longer a matter of fine-tuning optimization, but a dimensionality reduction strike at the architecture level.
The research did not use GPT-6 Astra to directly control the robotic arm. Instead, it adopted a smarter approach: GPT-6 Astra provides judgment and correction at the semantic level, forming a complementary architecture with π₀.₅'s physical space interaction and action prior.
How was this evaluation conducted?
The authors of this report are researchers from the Galaxy Universal team, and the first author is a PhD student supervised by Professor Wang He, founder and CTO of Galaxy Universal. The entire evaluation is a set of strictly aligned closed-loop control comparative experiments.
The research analyzed two closed-loop control architectures for simulated dual-arm operation:
Direct mode: Without running π0.5, GPT-6 Astra directly reads the three-way camera feeds and robot status, outputs the pose of the dual-arm end effectors and the opening/closing state of the grippers, and executes 1 to 5 control steps each time.
Mixed mode: At each decision moment, π0.5 first generates 50 candidate actions. GPT-6 Astra observes the same feeds, execution history, and the corresponding dual-arm trajectories of the candidate actions, then makes one of two choices: either follow the first 1 to 15 steps generated by π0.5, or generate 1 to 5 steps of end-effector pose correction by itself. After completing this segment, it observes the new frame and makes a new decision.
This architecture is actually very simple. The first author also mentioned in the report that this TopK idea of "candidate action selection" has been discussed many times in industry exchanges, but this is the first time it has been implemented to produce such a significant magnitude of performance difference.
The results show that the mixed mode achieved a 48% success rate and an average score of 62.60, which is even 64% higher than the average score of the second-place entry.
01 RoboDojo: Significantly Improved Success Rate After Integrating GPT-6 Astra
The first part is the RoboDojo experiment.
The team selected 10 types of complex robot operation tasks, including organizing desktops, classifying objects according to language instructions, sorting numbers, packing objects into boxes, building towers, drawing mahjong tiles, folding clothes, and putting bottles into buckets. Each task was tested 5 times, for a total of 50 tests.
Two schemes were set up in the experiment.
One is GPT-6 Astra Direct, where Astra directly generates robot actions based on vision, proprioceptive status and task goals; the other is π0.5+Astra, where the robot VLA model π0.5 provides actions, and Astra observes the environment and candidate actions, making corrections when necessary.
The difference between the results is obvious.
Astra Direct succeeded 13 times out of 50 tasks, with a success rate of 26%, and the average score of 48 tasks with complete native scores was 37.81.
After integrating π0.5, the number of successful tasks increased to 24, the success rate reached 48%, and the average score rose to 62.60. More notably, Astra only modified 14.4% of all executed control steps.
That is to say, most of the actions are still completed by π0.5, and Astra is mainly responsible for understanding tasks, judging the current status and deciding whether corrections are needed at key nodes.
This set of experiments first shows that the two types of models have obvious complementarity.
Astra is best at semantic understanding, visual recognition, spatial relationship judgment and task planning. In tasks such as "object classification", Astra Direct even scored 100 points; when facing grasping failures, missing objects or environmental changes, it can re-observe the scene and then decide the next action.
However, when it comes to tasks that require precise contact, stable grasping and continuous control, such as building towers and drawing mahjong tiles, the shortcomings of large models are quickly exposed.
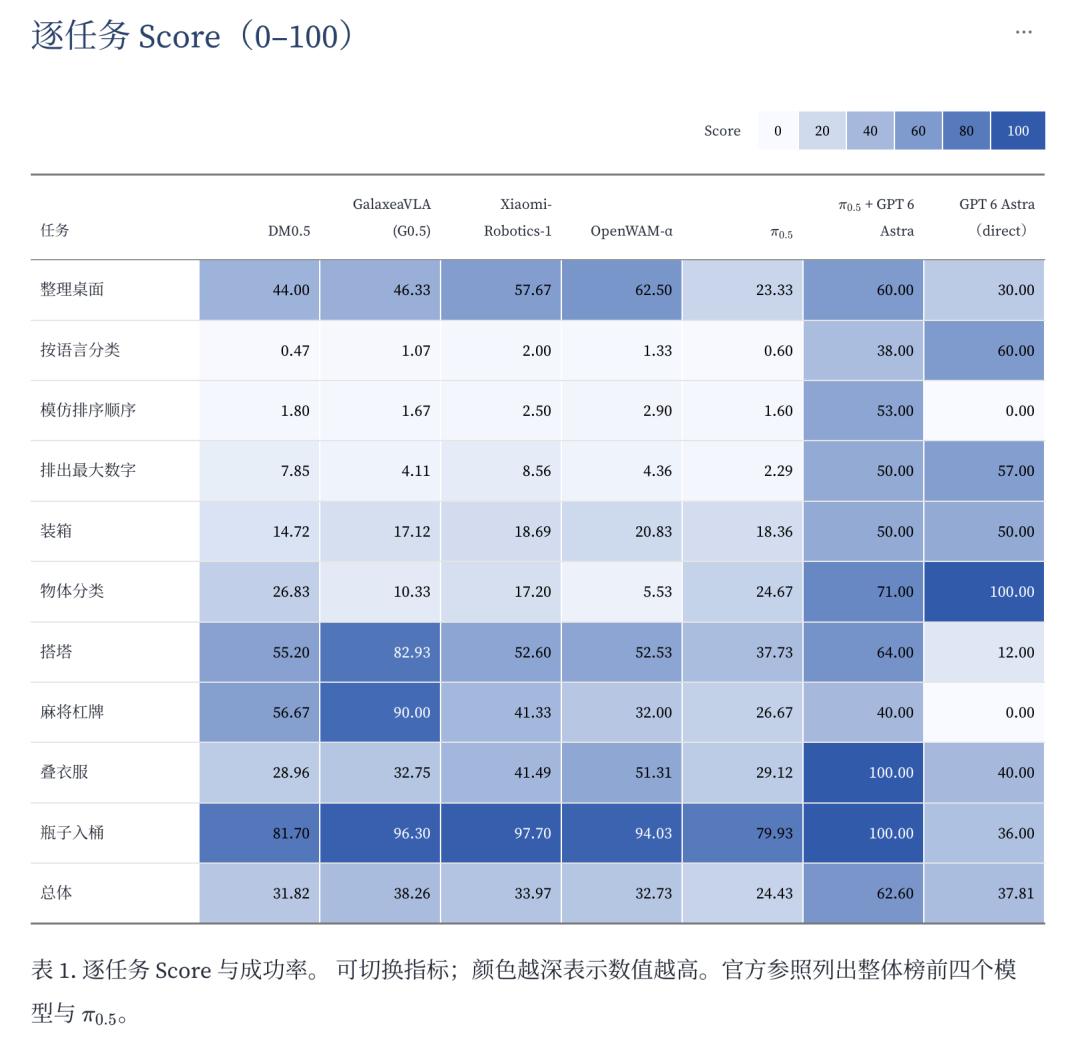
Astra Direct averaged only 12 points in the tower building task, and 0 points in the mahjong tile drawing task. The model can know where the wooden block should be placed, but it may not be able to stably control the landing point, friction and collision.
After adding π0.5, the score of tower building increased from 12 to 64, the score of mahjong tile drawing increased from 0 to 40, and tasks such as folding clothes and putting bottles into buckets were also significantly improved.
This is the most important message of the report: large models have been able to enter the robot policy layer, but the understanding of the physical world and the operation of the physical world are still two distinct capabilities.
02 RoboLab: Further Verification of Capabilities on Tasks with Semantic Understanding Requirements
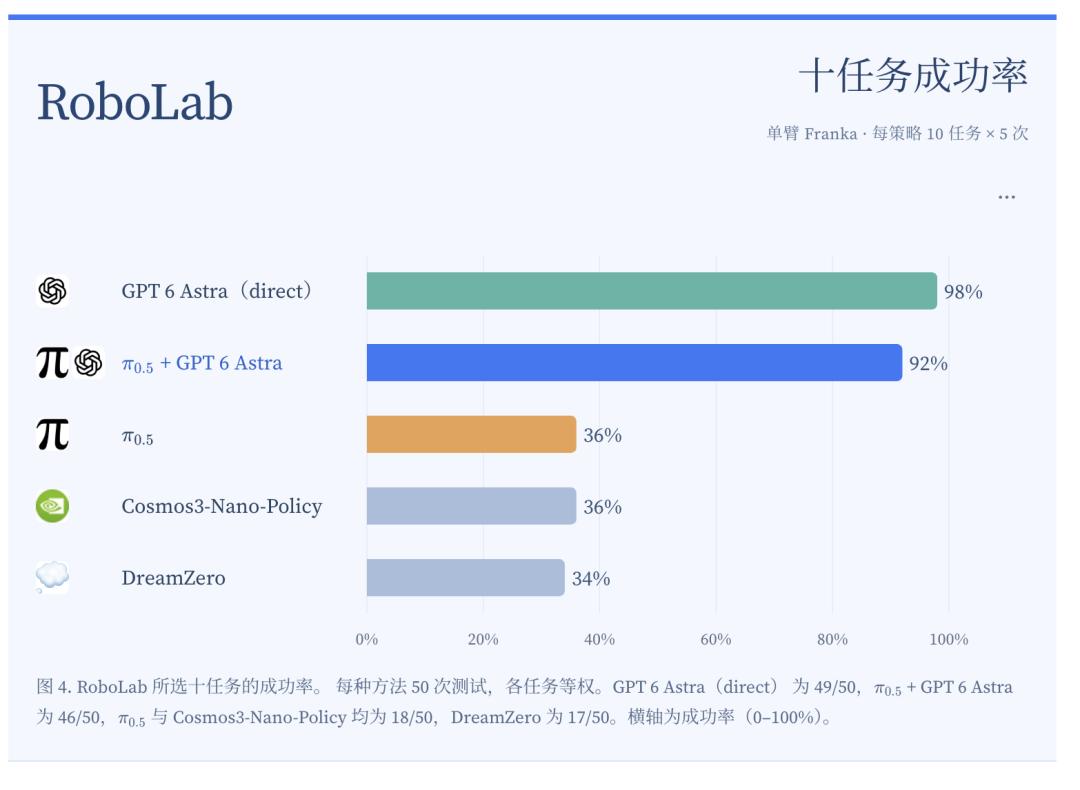
The RoboLab experiment further demonstrates Astra's advantages in another type of task, examining the understanding of general robot policies on vision, object relationships, task instructions and spatial structures. The team selected 10 types of tasks, each evaluated 5 times for a total of 50 tests, including putting blocks into containers, finding and moving pumpkins in clutter, stacking blocks in a specified order, adjusting the orientation of cups, and placing different objects in designated positions.
The results are very outstanding.
GPT-6 Astra Direct succeeded 49 times out of 50 experiments, with a success rate of 98%; Astra+π0.5 succeeded 46 times, with a success rate of 92%. For reference, π0.5 completed 18 times, Cosmos3-Nano-Policy completed 18 times, and DreamZero completed 17 times in the same set of statistics.
It is particularly worth noting that Astra was not additionally trained for these specific tasks. Based on the current frame, robot status and natural language task description, the model continuously judges how to operate next.
Judging from the results of each task, Astra achieved 100% success in 5 attempts for multiple tasks, including putting blocks into boxes, handling pumpkins in clutter, placing objects according to relationships, stacking in a specified order, and re-adjusting the orientation of cups. The only task that did not achieve full success was "putting the large raisin box into the container", which was completed 4 times out of 5.
The core capability demonstrated by this set of experiments is zero-shot generalization. The model can identify targets, understand spatial relationships, convert language requirements into actions, and continue to adjust strategies after environmental changes.
However, this figure needs to be understood in the context of the experimental caliber. The report clearly states that the RoboLab experiment only selected 10 tasks, with 5 final evaluation slots for each method per task, which is not a complete reproduction of the RoboLab leaderboard; the historical baselines and Astra did not strictly guarantee exactly the same initial state and control configuration, and some Astra experiments included authorized retries.
Therefore, 98% is more suitable for observing the upper limit of Astra's capabilities on these tasks, and cannot be simply regarded as a strictly same-condition leaderboard score.
03 GPT-6 Astra Excels at Understanding Tasks and Identifying "What Went Wrong"
Returning to the task-by-task results of RoboDojo, we can further see exactly where its strengths lie.
In the "object classification" task, Astra Direct scored 100 points and succeeded all 5 times; the average score of "classifying according to language instructions" reached 60, with a success rate of 40%; the score of "arranging the largest number" was 57.
Score Heatmap and Success Rate Heatmap
These tasks are highly dependent on language understanding, visual recognition, relational reasoning and goal planning, which are exactly the capabilities that large models are good at.
A large number of behaviors rarely demonstrated by traditional robot strategies also appeared in the experiment.
For example, after the model finds that a grasping posture is not ideal, it will actively change the approaching method; after the objects are roughly placed, it will re-observe the environment, find that the task is not actually completed, and continue to adjust; during the packing process, it can find that there are still missing objects behind the box; when the execution of the original plan is blocked, it will re-plan according to new visual feedback.
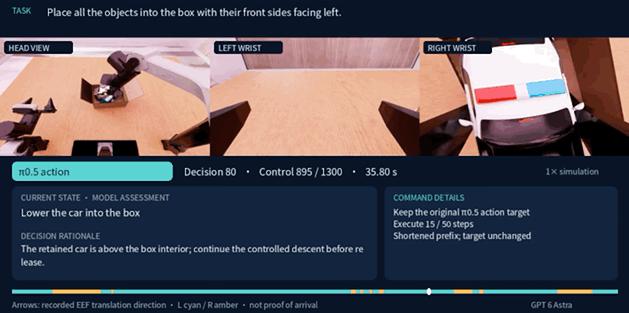
Figure: During the experiment, Astra will continue to judge the task status based on the new frame after execution, and adjust actions when necessary. For example, in the object classification task, the model finds that the current grasping requires local correction; in long-term tasks such as packing, the model will continuously check the remaining targets in the scene before deciding subsequent actions.
Excellent recovery performance also appeared in the number placement task: after the movement was blocked, the model re-understood the control feedback of the robotic arm, adjusted the action and continued to execute. It demonstrates GPT-6 Astra's local adaptability to control constraints, rather than just passively repeating failed commands.
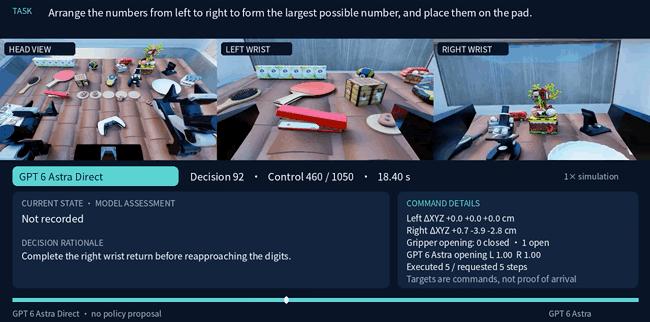
Figure: Number placement: excellent recovery after understanding control feedback
These phenomena indicate that Astra does not mechanically execute a pre-generated trajectory, but forms a closed loop of "observe - decide - execute - re-observe".
The model will even actively choose some strategies that may not be common in training data. For example, in the "putting bottles into buckets" task, Astra Direct once tried to sweep the bottles to the trash can instead of grasping them one by one. This solution eventually failed, but it shows that the model can find new solutions independently according to the goal.
04 The Real Bottleneck Still Lies in Physical Interaction
However, the research report also reveals Astra's weaknesses.
In the "tower building" task, Astra Direct averaged only 12 points with a success rate of 0; the score of "mahjong tile drawing" was 0; these tasks require precise contact, stable grasping, collision control and continuous judgment of the force state of objects. Compared with semantic and visual tasks, large models are obviously struggling here.
A typical problem is that understanding the goal does not mean being able to complete the action stably.
The model may know where the wooden block should be placed, but cannot ensure that the tower will not fall when it is put down; it knows that the object should enter the container, but it may fail due to collision between the gripper and the edge of the container. The current control adopts segmented execution, and the model usually needs to wait for an action segment to end before re-observing, so problems such as slipping and collision that occur during action execution are sometimes not discovered until the next round of feedback.
This is also where π0.5 generates value.
After adding π0.5, the score of "tower building" increased from 12 to 64, with a success rate of 60%; the score of "mahjong tile drawing" increased from 0 to 40; the score of "folding clothes" increased from 40 to 100; the score of "putting bottles into buckets" also increased from 36 to 100.
π0.5 provides motion prior formed by robot action data training, while Astra is responsible for identifying tasks, judging progress and correcting errors at a higher level. After the two are combined, some tasks that are difficult to complete by relying solely on Astra are significantly improved.
The research also analyzed some interesting but not necessarily robust or physically unachievable situations that appeared under the GPT-6 Astra mode. Due to the lack of mature action and object interaction prior provided by the embodied Policy, the model needs to solve the details in grasping, supporting, contacting, releasing and dual-arm coordination by itself, and some seemingly reasonable and interesting solutions are not stable in actual execution.
Zero-shot Behavior: Interesting Solutions, Not Necessarily Robust Actions
GPT-6 Astra (direct) will try to sweep the bottle into the bucket with the robotic arm, grasp the tower building board with one hand, or complete operations that are originally suitable for dual-arm cooperation with a single arm. These are different implementation methods for the same goal, not just simple task understanding errors.
The problem is: proposing a potentially effective operation and stably executing the operation are two different levels of capabilities. Without the support of mature action prior, the solution may ignore reliable grasping posture, sufficient support or appropriate release timing, making locally feasible actions difficult to convert into stable task completion. The value of embodied Policy is not only to provide an action answer, but also to provide an execution mode formed through interactive experience, so that the semantic-level solution is built on a more reliable operation basis.
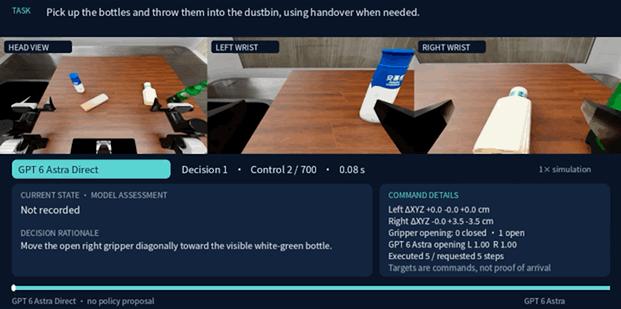
Figure: Zero-shot solution: trying to sweep the bottle into the bucket with the robotic arm
05 The Cost of Capability Improvement Remains Very High
The report also emphasizes that the current solution is still far from actual deployment.
The first is the reasoning cost. In the RoboDojo experiment, π0.5+Astra consumed a total of about 625 million Tokens, while Astra Direct exceeded 1.13 billion Tokens. Astra needs to repeatedly read visual and historical context and perform long reasoning, which is naturally contradictory