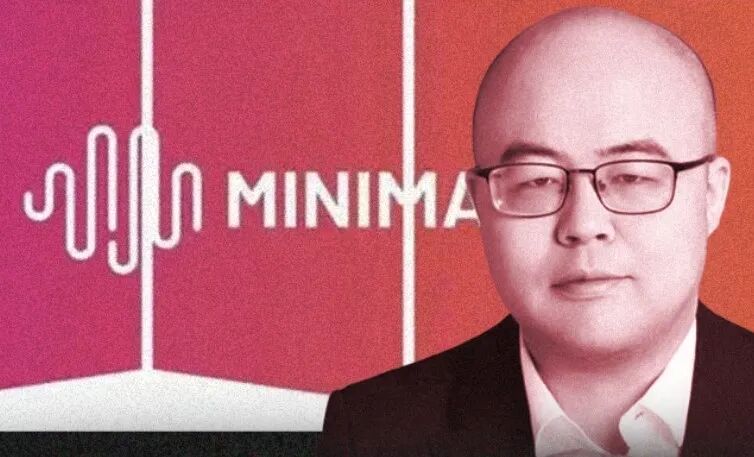
How does MiniMax achieve AGI? The method Yan Junjie adopts is to outflank from the rear.
"That last 5% gap can be far more difficult to close than completing the preceding 95%."
In a recently released episode of the British podcast *Invest in Progress*, Yan Junjie, founder of MiniMax, talked about the difficulties for Chinese large models to catch up with their US peers.
His conversation partner was Lawrence Burns, Investment Manager of Scottish Mortgage. In December 2025, Burns traveled to China to visit Yan Junjie and heard an impressive judgment: China's best models had already reached about 95% of the performance of the top US models, but the cost was only one-tenth. Later, Scottish Mortgage participated in MiniMax's Hong Kong IPO.
This time, Burns wanted to know what changes had taken place in these two gaps.
Yan Junjie did not give a new percentage figure. He said that the last 5% still requires time to catch up, and both Chinese and US models are in the early stage on the road to AGI. What he cares more about is the speed of progress.
Cost is a topic that has been repeatedly involved in this conversation. Yan Junjie believes that reducing inference cost can not only make the model accessible to more people, but also allow MiniMax to conduct more post-training and continuously improve model capabilities. He explained this with the company's name: "Mini" means to bring down the inference cost; "Max" means to push the upper limit of intelligence higher.
Following this path, he also made a commitment: "We plan to keep open-sourcing until AGI is achieved."
Catching up with the last 5%
Talking about the gap between Chinese models and US models, Yan Junjie first mentioned computing power.
"For us, especially for a Chinese AI company, computing power has always been a constraint."
From the very beginning of its establishment, MiniMax has to consider how to make limited computing power undertake more work. The design of model architecture, the construction of infrastructure, and the optimization of the inference process all need to focus on efficiency. Yan Junjie said that one of the company's design principles is that the model should perform well no matter what chip is used.
In his view, several leading Chinese model companies are finding ways to improve efficiency, but they have made different choices: some adjust the Transformer architecture, some improve the post-training infrastructure, and others focus on investing in different modalities. This preserves differences between Chinese models.
Burns asked more directly in the interview: Have the cutting-edge labs in the US been "spoiled" by abundant computing power? They have the conditions to continuously push the boundaries of technology, but have not been forced to put efficiency at the core from the very first day.
Yan Junjie focused the discussion on the situation of Chinese companies. The more constrained the hardware is, the more important the improvement of algorithms, architecture and infrastructure becomes.
"Constraints have made us better engineers and researchers."
Yan Junjie also wants to use the saved inference cost for post-training.
Reinforcement learning requires the model to try repeatedly and get feedback; generating synthetic training data also requires calling the model. These processes all consume inference computing power. If the cost of one inference is reduced, the same resources can support more training.
He judged that the proportion of post-training in model iteration will become higher and higher. By improving inference efficiency, MiniMax also aims to expand the scale of post-training. He even proposed that at some point in the future, MiniMax may have the largest post-training system, and thus reach the forefront of intelligence.
This is still a goal. For the current gap between China and the US, his judgment is relatively cautious: in the past three years, the progress speed of models on both sides has been roughly equivalent, but the remaining 5% may be more difficult to complete than the previous 95%.
Efficiency also extends to the organizational mode of the company. According to Yan Junjie's statement in the interview, MiniMax has only 500 people, and R&D follows two principles: make the architecture and infrastructure as simple as possible; insist on building infrastructure by ourselves, even if this will slow down product release in the short term.
The former is to allow the limited team to concentrate on their work, while the latter prepares for the subsequent expansion of model and training scale. He believes that the company's capital efficiency and organizational efficiency are gradually formed under these choices and external constraints.
However, whether low cost can bring profits is still a concern of Burns as an investor. MiniMax is still making losses, and the improvement of model capabilities, user growth and revenue increase ultimately need to support continuous investment.
Yan Junjie's idea is to reduce inference costs through technological innovation, improve model capabilities while maintaining price advantages, and make revenue grow faster than cost.
As of August, MiniMax's annualized revenue run rate has exceeded 800 million US dollars, with enterprise business contributing more than 80%. The annualized revenue run rate here refers to multiplying the August revenue by 12, which does not mean that the company has achieved full-year revenue of 800 million US dollars.
For reference, MiniMax disclosed that its revenue in the first half of 2026 was 116.6 million US dollars, a year-on-year increase of 283.1%; its revenue from open platforms and other AI enterprise services was 73.9 million US dollars, accounting for 63.4% of the total revenue. The latter proportion corresponds to the realized revenue structure in the first half of the year, which is different from the annualized caliber of August mentioned in the interview.
In the same period, the company's adjusted net loss was 293 million US dollars. In the interview, Yan Junjie did not give a timetable for achieving profitability.
Grandpa wanted to write a memoir
In the process of Yan Junjie's decision to develop general artificial intelligence, a family matter touched him a lot.
His grandfather wanted to write a memoir to preserve his decades of life experiences. But the old man could not type, and it was difficult for him to organize his past events into words on his own. Yan Junjie thought that AI should be able to help with this, but the technology at that time was not capable of doing so.
This incident made him pay more attention to the meaning of "general". According to his memory, computer vision and speech recognition at that time mainly served enterprises, and there was still a gap from the daily needs of ordinary consumers. An old man wanting to record his whole life is one of the unmet needs.
Yan Junjie was exposed to mathematics and computer science very early. He grew up in Henan, his father was a mathematics teacher, and there were many books at home. When he was in middle school, he had already started to teach himself college-level mathematics and computer science. What attracted him was to combine the two and solve real-world problems through programming.
In 2014, he interned at Baidu Deep Learning Institute, and Yu Kai was his mentor. At that time, he had already published dozens of papers on computer vision, and the breakthrough of AlexNet in image classification still shocked him greatly. He wanted to find a company with a large number of GPUs to verify how far deep learning could go.
According to Yan Junjie's recollection, during the internship, he could call one-third of Baidu's GPUs at peak time. He used these resources to study image classification and object detection, and partnered with another intern to participate in the ImageNet Challenge of that year, winning the third place.
When he founded MiniMax, he was convinced that AGI was worth pursuing, but he still did not know when it would arrive.
In the first year, the team built infrastructure, trained the first-generation versions of language, image and audio generation models, and also developed an application to test the model performance. This application is Glow, where users can chat with virtual partners. It quickly accumulated millions of users, exceeding the team's initial experimental expectations.
Then ChatGPT was released. Yan Junjie said that this changed his judgment on the technology development timeline: infrastructure, data and model scale all need to expand at a larger magnitude and faster speed than originally expected.
MiniMax also chose to invest in text, image, video, music and speech at the same time. For a company with limited resources, this means that R&D forces have to be dispersed in multiple directions.
Yan Junjie admitted that he did not know what the final form of the model would be when starting the business, so he started all directions first, and tried to integrate them when the technology was mature enough. He believes that multi-modality can bring richer data, and it is also an inevitable path for the model to continue to scale up.
"If we only focused on one modality at the beginning, our early progress might have been faster," he said.
In the interview, he classified MiniMax's models into two major series: the M series is a language model, focusing on programming and agents; the H series mainly focuses on video generation, covering video, image and audio. The next plan is to continue to improve the capabilities of the two types of models, and then integrate them into the same system.
In terms of agents, he hopes that AI can set goals by itself in a long task cycle and verify the execution results. He regards this autonomy as the direction that agents need to break through next.
At the time of the interview recording, Yan Junjie was focusing most of his energy on the next-generation model M3 Pro. He said that the model has not been completed yet, but he expects it to bring an important breakthrough.
For AGI, he also has a clear judgment standard: AI can develop new theories, and major new scientific breakthroughs will mainly rely on AI.
Open-sourcing until AGI is achieved
MiniMax charges through APIs while opening model weights, allowing developers to deploy and modify them on their own.
Yan Junjie believes that open source can promote commercialization and allow more developers to participate in model improvement. The exploration that MiniMax cannot complete by itself can be continued by the community.
He took H3 as an example. According to his introduction in the interview, this model was downloaded about 25 million times in the previous month; in the first two weeks after it was opened, about 300 open models had been derived based on it.
One of the examples is H3 Max, which is post-trained by the US company fal.ai based on H3. According to Yan Junjie's introduction, it can generate 5 seconds of video in 3 seconds, and the generation speed is faster than the playback speed of the video.
Such speed enables more interactive uses of video. Yan Junjie mentioned that some developers have created 24-hour AI live broadcasts, which generate pictures in real time according to the content the audience wants to watch. The same capability can also be used in scenarios such as games and education.
These attempts will in turn bring feedback to MiniMax, helping it discover what the model can do and what it still lacks. Yan Junjie regards this as the most direct help of open source for R&D.
Another benefit comes from the deployment method. Enterprise and government customers can run open-weight models on their own devices, have more control over data and privacy, and can continue to train and develop around their own needs.
"We plan to keep open-sourcing until AGI is achieved."
Talking about the competition from companies such as ByteDance and Alibaba, Yan Junjie believes that MiniMax's advantage lies in its focused goals. Large technology companies need to take into account multiple business lines, while MiniMax concentrates its R&D on high-efficiency multi-modal AGI. The improvements and new uses provided by community developers are also a way for it to leverage external forces.
He hopes to eventually integrate the best language model and video model into one system, so that the model can undertake more work. This vision also continues MiniMax's early choice of investing in multiple modalities at the same time.
In terms of the development path of AI in China and the US, Yan Junjie predicts that the differences in computing power, capital and chip access conditions will continue to affect the technologies and products on both sides. He summed up his observation in one sentence: "The US ecosystem builds a closed system supported by huge capital, while the Chinese ecosystem builds a collaborative system supported by efficiency." He believes that the two ecosystems will not necessarily go the same way.
At the end of the interview, Burns asked him to describe: If MiniMax achieves its goals, what will the world look like?
Yan Junjie talked about the ownership of AGI. He believes that this technology is too important to belong to only one company, country or organization. People who use the model, developers and researchers have all participated in the growth of the model, and should also share the capabilities it brings.
This is also the reason why he insists on using the slogan "Intelligence with everyone". Developing intelligence together with everyone means that after the model is opened, more people can continue to work on the basis of it.
He is also curious that when the world has more intelligence, will human understanding of the world and even the universe change accordingly?
"I think it will. It is this possibility that drives me forward."
This article is from the WeChat official account "Letter AI", author: Miao Zheng, published with authorization from 36Kr.