AI Companies: Raking in Sky-High Priced Data?
Data left by a bankrupt airline was purchased by Google for an offer of 10 million US dollars.
This transaction involves long-accumulated internal records of the US low-cost airline Spirit Airlines, including approximately 100 million emails, 500 million Microsoft Teams messages, and a large number of spreadsheets, calendars and other business materials. Google hopes to use these data to improve its AI models.
Why can the years of accumulated work records of an airline that has ceased operations still be sold for tens of millions of dollars?
Meanwhile, another AI data company micro1 announced that it plans to invest 1 billion US dollars in the next 12 months to purchase or obtain operation data licenses from real enterprises, so as to build a reinforcement learning environment for AI to learn to complete complex business tasks.
In the past few years, AI companies have spent huge sums of money purchasing GPUs and building data centers, yet there has long been no clear price for the data required for model training. At present, more and more quotations are emerging. A highly difficult math evaluation question may be worth 5,000 US dollars, the internal data of an enterprise can receive an offer of 10 million US dollars, and a leading model company may spend hundreds of millions of US dollars on services purchased from a single data supplier in a year.
What kind of data does AI actually need? Why can these data be sold at such drastically different prices? And how should a company decide how much money to spend on data?
Who are AI Companies Buying Data From?
In the past, the Internet was an important channel for large models to obtain data.
News reports, books, encyclopedias, forums, open source codes and professional websites constituted the important corpora for early model training. An industry insider revealed to Tencent Technology that in the early stage of industry development, in order to obtain high-quality data, some people even bought a large number of old books to "tear apart books for scanning".
With the development of the industry, copyright issues have attracted more and more attention. Leading model companies will obtain a large amount of content from the public network, and also purchase licenses from publishers and professional databases, before cleaning, deduplicating and filtering the data.
This market has always existed. OpenAI has reached a multi-year content cooperation with News Corp. According to the Wall Street Journal's report at that time, the value of this agreement may exceed 250 million US dollars within five years. OpenAI can use the current and historical content of media such as the Wall Street Journal and the New York Post, not only for product improvement, but also for displaying licensed content in ChatGPT.
However, with the improvement of model capabilities, the targets of data procurement have begun to change.
At present, the external data sources of model companies can be roughly divided into three categories.
The first category is companies that specialize in producing AI training data.
Companies such as Scale AI, Surge AI, Mercor, and micro1 all belong to this market. They help model companies organize labeling personnel and professional talents, process raw data into materials that can be used for training, and produce high-quality answers, evaluation questions and complex tasks required by models.
This business has developed to a quite large scale.
In July 2026, financial documents obtained by *The Information* showed that Mercor achieved a total revenue of 614 million US dollars in the first half of the year, of which about 91% came from foundation model companies, including OpenAI, Anthropic, Google DeepMind, etc.
The revenue of these data companies has reached the order of hundreds of millions of US dollars. They are also gradually shifting from providing large-scale labeling labor to organizing professionals such as mathematicians, programmers and doctors to produce high-quality data, as the demand for model training changes.
The second category is people with professional knowledge.
In February 2026, foreign media reported that some mathematicians were invited to provide highly difficult evaluation questions for AI, with a remuneration of about 5,000 US dollars per question.
Such questions are not ordinary Olympiad math problems. They need to be sufficient to test the capabilities of cutting-edge models, and also have reliable answers and verification methods. For AI that is increasingly good at mathematical reasoning, coming up with a problem that it cannot easily solve itself also requires high professional competence.
In addition, model companies also need engineers to design complex programming tasks, doctors to evaluate diagnostic reasoning, and legal experts to judge whether professional answers are reliable.
Compared with ordinary text labeling, the production cost of such data is higher, and the requirements for personnel are more stringent.
The third category, which has seen obvious new trends recently, is industry companies that hold real business data.
Spirit Airlines is a typical case. Before bankruptcy, this airline was not an enterprise providing data for AI. Its emails, meeting records, spreadsheets and business materials are just records naturally formed after years of business operations.
But for model companies that want to train AI to complete real work, these materials may provide another kind of value. For example, how does an enterprise deal with delayed delivery from suppliers? How does a customer complaint circulate among different departments? How do employees adjust their work plans according to new situations? These processes may be scattered in emails, contracts, meeting records and business systems.
There are a large number of articles on the Internet introducing enterprise management, supply chain and customer service, but it is difficult to fully restore the problems that a company has actually dealt with.
micro1's latest procurement plan is also aimed at this type of data.
On October 9, micro1 announced the launch of the Company Data Partnerships program, to purchase or obtain operation data licenses from enterprises, and convert them into reinforcement learning environments. Models can learn how to process incomplete information, conflicting objectives, and various unexpected situations in real business in such environments.
This demand is significantly different from the large-scale web data procurement in the past. As a result, the work records of enterprises have new potential buyers.
However, there are also obstacles for this type of data. The fact that enterprises own internal records does not mean they can freely sell information involving employees, customers and partners; raw records are not equal to training data that can be directly used. Buyers also need to complete authorization review, privacy processing, task extraction and result verification.
The scope where AI companies look for data is expanding, from Internet content and professional data companies to industry enterprises that truly hold business records.
How Much Does It Cost to Train a Top-tier AI in Terms of Data?
How much budget model companies actually invest in data is still a very opaque issue.
AI companies often disclose the computing power and infrastructure investment for training, but rarely publish the full data ledger. Even for leading companies such as OpenAI and Anthropic, the currently publicly available financial materials do not list the expenditures of pre-training corpora, expert post-training, reinforcement learning tasks and evaluation data item by item.
This is first of all related to the composition of data costs.
The data investment of a model company includes not only the purchase of original corpora and copyright licenses, but also data cleaning, deduplication, quality review and privacy processing. In the post-training stage, it is also necessary to purchase demonstration answers, preference judgments and complex tasks from experts; when training Agents, it may also be necessary to develop executable environments and automatic verification tools.
In addition, model companies are also producing data themselves. Internal researchers, labeling teams, synthetic data generation systems and evaluation infrastructure may all generate related costs.
From the perspective of listed large model companies, in the first half of 2026, Zhipu's R&D expenses reached 2.131 billion RMB, a year-on-year increase of 33.6%; MiniMax's R&D expenses were about 297 million US dollars, a year-on-year increase of 138.8%. MiniMax clearly stated that the growth mainly came from the increase in training-related cloud service costs brought by model iteration. However, it is difficult to find a separate corresponding figure for data procurement in the financial reports.
In the prospectus released by MiniMax at the end of 2025, it was disclosed that it plans to invest about 64.9 million Hong Kong dollars each year from 2026 to 2030 for data procurement, labeling and compliance of text, vision, audio and multimodal models, with a total of about 325 million Hong Kong dollars in five years.
Zhipu's prospectus shows that in the first half of 2025, R&D technology service and consulting expenses were about 52.21 million RMB, involving data cleaning, model evaluation and other R&D outsourcing work. Since multiple projects are disclosed in combination, it is impossible to confirm how much of it is directly used for data-related services, nor can it be judged whether it includes original data procurement.
The computing power and overall R&D expenditure of model companies are becoming more and more transparent, but there is still a lack of a unified financial standard for how much money is spent on purchasing original corpora, expert-produced training data, reinforcement learning tasks and evaluation materials. External procurement, internal data production and related computing costs are scattered in different accounts, making it difficult to directly compare the data investment of different model companies.
However, individual external procurements of overseas model companies have reached very high amounts. Google once planned to pay Scale AI about 200 million US dollars a year, and Mercor's hundreds of millions of US dollars in revenue in the first half of 2026 also shows that leading model companies are continuously purchasing external data production services.
According to another insider, the data investment cost of GPT-6 Astra is as high as several billion US dollars, but this is only industry rumor.
What is more worthy of research is how model companies actually determine their data budgets.
In the traditional understanding, if the model needs more data, just continue to expand the procurement scale. But this approach may cause waste: the same type of data has been accumulated a lot, and continuing to add it may not bring significant improvement; what really limits the model's capabilities may be another type of scarce data.
*Rethinking Data Mixture for Large Language Models*, published in EACL Findings in March 2026, systematically sorts out the data proportion optimization methods in large model training.
It discusses "which data should the limited training resources be used for".
For example, models of the same generation need to improve their abilities in mathematics, programming, language understanding and tool use at the same time, but adding data from different fields has different impacts on the final performance. The study summarizes how to adjust the proportion of various types of data under a fixed computing budget to improve model performance.
In the actual commercial procurement scenario, model companies also need to answer the third question: should these data be purchased or produced by themselves?
Assuming a model company wants to improve the success rate of complex programming tasks. If ordinary code can no longer significantly improve the model's performance, continuing to expand procurement may be meaningless; if the quality of synthetic tasks is high enough, the necessity of external procurement may also decrease.
Conversely, when certain data can only be provided by professionals or real enterprises, and can indeed improve model performance, it may be worth purchasing even if the unit price of procurement is very high.
Therefore, the data budget is not just a fixed proportion of R&D costs. It is related to what capabilities the next-generation model plans to improve, what data the existing model lacks, and how much additional revenue different types of data can bring.
This change also directly affects the price of the AI data market.
What Kind of Data Is Getting More and More Expensive?
The price of AI data is showing obvious differentiation.
On Mercor's recruitment page, the average contract rate for ordinary professionals is about 107 US dollars per hour, but the quotation for some oncology experts reaches 350 to 450 US dollars, and that for machine learning experts is 150 to 200 US dollars. In contrast, the cost of basic tasks such as simple image classification and text labeling can be as low as a few cents per item.
This price difference shows that at present, model companies are willing to pay higher fees for professional judgment in specific fields.
In addition to the 5,000 US dollars remuneration per math question mentioned at the beginning of the article, the quotations in the medical field can also well illustrate this point. The radiologists currently publicly recruited by Mercor have a contract rate of 200 to 400 US dollars per hour, and their tasks include medical image interpretation, writing reference diagnosis reports and evaluating model performance; the hourly salary of some oncology expert positions reaches 450 US dollars. These are expert remunerations, not the final unit price of data paid by model companies, but they already reflect the production cost of complex professional data.
Expert time is expensive and limited, so data companies need to obtain more effective training signals from each hour of labor. Experts may be responsible for creating tasks, defining qualified delivery standards, or handling situations where the model's opinions are inconsistent with the automatic scorer's. Another task of data companies is to measure whether the dataset can actually improve the model's performance.
Another growing demand is for reinforcement learning tasks and executable environments. Model companies need Agents to complete multi-step operations in the environment, and judge whether the execution is successful through real results or verification procedures.
The cost of such data comes not only from writing tasks, but also from environment development, rule setting, automatic verification and repeated testing. micro1's announced 1 billion US dollar enterprise data procurement plan is to extract such training materials from real operation records.
There is also a noteworthy price contrast in the robotics field. On October 16, foreign media reported that data collection projects such as Human Archive are recruiting people in more than 30 countries to wear devices to record their daily labor, paying 1 to 30 US dollars per hour.
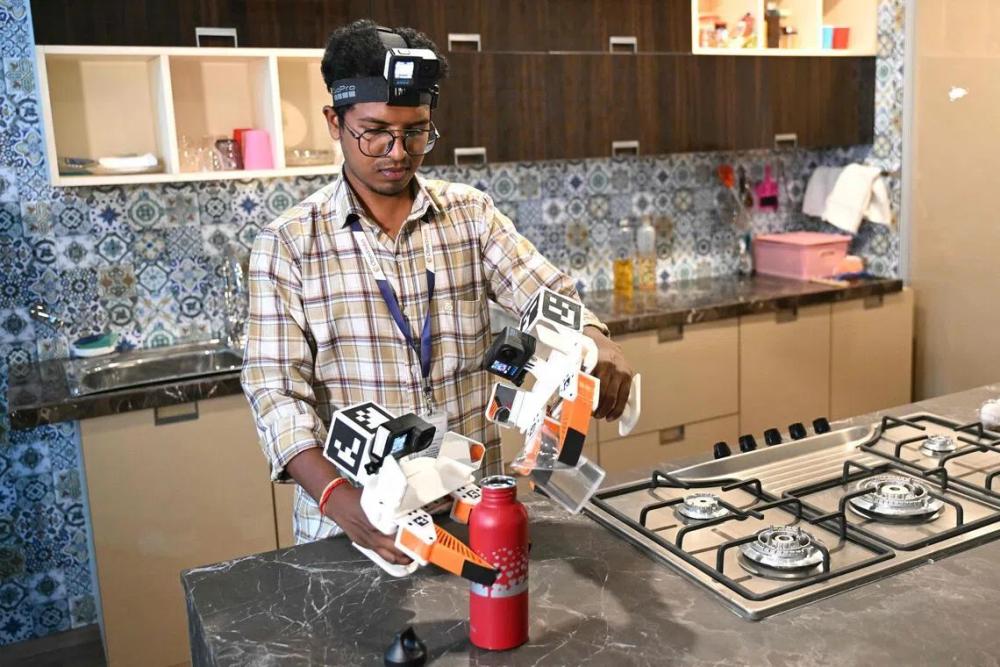
The report also pointed out that the demand for related real-world data has increased by about ten times within one year. At the same time, foreign media reported on October 15 that domestic robotics enterprise DexForce is using virtual simulation data to reduce training costs. The simultaneous development of the two routes means that the demand for real operation data is expanding, but simulation technology may also gradually push down the collection cost of part of the data.
A more profound change is that models themselves are becoming data producers. For mathematical and programming tasks whose answers can be automatically verified, models can generate questions in batches, try to solve them, and then use code executors or other verification tools to filter the results. This will reduce the demand for some manually produced tasks, and at the same time push the procurement budget to materials that are more difficult to generate, lack reliable verifiers, or require human professional experience.
Of course, there is also a question among them: can the next-generation model generate the data that currently requires expensive experts to produce at a lower cost by itself? If yes, the current high price may not be maintained for a long time.
What ultimately determines the price of data is whether it can provide verifiable capability increment beyond existing models and data sources, and how much cost needs to be paid to produce data of the same quality.
A long time ago, there was a widely circulated saying of "data hitting the wall": high-quality Internet data is no longer sufficient, so AI has encountered a data bottleneck that hinders the development of model capabilities.
Looking back today, "data" has begun to develop into a mature industrial chain. As long as human activities exist, this industrial chain, like an umbilical cord linking human beings and artificial intelligence, will thrive and grow endlessly.
This article is from the WeChat official account "Tencent Technology", author: Xiao Jing, editor: Xu Qingyang, published by 36Kr with