Is Claude going to be able to "read minds"? The mysterious new model of Anthropic has been revealed.
When you only ask AI to fix one bug, it may follow the clues to dig out a whole category of underlying problems behind it, and even take the initiative to ask you: do you want to solve all of them together?
Such AI may be arriving really soon.
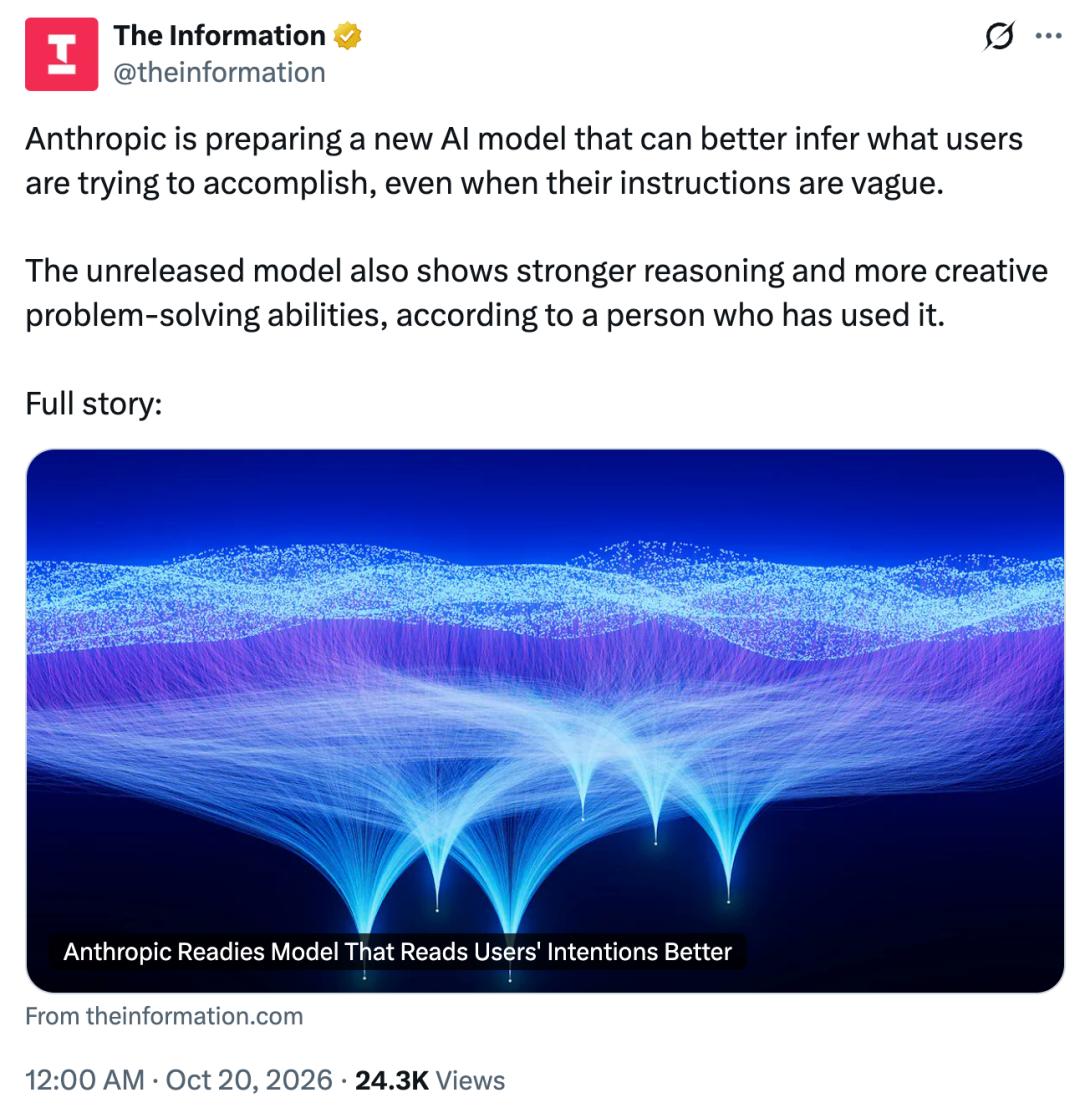
According to the latest scoop from The Information, Anthropic is preparing to launch a new model, whose reasoning ability and intuitive judgment are reportedly superior to all currently commercially available Anthropic models.
Some speculate that it could be "Claude Fable 5.5" or "Opus 5.6".
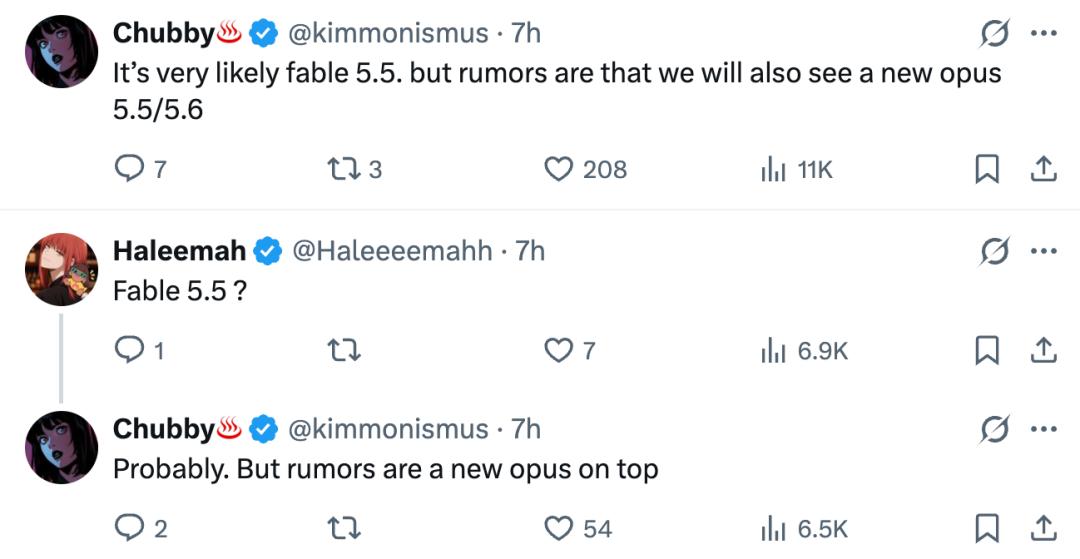
What draws more attention is that this new model seems to be particularly good at understanding users' unstated intentions. Even if users only provide limited information without clarifying the final goal, the new model can still infer what users actually want to achieve and propose more in-depth solutions.
The above news comes from a person who has already tested the model. At present, Anthropic has not officially announced this model, and its specific name, release date and evaluation results remain unknown.
Meanwhile, The Information also disclosed two other pieces of news: Google is developing a new model codenamed Gemini 4 Carbon, and OpenAI also plans to launch a new product that may belong to the Terra series in the coming weeks. The large model market, which has just gone through a round of intensive updates, is soon to embrace a new round of competition.
Anthropic's New Model
Starts to Proactively Understand User Intent
According to The Information's report, one tester believes that Anthropic's upcoming new model has surpassed the company's current commercial models in reasoning and intuitive judgment. One prominent feature is that it can infer deeper goals from users' simple instructions.
The report cites a programming scenario.
Assume the user asks the model to fix a certain bug, the new model may further identify a whole category of underlying problems that cause this bug during the process of inspecting the code. After discovering the problems, it may also take the initiative to ask the user whether similar problems need to be fixed together.
It should be noted that this is a hypothetical scenario used by the tester to explain the model's capabilities, and the report does not disclose the corresponding actual test results. But this example is really interesting. At present, when using AI programming tools, developers often need to repeatedly supplement instructions. For example, first ask the model to fix an error report, then ask it to check whether other files have similar problems, and finally arrange regression tests.
If the model can proactively discover the correlation between problems, developers can reduce these back-and-forth communications. Especially in large codebases, the same underlying problem may recur in different modules. If the model only fixes the immediate error, similar failures may still happen again. Of course, discovering similar problems is only the first step. It also needs to accurately judge the scope of impact to avoid modifying normally running code. It is also worth noting that the model mentioned in the report will first ask for the user's opinion.
Another example comes from stock investment.
According to the tester, if the user asks how to invest in stocks, traditional models may give common indicators such as price-to-earnings ratio and some relatively general suggestions. The new model may jump out of conventional thinking, independently propose more creative algorithms, and try to predict the future performance of stocks. What is emphasized here is the model's ability to propose new ideas. As for whether these algorithms are really effective and can achieve better prediction results in actual investment, there is no public evidence at present.
Both examples point to the same feature: when facing the problem raised by the user, the new model may further analyze the goal behind the problem and try to find a more complete solution.
This capability is particularly important for AI programming and Agent tasks. In complex tasks, users often only describe the results they want to achieve, and do not list all execution steps in advance. The model needs to check the environment by itself, locate problems, and adjust subsequent actions according to the information discovered midway. If it can grasp the user's intention more accurately, the model can reduce repeated trial and error during the execution process.
However, at present, these capability descriptions mainly come from one tester. There is no public evaluation that can verify the performance of the new model in real projects and how much it has improved compared with existing Claude models. Even which model family it will finally belong to has no answer yet.
Google and OpenAI Also Have New Models in the Pipeline
While Anthropic is preparing to update its model, Google and OpenAI are not idle.
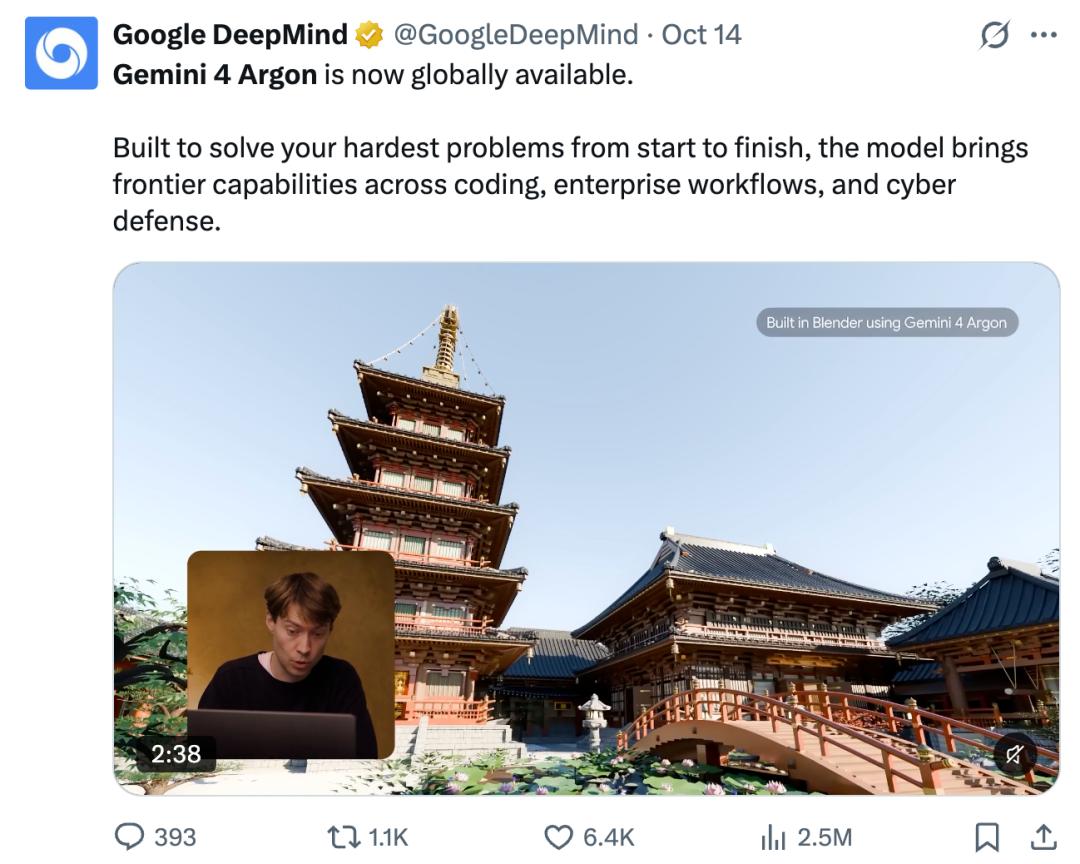
On October 14, Google officially expanded the access of its flagship model Gemini 4 Argon, making it available to developers, enterprises and consumers worldwide. Previously, this model was first opened to some cybersecurity defenders. Argon is mainly oriented to complex tasks such as programming, finance, law, cybersecurity and scientific research. In the evaluations announced by Google, Argon has achieved leading results in multiple professional tasks.
According to The Information citing sources familiar with the matter, Google is already developing its next model, internally codenamed Gemini 4 Carbon. Carbon is reportedly expected to go a step further than Argon, but there is no public performance data at present.
The report also mentions one advantage of Gemini. Argon does not seem to have fully surpassed the top models of Anthropic and OpenAI in overall capabilities. However, some developers told the media that Gemini still performs well in tasks requiring visual understanding, such as analyzing video content or checking whether website functions operate normally.
The Information also speculates that Google has a large amount of YouTube video data, which may help with this capability. However, the report does not prove that there is a direct causal relationship between the two.
On the other side, OpenAI is also preparing to continue updating its product line. According to people familiar with the matter, OpenAI is expected to launch a new model in the coming weeks, most likely a new version of the Terra series. Terra sits between Sol and Luna, belonging to OpenAI's mid-tier product line. This new model is expected to have further capability improvements, while its price will be lower than the previously released GPT-6.1 Sol.
From the perspective of product positioning, OpenAI is still trying to cover more development needs through models with different performances and different prices. For applications that require a large number of model calls, reasoning costs often directly affect whether the product can operate at scale. Even if a model does not reach flagship-level performance, as long as it can complete enough tasks at a lower price, it is equally attractive.
What is more noteworthy is that OpenAI has another heavyweight model under preparation. The Information previously reported that this unreleased model involves technologies related to recurrent Transformer, and the team is still dealing with safety and security risks to avoid major problems after the model is released.
Judging from these news, several leading manufacturers are preparing for the next round of model updates. There are still many uncertainties regarding the specific release time, performance improvement range and final product positioning.
When AI Starts to "Think One Step Further"
Back to Anthropic, what is most worth observing in this scoop is the possible change in the way the model processes tasks.
Take programming as an example. When a developer asks AI to fix a bug, it seems to be a very clear task on the surface. But the real goal is usually to get the program back to normal operation and prevent similar errors from recurring.
In the past, developers often needed to add prompts to tell the model these requirements step by step. If Anthropic's new model can really proactively discover similar problems and ask whether to expand the scope of repair as described by the tester, then it can take on more troubleshooting work that originally needed to be done by developers personally.
The significance of this change may be even greater in more complex Agent scenarios. When a user asks AI to analyze the reason for the decline of a certain business indicator, the model may need to check the data first, and then gradually troubleshoot related factors. If it can proactively discover the connection between anomalies, it can continue to analyze along new clues and reduce the number of repeated prompts from users.
But there is also a practical problem here: the goal inferred by the model may not necessarily be what the user really wants. Developers may only want to urgently fix online failures and do not intend to modify the entire project immediately. Even if the model identifies more widespread problems, it still needs to confirm whether the user is willing to take the risks brought by additional modifications. Similarly, in scenarios such as investment and finance, even if the model proposes a more complex analysis plan, it needs the user to confirm their goals, constraints and risk preferences.
The ability to accurately infer user intent and when to proactively ask for user opinions will directly affect the actual value of such capabilities.
There is currently no evidence that Anthropic's new model has solved these problems. But judging from the examples provided by the tester, it at least shows a direction worth looking forward to: after receiving a task, try to further judge whether the immediate problem is related to a deeper goal.
For developers who are increasingly relying on AI Agents to complete complex work, this may bring quite intuitive experience changes. As for how far Anthropic can take this capability, we will have to wait for the official release of the new model to see its performance in real tasks.
References:
https://www.theinformation.com/newsletters/ai-agenda/anthropic-readies-model-reads-users-intentions-better
https://x.com/kimmonismus/status/2112185581597860349
https://explainx.ai/blog/anthropic-new-model-gemini-4-carbon-openai-terra-the-information-report-what-we-know-2026
This article is from the WeChat official account "Machine Heart", author: Machine Heart, published with authorization from 36Kr.