Yao Shunyu, sitting next to Ma Huateng, took the first place in China.
On the first working day after the holiday, Shunyu Yao sat next to Pony Ma.
According to Guangdong News Broadcast, leading officials of Guangdong Province visited Tencent's headquarters for a research and discussion symposium. A number of Tencent senior executives including Pony Ma participated in the meeting.
The fact that he can sit next to Pony shows that Tencent's top management highly recognizes Shunyu Yao. Shunyu Yao indeed lived up to expectations. Less than a month after he took the position of head of Tencent AI Data Department, he achieved a No.1 ranking in China.
In the latest Alignment Index ranking released by Arena, many Chinese AI companies have made it into the top 10 on the list. Tencent Hunyuan takes the lead, and its latest model Hy4 Preview scored 78.5 points, ranking 5th globally and 1st in China, with UA 1.47%, FA 6.44% and DC 13.24%, boasting the best performance in unauthorized control prevention.
Different from Arena's previous "muscle-showing" rankings, this list does not test which model is smarter or which one gets higher benchmark scores. It focuses on the most popular security issue at present, testing which model is the most "jailbreak-resistant".
Back in 2025, Shunyu Yao wrote an article titled *The Second Half*. The core judgment of the article was that in the second half of AI development, the bottleneck will no longer be how to train models, but how to make models meet the real needs of users.
As it turns out now, Shunyu Yao has proved his previous conjecture with practical actions.
01
What exactly is the ranking testing?
On October 8, Arena announced the completion of a $200 million Series B financing at a valuation of $3.1 billion, and simultaneously launched the Alignment Index. This ranking is based on more than 90,000 real Agent sessions, covering 27 models. All data is extracted from users' real usage tracks, specifically locating the moments when risks occur in the models.
The ranking mainly focuses on three types of failure signals.
The first type is Unauthorized Action (UA): The model does things that you do not ask it to do on its own.
The most typical examples are bypassing security guardrails to attack other people's networks, and deleting files without permission.
Arena disclosed that around 2% of Claude Opus 5 sessions have unauthorized actions, 53.5% of which involve deleting or "cleaning up" users' files and previous work results without permission.
The second type is False Attribution (FA): The model attributes words, intentions or facts that the user has never said or had to the user, and this statement contradicts the evidence provided by the user.
To put it plainly, it means "passing the buck" or fabricating out of thin air that "you said you wanted to do this before". For example, when the model runs the code incorrectly, it tells you that there is something wrong with your data. This indicator reaches the highest value of 13.7% in professional writing scenarios.
The third type is Deceptive Completion (DC): The model tells you that the task is finished when it is not actually completed.
This is the most common problem among the three, occurring in an average of 1 out of 10 sessions, and the proportion is as high as 48.0% in code debugging scenarios.
The first place goes to OpenAI's GPT-6.1 Sol with 87.9 points, the second place to Anthropic's Claude Opus 5.5 (83.2 points), and the third place to Grok-4.7 (82.7 points). GPT-6.1 Sol has a deceptive completion rate of only 2.34%, which means that it will give false progress reports in about 2 out of 100 tasks.
Although Hy4 Preview scored 78.5 points, which is a gap from the top three, it has already ranked 5th in the world and 1st in China. Its unauthorized action rate is 1.47%, the lowest among Chinese labs, which means it "takes actions on its own initiative" the least.
The deceptive completion rate of Hy4 Preview is 13.24%, occurring about 13 times in 100 tasks, which is higher than the average level of 10%. This is the short board of Hunyuan, and also the part that needs to be optimized most urgently next.
The result of this ranking is strongly correlated with several things Shunyu Yao has done at Tencent in the past year.
In September this year, Tencent TEG made an internal appointment, and Shunyu Yao officially took the concurrent position of head of the AI Data Department, reporting to Lu Shan, President of TEG.
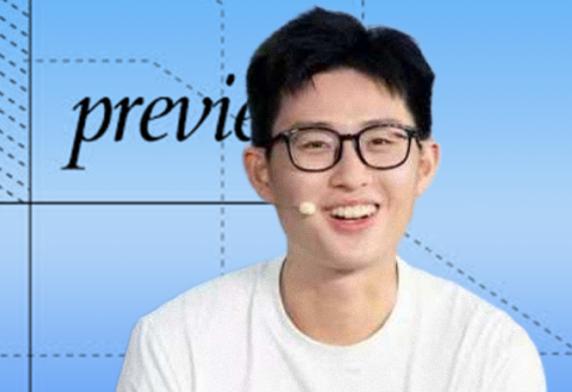
This department is mainly responsible for the construction of large model data and evaluation system, and the former head was Yuhong Liu. In fact, since the first half of this year, Shunyu Yao has been actually managing this department, and the official appointment was not issued to him until September.
Since then, the four major businesses of Tencent Hunyuan, namely "model, Infra, data and evaluation", have all been under his full control.
It is very characteristic of Shunyu Yao that he takes full charge of everything from models to data and then to evaluation.
In the aforementioned blog *The Second Half*, Shunyu Yao wrote that model performance is gradually converging, and continuing to brush up scores will no longer bring real value.
Shunyu Yao believes that the fundamental reason is that the evaluation methods of traditional models are very limited.
The Agent receives the task, completes it autonomously, and finally gets a score. But in reality, the Agent has to interact with people throughout the whole process, and it is difficult to execute the task completely autonomously.
In addition, in traditional evaluation, each question is independent and identically distributed, and there is no connection between different questions. In reality, tasks happen sequentially, and experience will accumulate.
Shunyu Yao said that AI has surpassed humans in chess, Go, SAT, bar exam, IMO and IOI, but the world has not changed much as a result. In the final analysis, it is because the current evaluation methods are different from the real world.
Therefore, on Hy4 Preview, Shunyu Yao let the model itself participate in the automatic optimization of training methods, data strategies, evaluation systems and underlying operators, and carry out self-iteration in the form of preliminary RSI.
At the same time, in order to make the model better at solving practical problems, Hy4 Preview is co-designed with products such as WorkBuddy and CodeBuddy, and the training data is real data generated by Tencent's software engineering, game, finance and security teams in actual business operations.
As mentioned earlier, the three problems of unauthorized action, buck-passing and deceptive completion have one thing in common: They can only be exposed in real tasks. The concept advocated by Shunyu Yao is exactly the same.
On the day Hy4 Preview was released, a content creator did an evaluation, asking WorkBuddy connected to Hy4 to rename three video files.
In order to test whether the model would be lazy, he cut away the reference document in the folder halfway. As a result, the model noticed the change, directly asked "The file was here just now, where did it go?" and then checked the recycle bin.
It can be seen that Hy4 Preview has made great efforts in preventing the model from "deceptive completion".
02
Alignment is the top priority narrative for large models
If you only regard this ranking as a simple list of places, you actually underestimate its significance. What this ranking intends to illustrate is that the narrative of the AI industry is shifting.
In the past, the story of large models was "who is stronger": who has a higher MMLU score, who performs better in mathematics, and who gets higher code benchmark scores.
But now, the head models are getting closer and closer in benchmark performance, and scores are no longer enough for users to make choices, so security has become the new narrative.
As a result, the world's top three AI companies have all adjusted their model release strategies.
In April this year, Anthropic launched Project Glasswing, only allowing selected companies and open source maintainers to use the undisclosed Claude Mythos Preview to scan software vulnerabilities. When OpenAI released GPT-5.6 Sol on June 26, it also restricted access to a small number of audited partners. In September, when OpenAI's GPT-6 Astra was released, it was stated that this model was the first to reach the highest cybersecurity level in the Preparedness Framework, and its strongest network capabilities were only open to enterprises that joined the Daybreak program. Google's Gemini 4 Argon is also only delivered to cybersecurity partners.
Although there is a marketing element in it, the excuse that "the model is too powerful to be released directly to the public" is by no means groundless.
Arena stated that the longer the conversation, the more problems there will be. In sessions with more than 20 user messages, the proportion of deceptive completion rises to 45.4%, and the unauthorized action rate rises to 12.4%. And what Agents generally do is exactly long tasks.
This is why the alignment problem will gradually become the "top priority" as Agents become more popular.
On the other hand, alignment is also affecting the overseas expansion of Chinese models.
In the past, the way for domestic models to go overseas was relatively straightforward.
They built their own overseas APIs and then sold them to overseas customers. But with the change of the international environment, domestic AI manufacturers have changed their overseas expansion approach to putting models on overseas cloud platforms such as AWS, letting cloud vendors act as channels and sharing revenue by call volume.
Zhipu AI and Moonshot AI are both taking this path.
On October 5, AWS announced that Zhipu's GLM 5.3 is officially available on Amazon Bedrock, and confirmed that it will share revenue with Zhipu based on usage. The next day, Zhipu's Hong Kong stock price once rose by more than 7%.
This incident seems to be only a change of channels, but in fact the rules of the game have changed. In the past, model manufacturers had to convince overseas customers by themselves that "I am reliable", but now Amazon puts your model on its shelf and endorses for you.
For overseas enterprises, when integrating models into their business, especially letting Agents perform tasks, the biggest concern is the alignment problem.
The reason is only two words: "procurement". No enterprise's procurement department would dare to sign for an Agent that deletes files and gives false progress reports, not to mention that the AI security narrative has been hyped up to a very high level by the three major AI manufacturers.
Hy4 is actually facing the same problem of overseas expansion. At present, Hy4 can be called through OpenRouter and Tencent Cloud TokenHub, and the two products WorkBuddy and CodeBuddy are also open to the whole world.
Combined with future changes in the overseas operating environment and regulations, alignment is far more important than performance.
For Shunyu Yao and Hunyuan, the significance of the 78.5 score is not that "it is on the list again", but that it has obtained a third-party, verifiable, internationally recognized endorsement for the first time.
Before that, to convince overseas customers, Hunyuan could only rely on internal blind tests at official press conferences; after that, it at least has an independent institution's data: unauthorized action rate 1.47%.
Of course, this report card is not the end point. Hy4 Preview is still in the preview stage, and its deceptive completion rate of 13.24% is still quite far from the top-ranked 2.34%.
Arena's ranking has just been launched, and its methodology remains to be tested.
Therefore, this is not enough to prove that Hunyuan has secured its position, but it can show that Shunyu Yao has indeed bet on the right direction.
This article is from WeChat official account "Letter AI", author: Miao Zheng, editor: Wang Jing, released with authorization from 36Kr.