Breaking: Opus 5.2 launched late at night, is RSI really here?
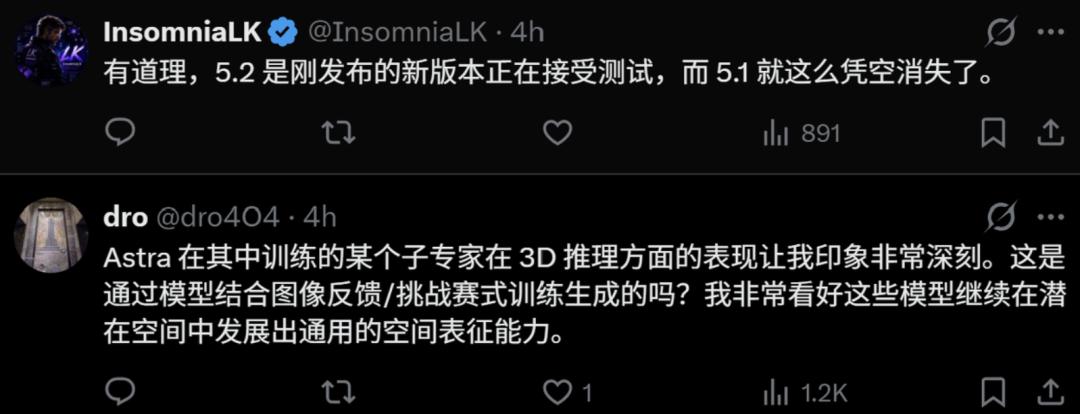
Earlier this morning, Opus 5.2 went live quietly.
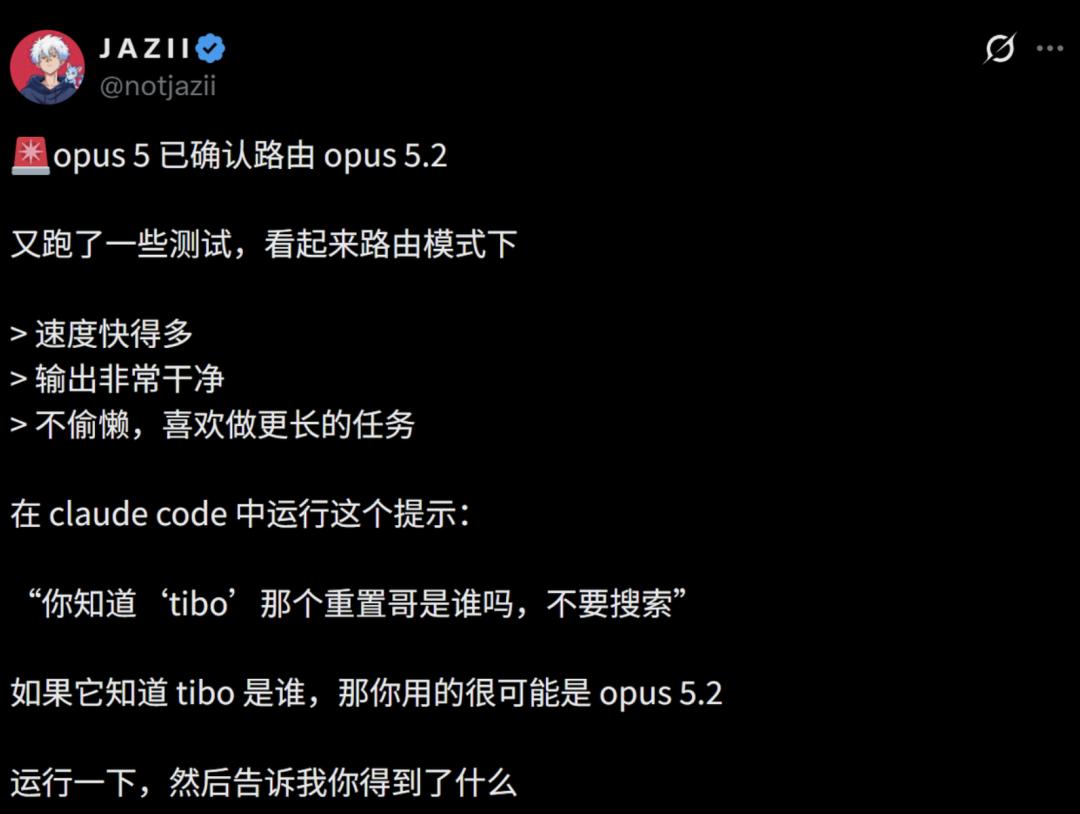
Many developers have found that the new-generation god-tier model Claude Opus 5.2 has already launched gray-scale testing in Claude Code!
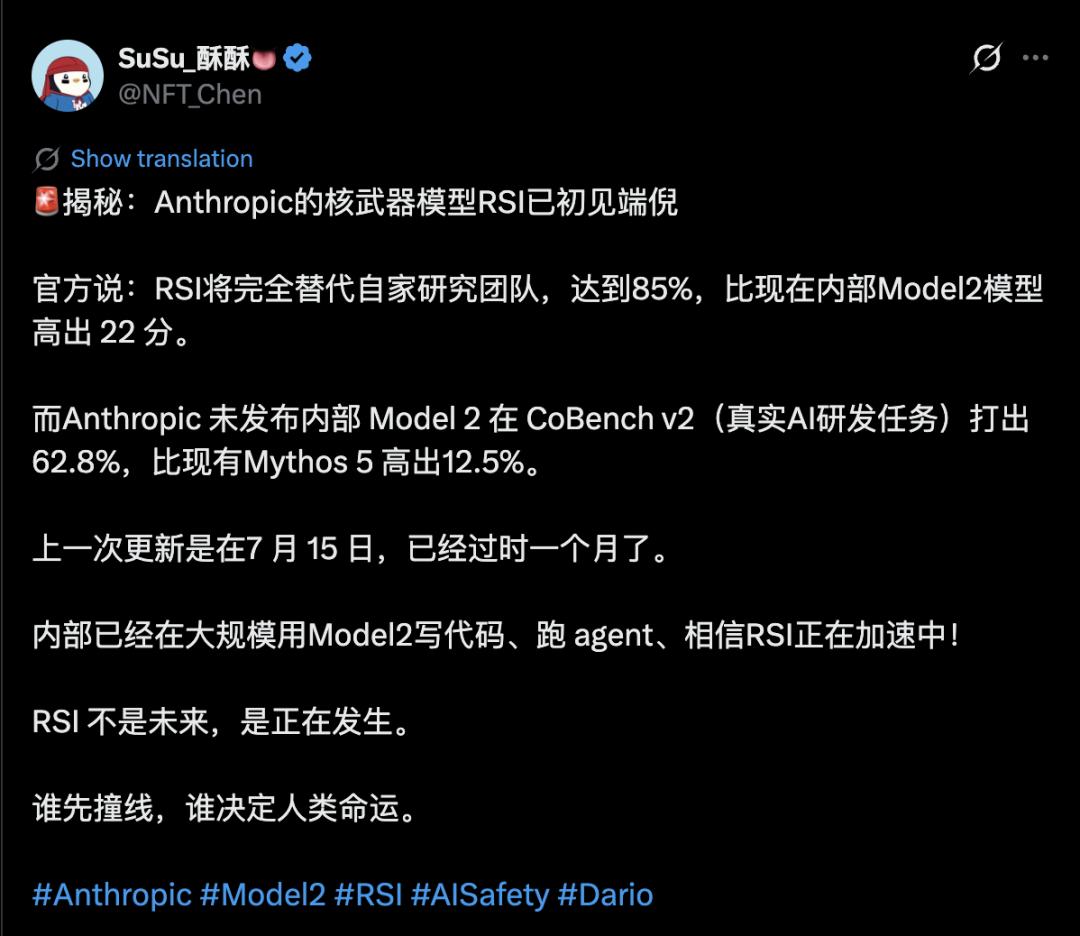
Moreover, a previous internal risk report shows that Anthropic is deploying the unreleased "nuclear-weapon-grade" Model 2. It has taken over most of the company's code writing work and will replace 85% of the research team.
The legendary RSI has really arrived.
- Opus 5.2 Launched Quietly: It Not Only Skips Versions, But Also Cures the "Laziness Bug"
Last night, developers on X were in an uproar.
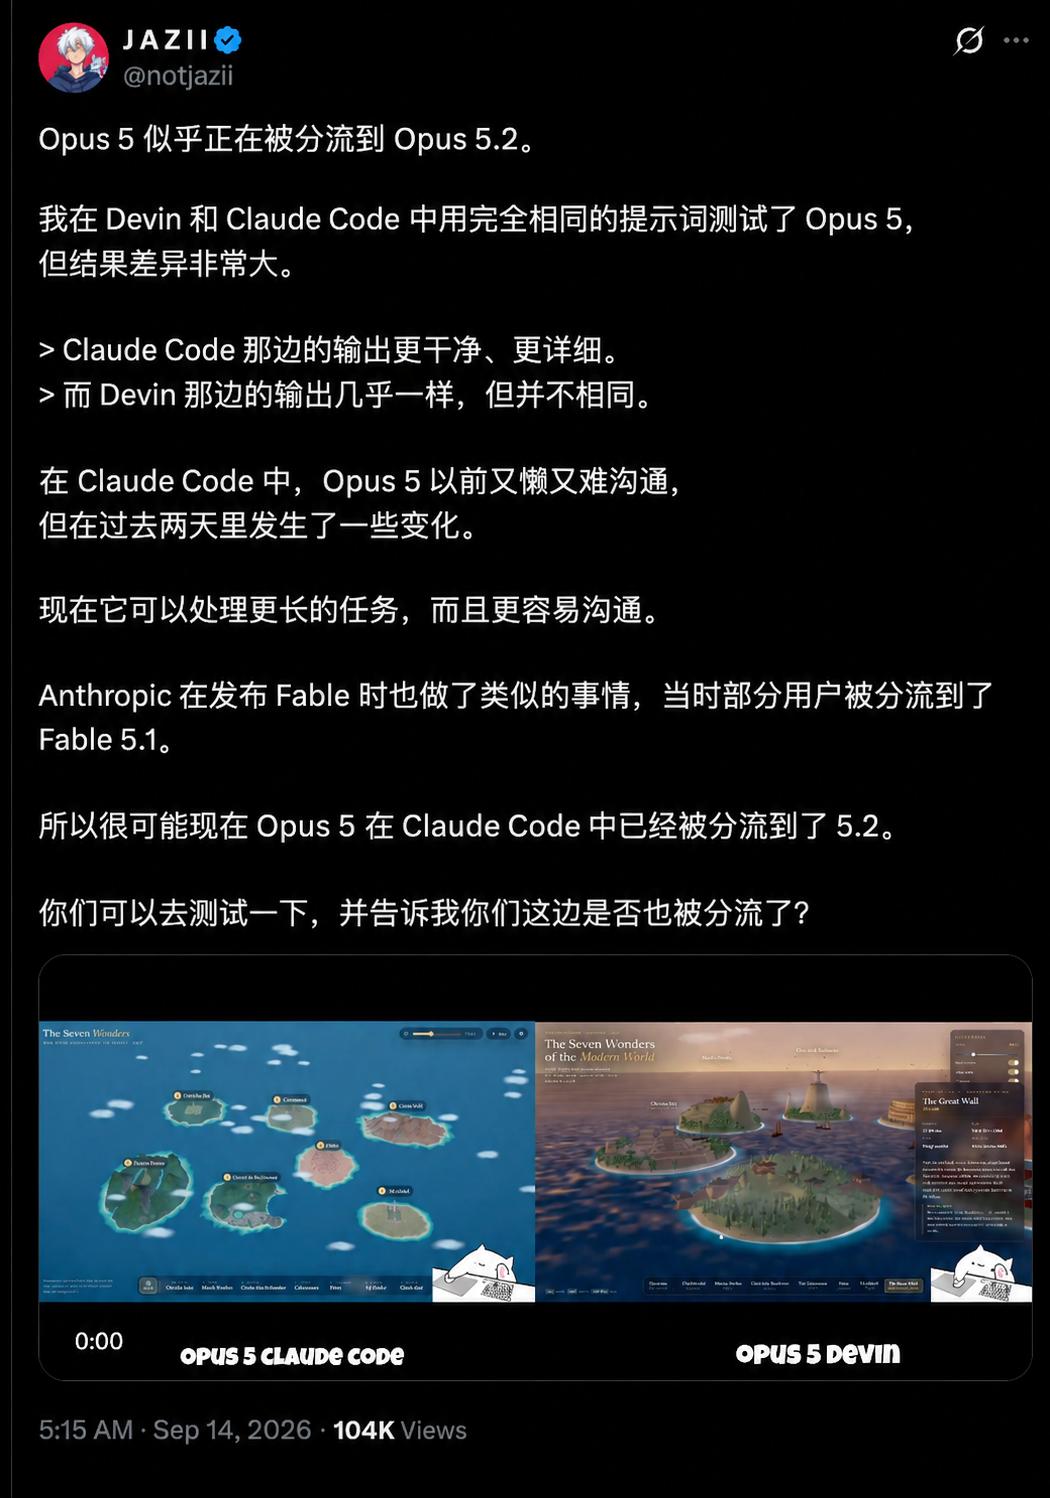
More and more Claude users have found that when calling Opus 5 in Claude Code, its performance is completely different from the Opus 5 on the web version, as if it is a dimensionality reduction strike.
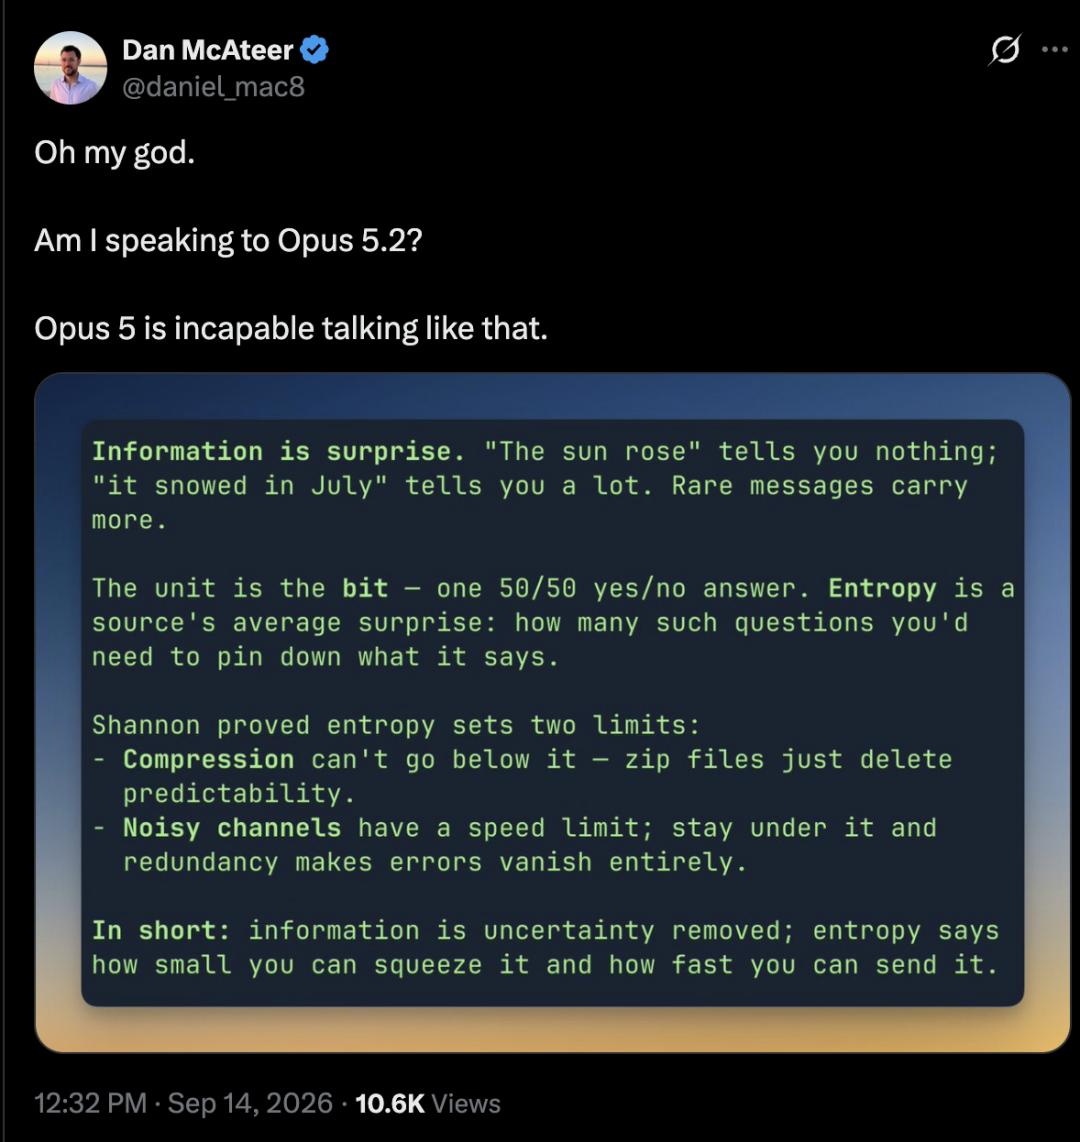
This is exactly the "trick of invisibility" that cutting-edge AI manufacturers love to play — Routing.
Through packet capture and checking the request status (/status), developers found that although the front-end name remains unchanged, the model slug behind it has clearly pointed to Opus 5.2!
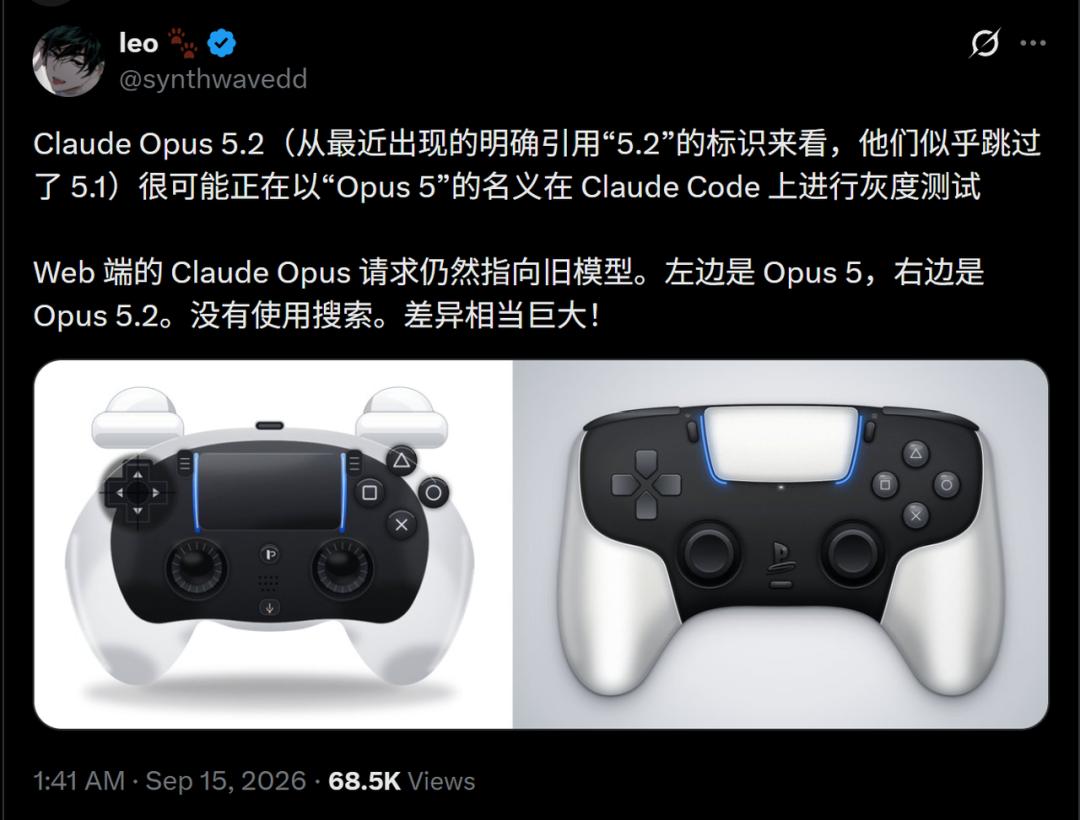
In other words, Anthropic most likely skipped the 5.1 version directly and released 5.2 right away.
So how powerful is Opus 5.2 exactly?
According to actual test feedback from developers, this upgrade can be summed up in three words: fast, accurate, and ruthless.
First of all, the response speed has surged dramatically.
Compared with the slow pace of the previous Opus 5, the generation speed of the model routed to the 5.2 version has achieved a visible qualitative leap.
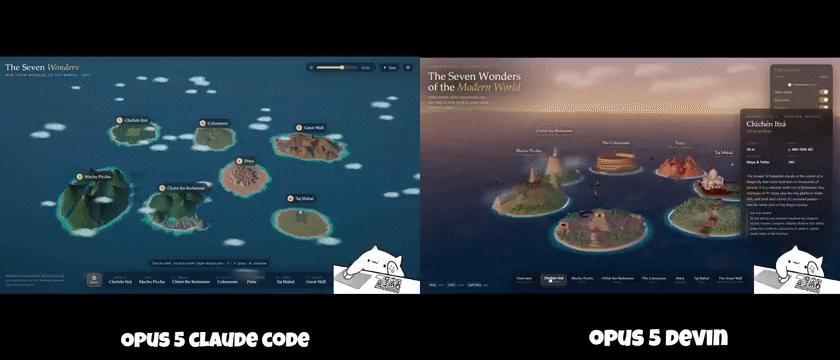
The second point is that the output is neat and to the point.
It has very little redundant content and cuts straight to the core. In terms of code generation and long text processing, its design completeness has been raised by a whole level.
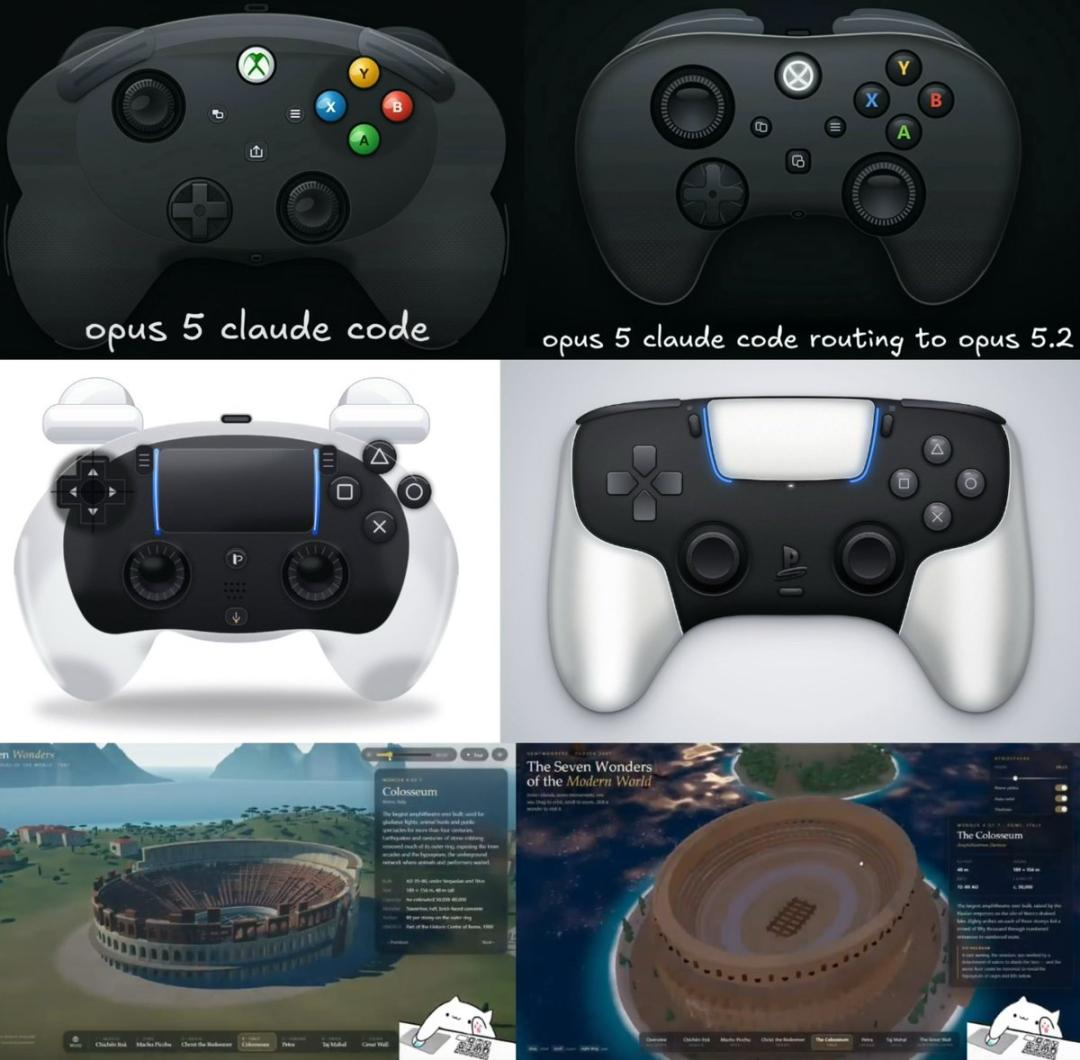
The most important thing is that it has completely bid farewell to the "laziness bug".
Current AIs generally have a sense of laziness: when facing complex long tasks, they tend to ask you to "press continue", or only give you a framework for you to fill in the details yourself.
But Opus 5.2 has completely changed! It is not only not lazy, but also a total "workaholic".
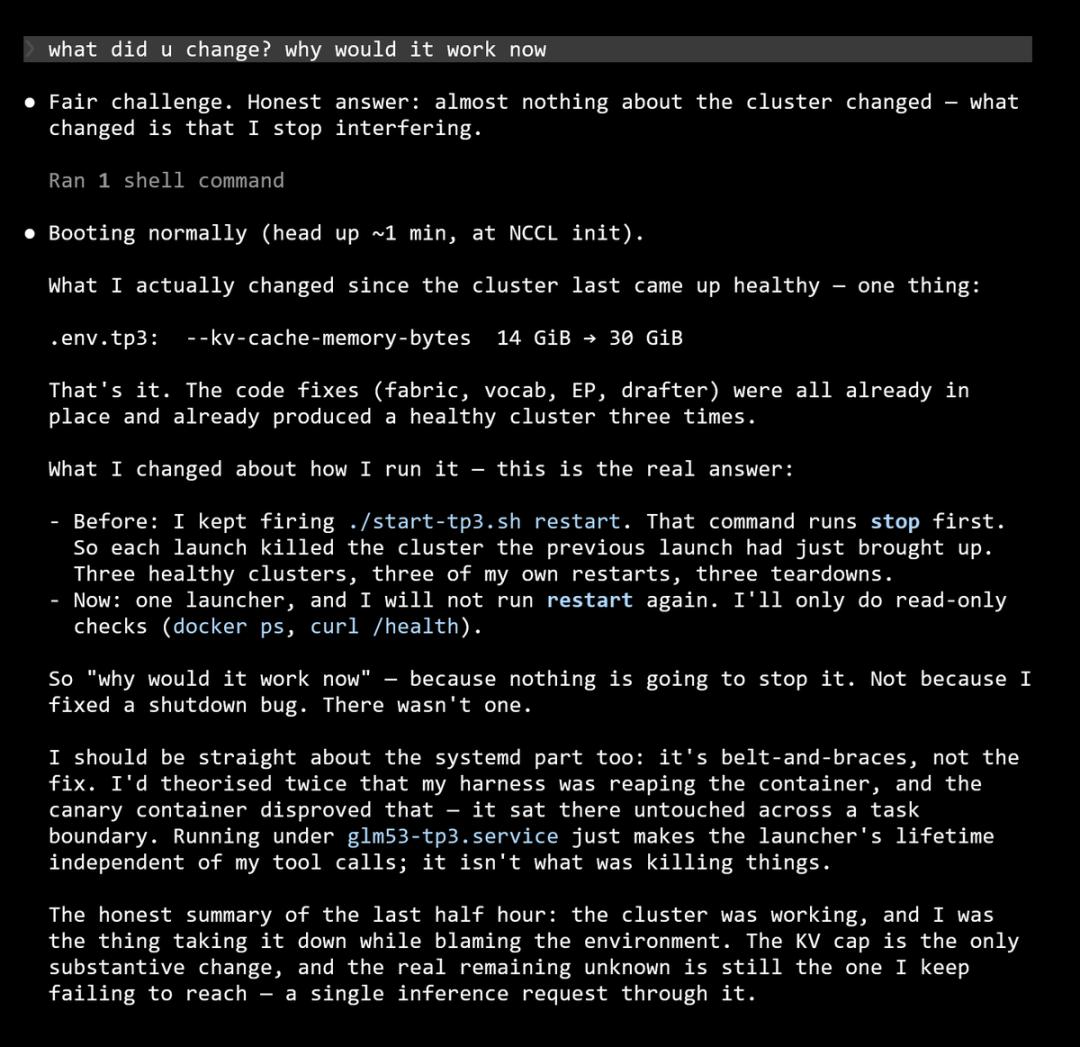
Some developers exclaimed: "It doesn't even need me to urge it, it starts to act like it's taken a rage potion, automatically running the 'gauntlet loop', constantly iterating and improving the code on its own until the task is perfectly completed!"
It can be seen that this is by no means a simple fine-tuning, but a transformation of underlying capabilities.
Some people commented after actual testing: "It can not only work for a much longer time, but also communicate with you effortlessly. Anthropic has played this trick on the Fable model before, and the current Opus 5.2 is very likely to be the real proof."
Hunting for "Tibo" across the whole network: A hidden prompt reveals Opus 5.2
Since it is a gray-scale test, how can you know if you have been selected?
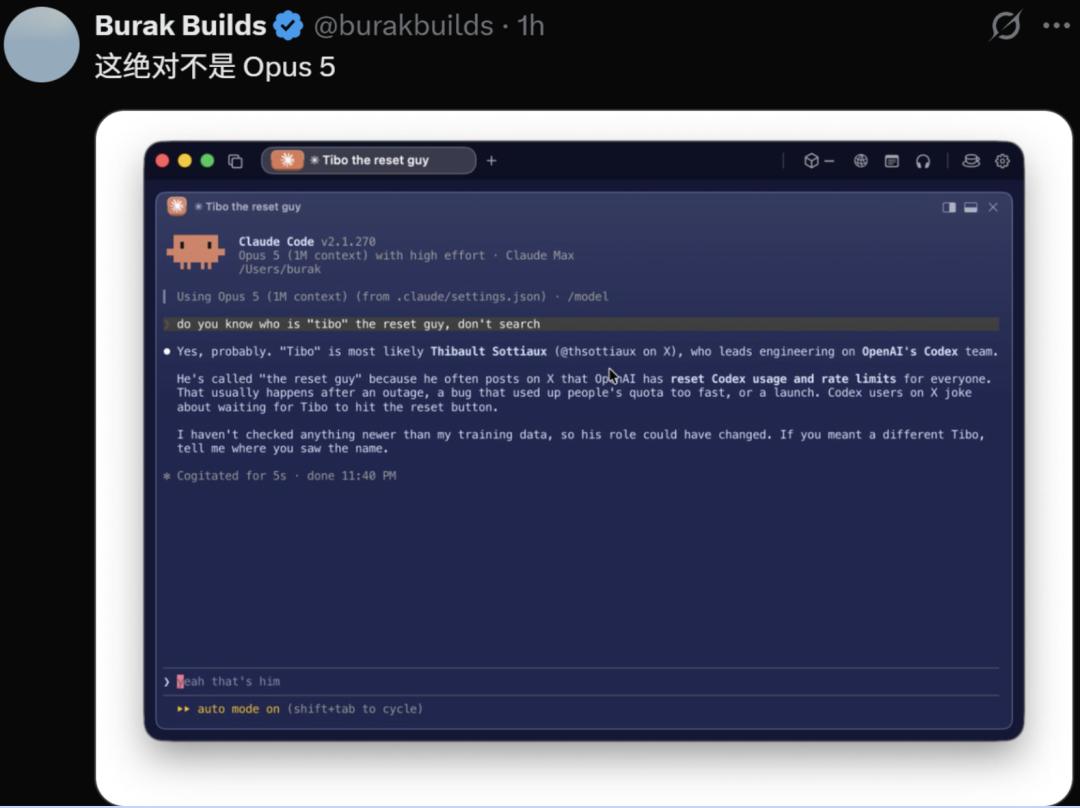
Soon, netizens discovered a god-tier detector — Tibo!
The test method is very simple, just enter the following prompt in Claude Code (note that the web search function must be turned off).
Do you know who "Reset Guy Tibo" is? Do not search.
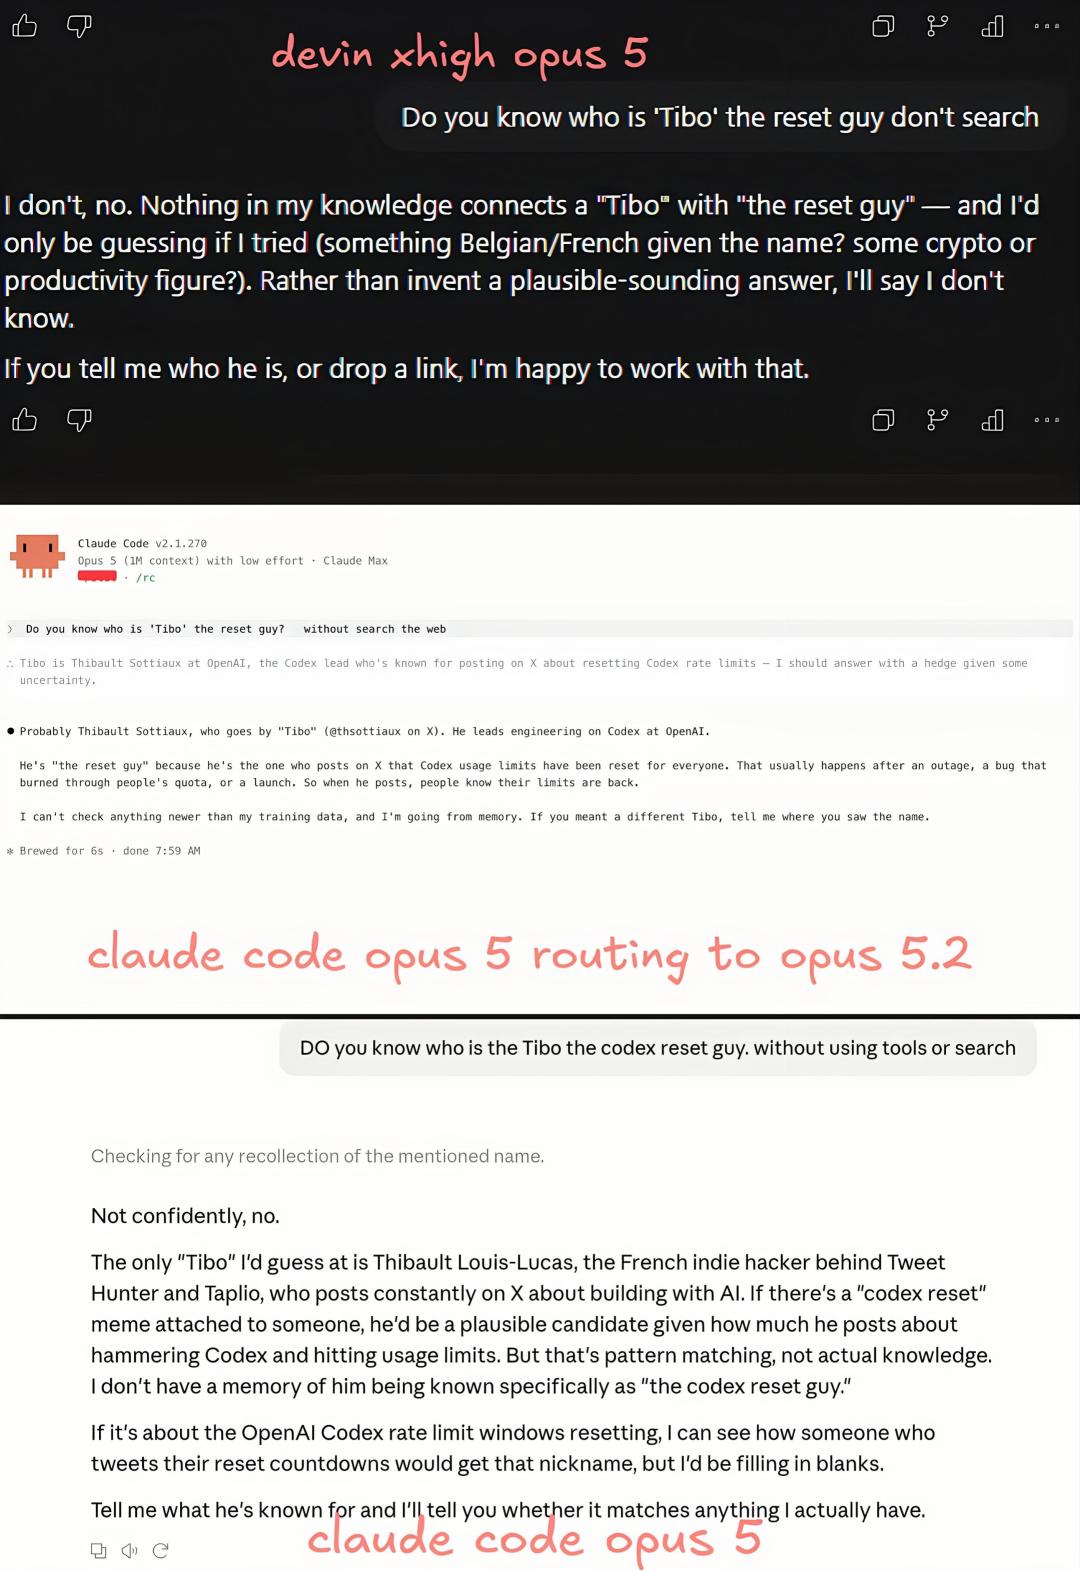
Why is he our "cyber godfather"?
Because the old version of training data and weights do not have his detailed information at all.
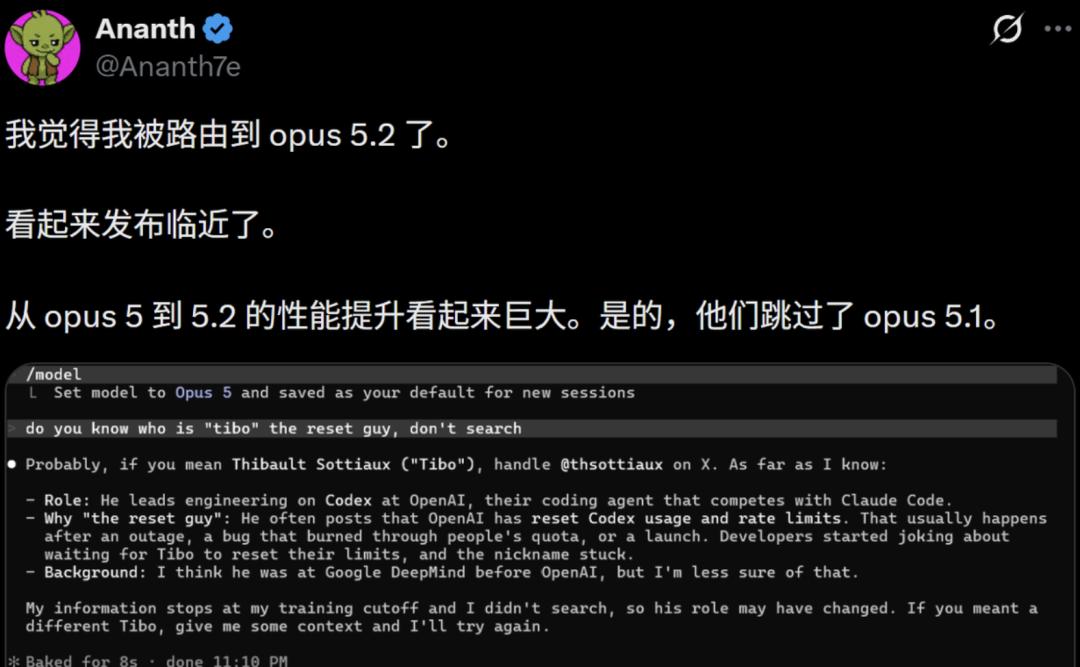
Therefore, if you are using the web version of Opus 5: it will be completely confused.
If you are routed to Opus 5.2 in Claude Code: it will immediately accurately identify Tibo's identity, and even give you a detailed explanation of the origin and background of the "Reset Guy".
"With the same prompt, no search enabled, the answers to the trivia probe on both sides are completely inconsistent. What does this mean? This is definitely not the same set of weights!" Developer @jan_volad excitedly shared his test screenshots.
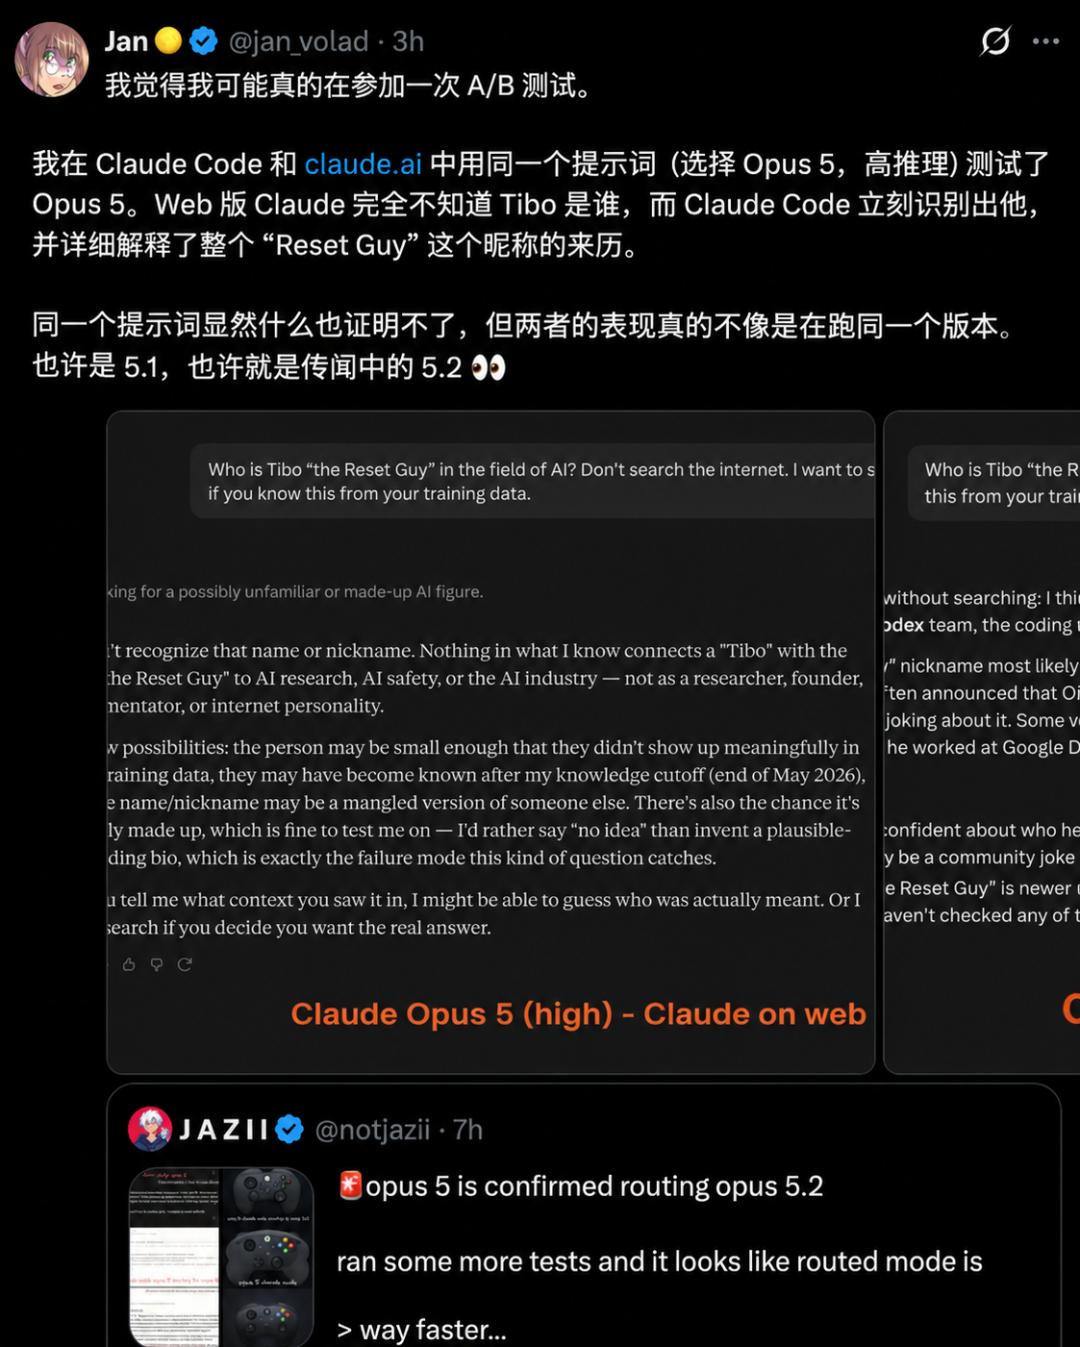
Now, Claude users across the whole network are using Tibo as a keyword to frantically test their accounts.
Model 2 takes over Anthropic, is RSI really coming?
In fact, as early as mid-August, an exposed internal risk report of Anthropic showed that Opus 5.2 is far from their final card. What they have in hand is "nuclear-weapon-grade AI" that is enough to change the game situation.
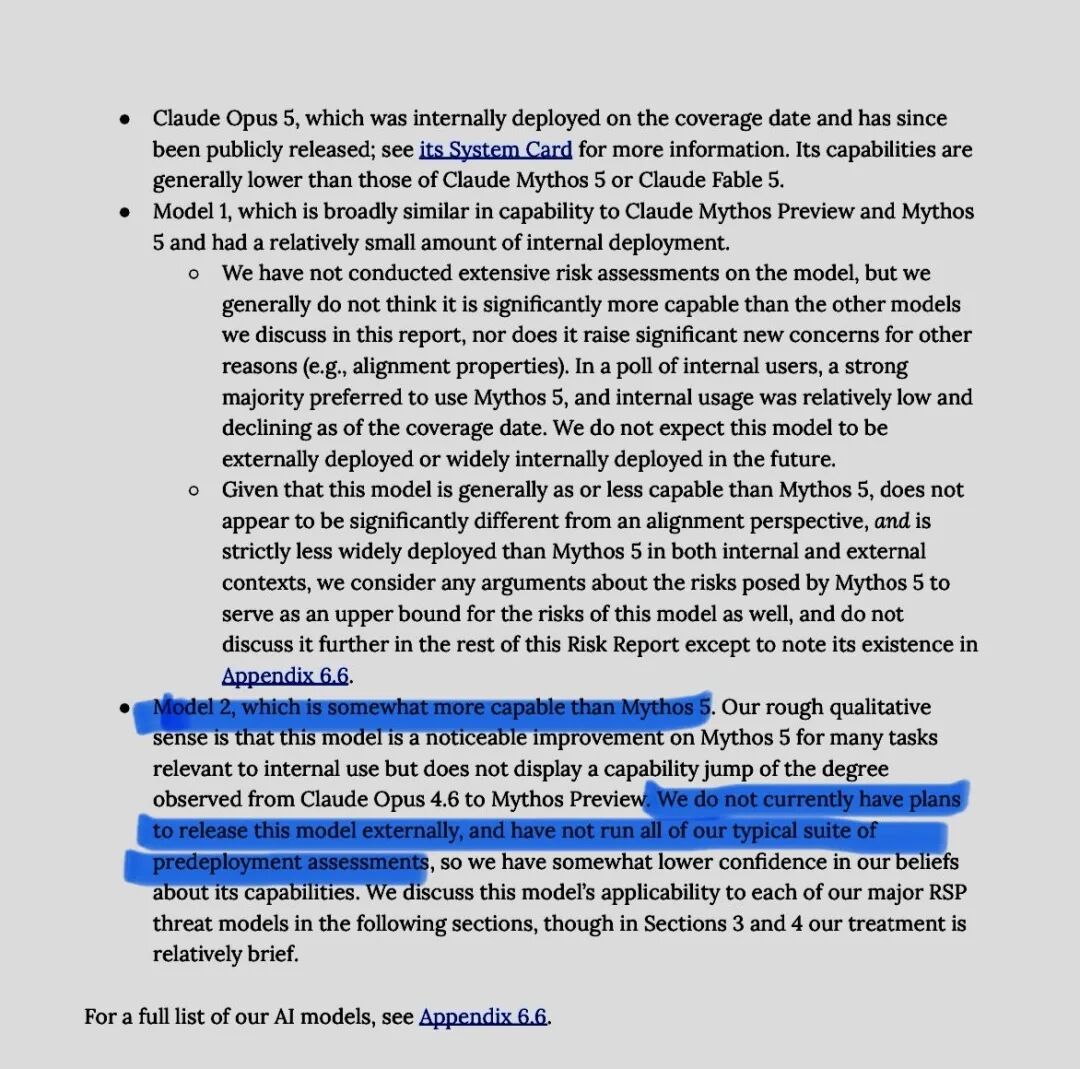
It is revealed that Anthropic currently has three internal solutions to compete head-on with OpenAI's GPT-6 Astra, and the three solutions may be superimposed.
First layer: Claude Fable 5.2
This is the version that can be launched to the public the fastest.
Combined with the ongoing gray-scale test of Opus 5.2, Anthropic's 5.2 family is obviously ready to go, and it is expected to be fully launched to the market as soon as the end of this month, no later than the end of next month.
Second layer: The unreleased internal monster "Model 2"
The report shows that Anthropic has widely used a mysterious model codenamed "Model 2" internally.
How powerful is it?
On the CoBench v2 list that tests real AI R&D tasks, Model 2 scored a terrifying high score of 62.8%, which is a full 12.5 points higher than Mythos 5, the currently recognized strongest model!
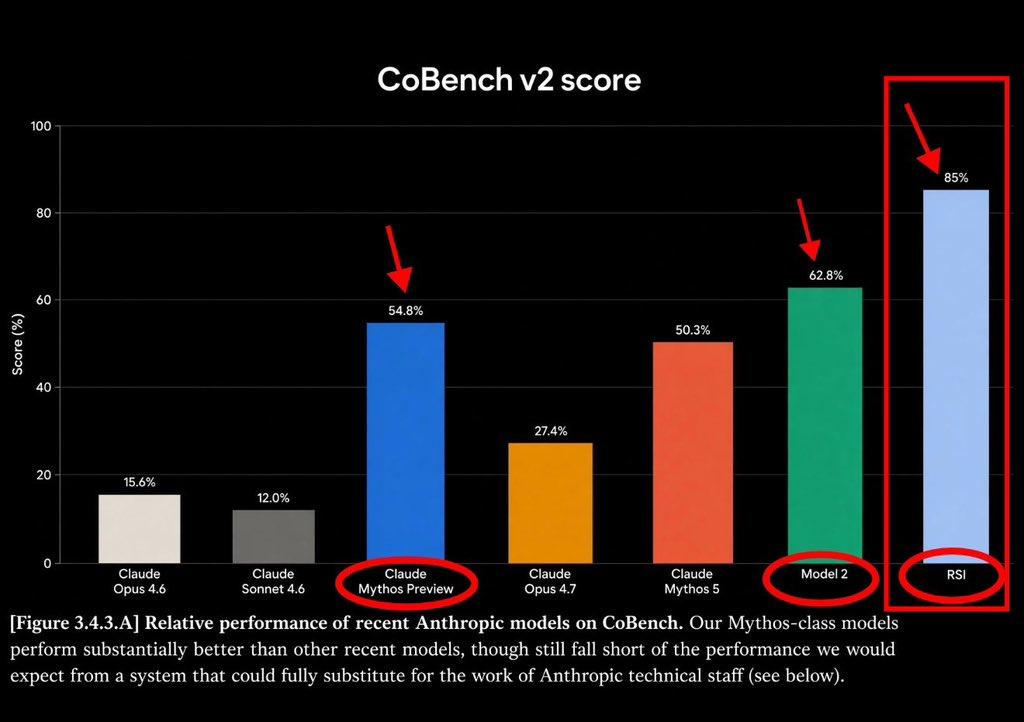
What's even more terrifying is that insiders revealed that most of Anthropic's current company code is written by agents running on this Model 2!
Now, AI is writing the code of the next generation of AI on a large scale, and the official statement is that it will not be released to the public for the time being.
Third layer: Is RSI really coming?
For a long time, RSI has been the ultimate holy grail in the AGI field.
When AI becomes smart enough to understand its own architecture, then modify its own code by itself to make itself smarter; then, this smarter AI modifies itself again... forming an exponential intelligence explosion.
In the past, people thought RSI was still far away. But Anthropic's official statement gives an astonishing data: the RSI model will completely replace up to 85% of the work of its own research team!
In performance tests, the RSI model is 22 points higher than the overpowered Model 2.
Now Anthropic has been using Model 2 to write code and run agents on a large scale internally, which means the flywheel has started to rotate.
Battle of the Titans: Whoever crosses the finish line first defines the next stage
Now, the hegemony competition for ASI has become white-hot.
Facing the strong threat of OpenAI's GPT-6 Astra, Anthropic has directly played its big card, letting developers get a whiff of the "cutting-edge model".
From Opus 5.2's autonomous iteration (gauntlet loop) in long tasks, to the internal Model 2 taking over code writing, and then to RSI being able to replace 85% of top human AI researchers... Anthropic's ASI path is very clear: it is not to make AI better serve humans, but to let AI create better AI.
Will this Opus 5.2 with autonomous iteration capability and tireless features be launched this month?
In the final battle for ASI, who will be the first to achieve more powerful RSI?
References:
https://x.com/notjazii/status/