The latest exposure of GLM-5.5 shows that three reset cards for the "intelligence degradation" issue are already in place.
Is GLM-5.5 really coming soon?!
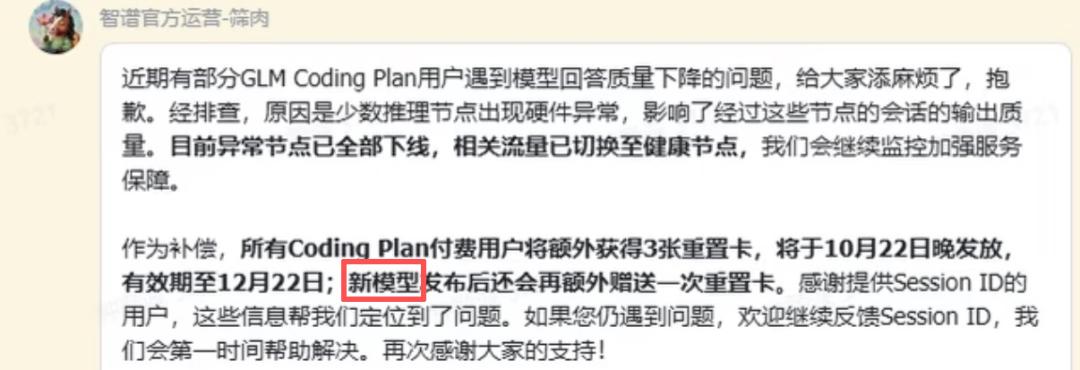
Recently, some users of the GLM Coding Plan have received official compensation notifications, as part of the users previously encountered the "intelligence degradation" issue of the model.
But what is more noteworthy than the compensation itself is a sentence left by Zhipu AI in the announcement ——
After the new model is released, you will get an additional free quota reset opportunity!
Wow, a compensation notification accidentally spoiled the next-generation model. (doge)
Coincidentally, recent revelations about GLM-5.5 have been popping up one after another.
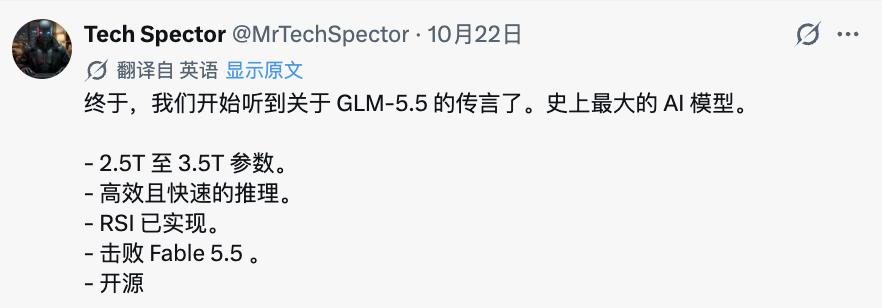
Unconfirmed sources claim that the parameter scale of GLM-5.5 may reach 2.5 trillion to 3.5 trillion, which is much larger than the previously rumored 1.6 trillion!
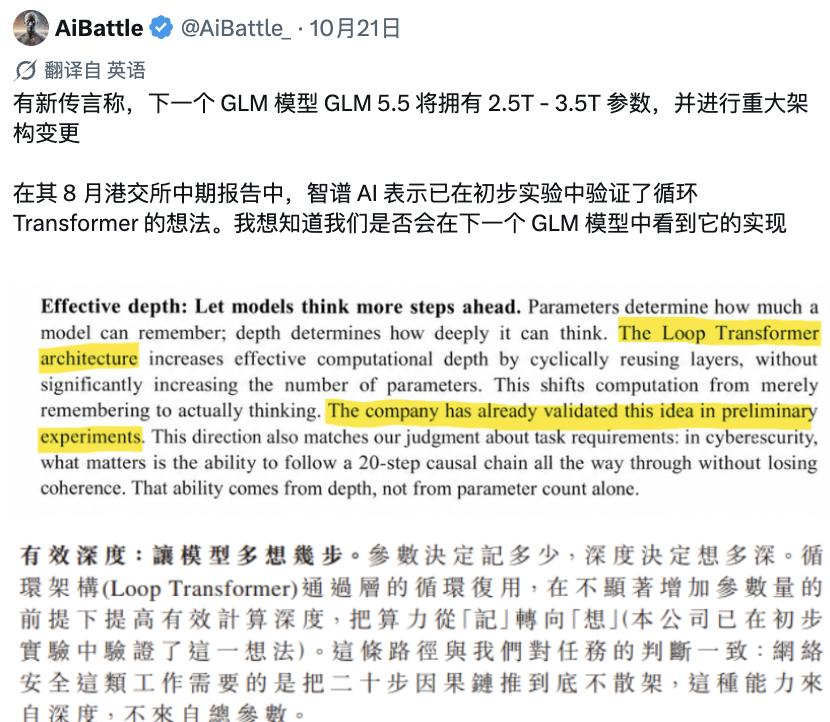
Some netizens also speculate whether the recurrent Transformer architecture that Zhipu AI has initially verified before will be applied to the next-generation GLM???
So... the number of parameters may reach trillions, and the deep reasoning capability is expected to reach a new level? (Not sure if it's real or not.jpg)
Extremely looking forward to it, times 100000.
The official revealed the "new model" in advance, is GLM-5.5... coming?
Although the official has not disclosed specific information about the next-generation model, following the recent rumors, we can really find some traces of GLM-5.5!
First, let's talk about the "parameter scale" that everyone is very concerned about.
It is known that GLM-5.3 released in August this year has a total parameter count of about 743 billion and adopts the MoE (Mixture of Experts) architecture.
However, according to the current online speculation about the total parameter scale of the next-generation GLM, the parameter scale of the next-generation GLM may directly surge to 2.5 trillion to 3.5 trillion.
emm... I counted with my fingers, if this is true, then ——
It will directly expand to about 3.4 to 4.7 times that of GLM-5.3??! (Is this real or not.jpg)
Of course, there is a key point that needs to be emphasized ——
For MoE models, the total number of parameters and the number of parameters actually activated in each reasoning process are completely different concepts.
For example, an MoE model with trillions of parameters usually only calls part of the expert network to participate in the calculation when processing each Token.
Therefore, the sharp increase in parameter scale does not mean that the reasoning calculation amount will grow at the same multiple.
Even so, if the online rumors are true, this still means that Zhipu AI is preparing to carry out a quite next-level expansion in model capacity~
Moreover, simply making the model larger is far from enough.
After some research, another interesting rumor about the new next-generation model is that GLM-5.5 may usher in a major architecture upgrade.
This matter actually has traces to follow.
In August this year, when Zhipu AI released GLM-5.3-Flash, it had already carried out a major overhaul of the underlying architecture of the model.
The most noteworthy part is that it introduced a hybrid architecture combining linear attention and sparse attention for the first time in the GLM series, and adopted mHC technology to improve the internal information transmission and training stability of the model.
With this set of combined optimizations, GLM-5.3-Flash outperforms GLM-5.2 in multiple evaluation benchmarks, while the reasoning price is reduced to about one tenth of the latter.
In other words, Zhipu AI has verified a new route that balances model capability and reasoning efficiency in the previous generation of models.
If this architecture can be further scaled to the trillion-parameter level, the next-generation GLM will have the opportunity to continue to reduce reasoning costs while expanding model capacity.
The model is getting larger and larger, and the operating cost still has the opportunity to continue to decrease.
Who wouldn't look forward to this?! (doge)
It may also be empowered by... Recurrent Transformer???
In addition to the parameter scale and underlying architecture, there is another notable speculation in everyone's discussion about GLM-5.5 ——
Will the Recurrent Transformer also be applied to the next-generation GLM?
Coincidentally, Zhipu AI has indeed publicly mentioned this technology before.
In August this year, Zhipu AI clearly introduced the Recurrent Transformer in its mid-term report, and revealed that it has verified the relevant ideas in preliminary experiments.
Its core goal is to enable AI to "think deeper".
In simple terms ——
The Recurrent Transformer allows the model to repeatedly call the same set of network layers, complete more rounds of internal calculation without significantly increasing the number of parameters, thereby improving the effective reasoning depth.
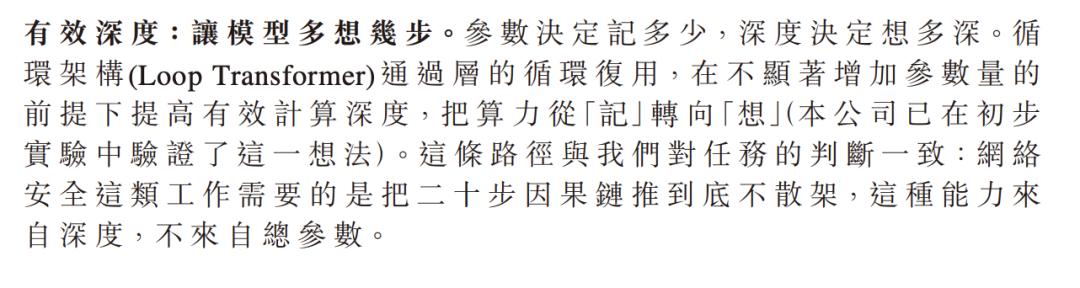
According to Zhipu AI's judgment, the parameter scale determines how much information the model can store, while the calculation depth determines how complex reasoning the model can perform.
Especially in complex tasks such as programming and cybersecurity, the model often needs to continuously complete more than ten or even dozens of steps of judgment to get the correct result.
Once a certain link in the middle goes wrong, the subsequent tasks may all go off track!!
Zhipu AI even gave a "specific example" in the report ——
Cybersecurity tasks may require the model to perform continuous reasoning along a causal chain of up to 20 steps, and each step must maintain logical consistency.
The direction explored by the Recurrent Transformer is exactly to enable the model to perform continuous reasoning along complex causal chains and improve the processing capability of multi-step tasks.
This mechanism also allows the model to increase the calculation depth without significantly increasing the number of parameters, which is equivalent to providing another capability expansion path for complex tasks.
However, the increase in the number of loops will also bring additional computational overhead. How to balance the reasoning depth and operating efficiency is still a problem that needs to be solved.
As for whether this technology will be applied to GLM-5.5, there is no official confirmation yet.
But putting these clues together, the technical upgrade of the next-generation GLM is quite worth looking forward to~
Looking back at Zhipu AI's model upgrade path this year, we can actually see a quite clear capability evolution route ——
In February this year, GLM-5 was released.
In April, GLM-5.1 followed up.
In June, GLM-5.2 was launched, focusing on improving the capability of complex tasks and long-duration Agent execution.
In August, GLM-5.3 was released, which further strengthened the programming capability. Then GLM-5.3-Flash was unveiled, starting new explorations in model architecture and reasoning efficiency.
From this iteration route, Zhipu AI has indeed been continuously upgrading around programming, Agent, deep reasoning and reasoning efficiency~
If GLM-5.5 can really continue to make breakthroughs in these directions, the upgrade of the next-generation flagship model may really be well worth looking forward to.
Waiting for it eagerly!! (rubbing hands.jpg)
Reference links:
[1]https://x.com/teortaxesTex/status/2113073759359811767
[2]https://x.com/ai_funss/status/2112902395365933107
This article is from the WeChat official account QbitAI, author: Meng Yao, authorized for release by 36Kr.